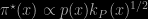Archive for control variates

Monte Carlo with infinite variances [a surveyal guide]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on January 14, 2026 by xi'an

Watch out!, Reiichiro Kawai has just published a survey on infinite variance Monte Carlo methods in Probability Surveys, which is most welcomed as this issue is customarily ignored by both the literature and the practitioners. Radford Neal‘s warning about the dangers of using the harmonic mean estimator of the evidence (as in Newton and Raftery 1996) is an illustration that remains pertinent to this day. In that sense, the survey relates to specific, earlier if recent attempts, such as Chatterjee and Diaconis (2015) or Vehtari et al (2015), with its Pareto correction.

In its recapitulation of the basics of Monte Carlo (closely corresponding to my own introduction of the topic in undergraduate classes), the paper indicates that the consistency of the variance estimator is enough to replace the true variance with its estimator and maintain the CLT. I have often if vaguely wondered at the impact (if any) a variance estimator with (itself) an infinite variance would have. A note to this effect appears at the end of Section 1.2. While being involved from the start, importance sampling has to wait till section 3.2 to be formally introduced. It is also interesting to note that the original result on the optimal importance variance being zero when the integrand is always positive (or negative) is extended here, by noting that a zero variance estimator can always be found by breaking the integrand f into its positive and negative parts, and using now two single samples for the respective integrals. I thus find Example 6 rather unhelpful, even though the entire literature contains such examples with no added value of formal optimal importance samplers. A comment at the end of Example 6 is opens the door to a short discussion of reparametrisation in simulation, a topic rarely discussed in the literature. The use of Rao-Blackwellization as a variance reduction technique that is open to switching from infinite to finite variance, is emphasised as well in Section 2.1.

In relation with a recent musing of mine during a seminar in Warwick, the novel part in the survey on the limited usefulness of control variate is of interest, even though one could predict that linear regression is not doing very well in infinite variance environments. Examples 8 and 9 are most helpful in this respect. It is similarly revealing if unsurprising that basic antithetic variables do not help. The warning about detecting or failing to detect infinite variance situations is well-received.

While theoretically correct, the final section about truncation limit is more exploratory, in that truncation can produce biased answers, whose magnitude is not assessed within the experiment.

finite variance goals

Posted in Books, Statistics, Travel, University life with tags , , , , , , , , , , on November 8, 2025 by xi'an

During Johan Seger’s seminar in Warwick, on the control variate improvements he developed with Rémi Leluc (which PhD thesis committee I joined), Aymeric Dieuleveut, François Portier, and Aigerim Zhuman, I started wondering at whether or not a control variate could turn an infinite variance Monte Carlo estimate into a finite variance one. And asked… ChatGPT about it, with the above reply that is correct if not practical in the least since the example provided therein was reverse-engineering an infinite variance rv into a sum of an infinite variance rv considered as the control variate and a finite variance rv. As summarised below. In practice, this would mean replacing the integrand of interest with a much simpler integrand that shares the same asymptotic behaviour, not an easy task! (As an aside, I found out that enabling MathJax on this ‘Og would cost me $40 a month!)

5. Summary

✅ Theoretical possibility:
Yes — control variates can make an infinite-variance estimator finite, but only if the control’s sample path shares the same tail driver and its expectation is known.infinite variance rv
In real-world Monte Carlo, when X is heavy-tailed, you usually:

  1. Split X = Y + (X-Y), where Y has known expectation and similar tails,

  2. Use Y as control variate, and

  3. Possibly combine with truncation, conditional expectation, or importance sampling for stability.

coupling-based approach to f-divergences diagnostics for MCMC

Posted in Books, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , on October 27, 2025 by xi'an

Adrien Corenflos (University of Warwick) and Hai-Dang Dau (NUS) just arXived their paper on MCMC diagnostics that Adrien told me about last month, while in Warwick.

“This [f-divergence] bound is clearly suboptimal since it does not vary in t and does not take into account the mixing of the Markov chain. We present a scheme where the weights are ‘harmonized’ as the Markov chain progresses, reflecting its mixing through the notion of coupling.”

They start by opposing the classical ergodic average and embarrassingly parallel estimates obtained by N parallel chains culled of their B initial values, to couplings used in standard diagnoses. Opting for the parallel perspective, maybe rekindling the diagnostic war of the early 1990s! The evaluation tool in the paper is based on f-divergences, like the χ² divergence which naturally relates to the effective sample size when considering weighted atomic measures. When consistent, these weighted approximations produce upper bounds on the f-divergence, with exact convergence in case of independence.

In my opinion the most exciting part of the paper stands with the ability to modify these weights along MCMC iterations, since the naïve sequential importance sampling argument I also use in class keeps them constant! The trick is to (be able to) couple randomly chosen parallel chains, with the weights being averaged at each coupling event. The resulting algorithm preserves expectation (in the importance sampling sense) and consistency (in the particle sense). Furthermore, the f-divergence bound based on the weights can only decrease between iterations, which reminds me of interleaving. And exponential convergence of the weights to uniform ones (under the strong assumption of a uniformly lower bounded probability of coupling). The paper concludes with interesting remarks on perfect sampling, Rao-Blackwellisation, control variates, and backward sampling.

A long-standing gap exists between the theoretical analysis of Markov chain Monte Carlo convergence, which is often based on statistical divergences, and the diagnostics used in practice. We introduce the first general convergence diagnostics for Markov chain Monte Carlo based on any f χ² -divergence, allowing users to directly monitor, among others, the Kullback–Leibler and the divergences as well as the Hellinger and the total variation distances. Our first key contribution is a coupling-based ‘weight harmonization’ scheme that produces a direct, computable, and consistent weighting of interacting Markov chains with respect to their target distribution. The second key contribution is to show how such consistent weightings of empirical measures can be used to provide upper bounds to f -divergences in general. We prove that these bounds are guaranteed to tighten over time and converge to zero as the chains approach stationarity, providing a concrete diagnostic.

R[are]SS meeting

Posted in Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , on September 29, 2024 by xi'an


Yesterday, I happened to be at the right time in the right place, as I was in Warwick for a RSS local section meeting on rare event simulation. (If missing the aurora borealis and the moon eclipse on previous nights!) And hence attended a seminar by Francesca Crucinio in six days!, as she talked about a turnkey approach to unbiased estimation of transforms of a moment, or wlog a mean μ, f(μ). A recent article with Nicolas Chopin (CREST) and Sumeet Singh, where they resort to Taylor expansions to achieve unbiasedness, using the Russian roulette trick to stop the summation from running to infinity. (As it happens, I heard Nicolas talk about this idea in the recent past namely at the ISBA-Fusion Sunday morn at Ca’Foscari.) Using a Taylor expansion is obviously natural and mathematically correct, albeit fraught with potential dangers [imho]:

  • the Taylor expansion involves central moments up to a random order R, which are harder & harder to estimate with increasing orders (i.e., more & more uncertain, with the possibility of infinite variance estimators after a certain order)
  • I did not spot a discussion on the moment estimators, that seems to rely on k iid replicas for the k-th moment
  • a lot of calibration ensues, from the choice of the centre x⁰ to the (artificial) distribution of the stopping value R, to the parameterisation of the random variable attached to the moment μ
  • the paper insists on recycling simulations to stabilise the moment estimators and ensure consistency, as a primary level of Rao-Blackwellisation, but this only applies to the smallest order moments and could be devised in many different ways, with varying computing costs
  • consistency of the estimate is not necessarily needed, as for instance for pseudo-marginal applications
  • as often with Russian roulette, positive quantities may receive negative estimations that are dominated by truncations to the positive real line (and alternating series offer the use of sandwiching estimators)
  • for the above reason, it is not always reasonable to tunnel vision on unbiasedness and alternative estimates like bridge sampling solutions could be integrating towards improving the quality of the estimator (especially since the conditions for finite variance involve unknown quantities)
  • while f-Taylored solutions like harmonic mean estimators for f(x)=1/x are not necessarily a panacea, they could be included in the comparison or as control variates

The first talk by Mathias Rousset was investigating adaptive multilevel sampling, a form of nested sampler, at the theoretical level, while the third talk by Tobias Grafke was a repetition of a talk he gave at the masterclass the interface between computational physics and computational statistics, last April.

optimal importance sampling

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , on May 31, 2023 by xi'an

In Stein Π-Importance Sampling, Congye Wang et al. (mostly from Newcastle, UK) build an MCMC scheme with invariant distribution Π targeting a distribution P, showing that the optimal solution (in terms of a discrepancy) differs from P when the chain is Stein-sampled, e..g. via kernel discrepancies. In terms of densities, the solution is

\pi^\star(x)\propto p(x)k_P(x)^{1/2}

the correction involving the root of a Stein kernel, introduced by Oates, Girolami, and Chopin in their 2017 Series B Read Paper. This is rather paradoxical, even though the outcome does depend on the divergence criterion. Most intriguing!!!