Archive for M-estimation

robust privacy

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , on May 14, 2024 by xi'an

During a recent working session, some Oceanerc (incl. me) went reading Privacy-Preserving Parametric Inference: A Case for Robust Statistics by Marco Avella-Medina (JASA, 2022), where robust criteria are advanced as efficient statistical tools in private settings. In this paper, robustness means using M-estimators T—as function of the empirical cdf—with basis score functions Ψ, defined as
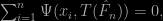
\sum_{i=1}^n\Psi(x_i,T(\hat F_n))=0,

where Ψ is bounded. A construction further requiring that one can assess the sensitivity (in Dwork et al, 2006, sense) of a queried function, sensitivity itself linked with a measure of differential privacy. Because standard robustness approaches à la Huber allow for a portion of the sample to issue from an outlying (arbitrary) distribution, as in ε-contaminations, it makes perfect sense that robustness emerges within the differential framework. However, this common sense perception does not seem good enough for achieving differential privacy and the paper introduces a further randomization with noise scaled by (n,ε,δ) in the following way

T(\hat F_n)+\gamma(T,\hat F_n)5\sqrt{2\log(n)\log(2/\delta)/\epsilon_n}Z

that also applies to test statistics. This scaling seems to constitute the central result of the paper, which establishes asymptotically validity in the sense of statistical consistency (with the sample size n). But I am left wondering whether this outcome counts as supporting differential privacy as a sensible notion…

“…our proofs for the convergence of noisy gradient descent and noisy Newton’s method rely on showing that with high probability, the noise introduced to the gradients and Hessians has a negligible effect on the convergence of the iterates (up to the order of the statistical error of the non-noisy versions of the algorithms).” Avella-Medina, Bradshaw, & Loh

As a sequel I then read a more recent publication of Avella-Medina, Differentially private inference via noisy optimization, written with Casey Bradshaw & Po-Ling Loh, which appeared in the Annals of Statistics (2023). Again considering privatised estimation and inference for M-estimators, obtained by using noisy optimization procedures (noisy gradient descent, noisy Newton’s method) and constructing noisy confidence regions, that output differentially private avatars of standard M-estimators. Here the noisification goes through a randomisation of the gradient step like
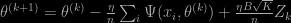
\theta^{(k+1)}=\theta^{(k)}-\frac{\eta}{n}\sum_i\Psi(x_i,\theta^{(k)})+\frac{\eta B\sqrt K}{n}Z_k

where B is an upper bound on the gradient Ψ, η is a discretization step, and K is the total number of iterations (thus fixed in advance). The above stochastic gradient sequence converges with high probability to the actual M-estimator in n and not in K, since the upper bound on the distance scales in √K/n. Where does the attached privacy guarantee come from? It proceeds by an argument of a composition of a sequence of differentially private outputs, all based on the same dataset.

“…the larger the number [K] of data (gradient) queries of the algorithm, the more prone it will be to privacy leakage.”

The Newton method version is a variation on the above stochastic gradient descent. Except it seems to converge faster, as illustrated above.

ISBA 2016 [#6]

Posted in Kids, Mountains, pictures, Statistics, Travel, University life, Wines with tags , , , , , , , , , , , , , , on June 19, 2016 by xi'an

Fifth and final day of ISBA 2016, which was as full and intense as the previous ones. (Or even more if taking into account the late evening social activities pursued by most participants.) First thing in the morning, I managed to get very close to a hill top, thanks to the hints provided by Jeff Miller!, and with no further scratches from the nasty local thorn bushes. And I was back with plenty of time for a Bayesian robustness session with great talks. (Session organised by Judith Rousseau whom I crossed while running, rushing to the airport thanks to an Air France last-minute cancellation.) First talk by James Watson (on his paper with Chris Holmes on Kullback neighbourhoods on priors that Judith and I discussed recently in Statistical Science). Then as a contrapunto Peter Grünwald gave a neat geometric motivation for possible misbehaviour of Bayesian inference in non-convex misspecified environments and discussed his SafeBayes resolution that weights down the likelihood. In a sort of PAC-Bayesian way. And Erlis Ruli presented the ABC-R approach he developed with Laura Ventura and Nicola Sartori based on M-estimators and score functions. Making wonder [idly, as usual] whether cumulating different M-estimators would make a difference in the performances of the ABC algorithm.

David Dunson delivered one of the plenary lectures on high-dimensional discrete parameter estimation, including for instance categorical data. This wide-range talk covered many aspects and papers of David’s work, including a use of tensors I had neither seen nor heard of before before. With sparse modelling to resist the combinatoric explosion of contingency tables. However, and you may blame my Gallic pessimistic daemon for this remark, I have trouble to picture the meaning and relevance of a joint distribution on a space of hundreds and hundreds of dimension and similarly the ability to check the adequacy of any modelling in terms of goodness of fit. For instance, to borrow a non-military example from David’s talk, handling genetic data on ACGT sequences to infer its distribution sounds unreasonable unless most of the bases are mono-allelic. And the only way I see to test the realism of a model in this framework would be to engineer realisations of this distribution to observe the outcome, a test that seems neither feasible not desirable. Prediction based on such models may obviously operate satisfactorily without such realism requirements.

My first afternoon session (after the ISBA assembly that announced the location of ISBA 2020 in Yunnan, China!, home of Pu’ Ehr tea) was about accelerated MCMC schemes with talks by Sanvesh Srivastava on divide-and-conquer MCMC using Wasserstein barycentres, already discussed here, Minsuk Shin on a faster stochastic search variable selection which I could not understand, and Alex Beskos on the extension of Giles’ multilevel Monte Carlo to MCMC settings, which sounded worth investigating further even though I did not follow the notion all the way through. After listening to Luke Bornn explaining how to recalibrate grid data for climate science by accounting for correlation (with the fun title of `lost moments’), I rushed to my rental to [help] cook dinner for friends and… the ISBA 2016 conference was over!

communication-efficient distributed statistical learning

Posted in Books, Statistics, University life with tags , , , , , , , , on June 10, 2016 by xi'an

mikecemMichael Jordan, Jason Lee, and Yun Yang just arXived a paper with their proposal on handling large datasets through distributed computing, thus contributing to the currently very active research topic of approximate solutions in large Bayesian models. The core of the proposal is summarised by the screenshot above, where the approximate likelihood replaces the exact likelihood with a first order Taylor expansion. The first term is the likelihood computed for a given subsample (or a given thread) at a ratio of one to N and the difference of the gradients is only computed once at a good enough guess. While the paper also considers M-estimators and non-Bayesian settings, the Bayesian part thus consists in running a regular MCMC when the log-target is approximated by the above. I first thought this proposal amounted to a Gaussian approximation à la Simon Wood or to an INLA approach but this is not the case: the first term of the approximate likelihood is exact and hence can be of any form, while the scalar product is linear in θ, providing a sort of first order approximation, albeit frozen at the chosen starting value.

mikecem2Assuming that each block of the dataset is stored on a separate machine, I think the approach could further be implemented in parallel, running N MCMC chains and comparing the output. With a post-simulation summary stemming from the N empirical distributions thus produced. I also wonder how the method would perform outside the fairly smooth logistic regression case, where the single sample captures well-enough the target. The picture above shows a minor gain in a misclassification rate that is already essentially zero.