 I am quite surprised that the NobAIl committee did not select ChatGPT‘s Sam Altman for their literature prize—since he made a reality of monkeys typing at random on a typewriter, hence bound to a.s. produce past and future masterpieces—, now betting on Twitter’s Dorsey, Williams and Stone for their peace prize— for achieving worldwide harmony if within each single-minded community in only 140 characters—, and Amazon’s Jeff Bezos for their Sveriges Riksbank Prize in Economic Sciences in Memory of Alfred Nobel—for produing the ultimate monopoly of a single worldwide convenience store—, given their picks for physics—with spin glass Ising models that have always sounded to me like the worst possible illustration for MCMC techniques— and chemistry—for a deep learning predictor of protein structures, built by large teams and numerous CPU hours, achieving high success rates if not perfection, but prediction is not explanation, reminding me of Nietzsche’s “physics, too, is only an interpretation and exegesis of the world (to suit us, if I may say so!) and not a world-explanation”—… Keeping their sharp focus on AI’s, corporate funded research, and male recipients… (As coïncidences come, I am currently reading a book of the literature 2024 Nobel recipient, Han Kang, The Vegetarian, that I find stunning and immensely original!)
Archive for Markov random field
NobAIl prAIzes
Posted in Books, pictures, Travel, University life with tags AI, AlphaFold, Amazon, artificial intelligence, Boltzmann machines, Botlzman models, ChatGPT, Deep Mind, Friedrich Nietzsche, Google, Hopfield networks, Ising model, Markov random field, MCMC algorithms, neural network, Nobel Prize, Nobel Prize in Litterature, protein folding, South Korea, Stockholm, Sveriges Riksbank Prize in Economic Sciences in Memory of Alfred Nobel, Sweden, twitter, vegetarian diet on October 11, 2024 by xi'anflea circus
Posted in Books, Kids, pictures, R, Statistics with tags coupling, cross validated, fleas, Leonhard Euler, Markov chains, Markov random field, Monte Carlo integration, occupancy, Poisson approximation, R, random walk, stationarity on December 8, 2016 by xi'an An old riddle found on X validated asking for Monte Carlo resolution but originally given on Project Euler:
A 30×30 grid of squares contains 30² fleas, initially one flea per square. When a bell is rung, each flea jumps to an adjacent square at random. What is the expected number of unoccupied squares after 50 bell rings, up to six decimal places?
The debate on X validated is whether or not a Monte Carlo resolution is feasible. Up to six decimals, certainly not. But with some lower precision, certainly. Here is a rather basic R code where the 50 steps are operated on the 900 squares, rather than the 900 fleas. This saves some time by avoiding empty squares.
xprmt=function(n=10,T=50){

 mean=0
 for (t in 1:n){

   board=rep(1,900)
   for (v in 1:T){

    beard=rep(0,900)
    if (board[1]>0){
      poz=c(0,1,0,30)
      ne=rmultinom(1,board[1],prob=(poz!=0))
      beard[1+poz]=beard[1+poz]+ne}
    #
    for (i in (2:899)[board[-1][-899]>0]){
     u=(i-1)%%30+1;v=(i-1)%/%30+1
     poz=c(-(u>1),(u<30),-30*(v>1),30*(v<30))
     ne=rmultinom(1,board[i],prob=(poz!=0))
     beard[i+poz]=beard[i+poz]+ne}
    #
    if (board[900]>0){
     poz=c(-1,0,-30,0)
     ne=rmultinom(1,board[900],prob=(poz!=0))
     beard[900+poz]=beard[900+poz]+ne}
     board=beard}
   mean=mean+sum(board==0)}
 return(mean/n)}
The function returns an empirical average over n replications. With a presumably awkward approach to the borderline squares, since it involves adding zeros to keep the structure the same… Nonetheless, it produces an approximation that is rather close to the approximate expected value, in about 3mn on my laptop.
> exprmt(n=1e3)
[1] 331.082
> 900/exp(1)
[1] 331.0915
Further gains follow from considering only half of the squares, as there are two independent processes acting in parallel. I looked at an alternative and much faster approach using the stationary distribution, with the stationary being the Multinomial (450,(2/1740,3/1740…,4/1740,…,2/1740)) with probabilities proportional to 2 in the corner, 3 on the sides, and 4 in the inside. (The process, strictly speaking, has no stationary distribution, since it is periodic. But one can consider instead the subprocess indexed by even times.) This seems to be the case, though, when looking at the occupancy frequencies, after defining the stationary as:
inva=function(B=30){
return(c(2,rep(3,B-2),2,rep(c(3,
  rep(4,B-2),3),B-2),2,rep(3,B-2),2))}
namely
> mn=0;n=1e8 #14 clock hours!
> proz=rep(c(rep(c(0,1),15),rep(c(1,0),15)),15)*inva(30)
> for (t in 1:n)
+ mn=mn+table(rmultinom(1,450,prob=rep(1,450)))[1:4]
> mn=mn/n
> mn[1]=mn[1]-450
> mn
     0      1      2     3
166.11 164.92  82.56 27.71
> exprmt(n=1e6) #55 clock hours!!
[1] 165.36 165.69 82.92 27.57
my original confusion being that the Poisson approximation had not yet taken over… (Of course, computing the first frequency for the stationary distribution does not require any simulation, since it is the sum of the complement probabilities to the power 450, i.e., 166.1069.)
auxiliary variable methods as ABC
Posted in Books, pictures, Statistics, University life with tags ABC, auxiliary variable, doubly intractable problems, Markov random field, Newcastle-upon-Tyne, unbiased estimation on May 9, 2016 by xi'an Dennis Prangle and Richard Everitt arXived a note today where they point out the identity between the auxiliary variable approach of Møller et al. (2006) [or rather its multiple or annealed version à la Murray] and [exact] ABC (as in our 2009 paper) in the case of Markov random fields. The connection between the two appears when using an importance sampling step in the ABC algorithm and running a Markov chain forward and backward the same number of steps as there are levels in the annealing scheme of MAV. Maybe more a curiosity than an indicator of a large phenomenon, since it is so rare that ABC can be use in its exact form.
insufficient statistics for ABC model choice
Posted in Books, Kids, Statistics, University life with tags ABC, arXiv, Cross Validation, Gibbs random field, hidden Markov models, Markov random field, Monte Carlo Statistical Methods, paradigm shift, Pierre Pudlo, predictive loss, simulation, summary statistics on October 17, 2014 by xi'an[Here is a revised version of my comments on the paper by Julien Stoehr, Pierre Pudlo, and Lionel Cucala, now to appear [both paper and comments] in Statistics and Computing special MCMSki 4 issue.]
 Approximate Bayesian computation techniques are 2000’s successors of MCMC methods as handling new models where MCMC algorithms are at a loss, in the same way the latter were able in the 1990’s to cover models that regular Monte Carlo approaches could not reach. While they first sounded like “quick-and-dirty” solutions, only to be considered until more elaborate solutions could (not) be found, they have been progressively incorporated within the statistican’s toolbox as a novel form of non-parametric inference handling partly defined models. A statistically relevant feature of those ACB methods is that they require replacing the data with smaller dimension summaries or statistics, because of the complexity of the former. In almost every case when calling ABC is the unique solution, those summaries are not sufficient and the method thus implies a loss of statistical information, at least at a formal level since relying on the raw data is out of question. This forced reduction of statistical information raises many relevant questions, from the choice of summary statistics to the consistency of the ensuing inference.
In this paper of the special MCMSki 4 issue of Statistics and Computing, Stoehr et al. attack the recurrent problem of selecting summary statistics for ABC in a hidden Markov random field, since there is no fixed dimension sufficient statistics in that case. The paper provides a very broad overview of the issues and difficulties related with ABC model choice, which has been the focus of some advanced research only for a few years. Most interestingly, the authors define a novel, local, and somewhat Bayesian misclassification rate, an error that is conditional on the observed value and derived from the ABC reference table. It is the posterior predictive error rate
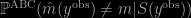
integrating in both the model index m and the corresponding random variable Y (and the hidden intermediary parameter) given the observation. Or rather given the transform of the observation by the summary statistic S. The authors even go further to define the error rate of a classification rule based on a first (collection of) statistic, conditional on a second (collection of) statistic (see Definition 1). A notion rather delicate to validate on a fully Bayesian basis. And they advocate the substitution of the unreliable (estimates of the) posterior probabilities by this local error rate, estimated by traditional non-parametric kernel methods. Methods that are calibrated by cross-validation. Given a reference summary statistic, this perspective leads (at least in theory) to select the optimal summary statistic as the one leading to the minimal local error rate. Besides its application to hidden Markov random fields, which is of interest per se, this paper thus opens a new vista on calibrating ABC methods and evaluating their true performances conditional on the actual data. (The advocated abandonment of the posterior probabilities could almost justify the denomination of a paradigm shift. This is also the approach advocated in our random forest paper.)
JSM 2014, Boston [#2]
Posted in Statistics, Travel, University life with tags Boston, CHANCE, conjugate priors, dynamic model, feature allocation model, Harvard Square, JSM 2014, Markov random field, optimal transport on August 7, 2014 by xi'an
Day #2 at JSM started quite early as I had to be on site by 7am for the CHANCE editors breakfast. No running then, except to Porter metro station. Interesting exchange full of new ideas to keep the journal cruising. In particular, a call for proposals on special issues on sexy topics (reproducible research anyone? I already have some book reviews.). And directions to increase the international scope and readership. And possibly adding or reporting on a data challenge. After this great start, I attended the Bayesian Time Series and Dynamic Models session, where David Scott Matteson from Cornell University presented an extension of the Toronto ambulance data analysis Dawn Woodard had exposed in Banff at an earlier workshop. The extension dealt with the spatio-temporal nature of the data, using a mixture model with time-dependent weights that revolved cyclically in an autoexponential manner. And rekindling the interest in the birth-and-death alternative to reversible jump. Plus another talk by Scott Holan mixing Bayesian analysis with frequency data, an issue that always puzzled me. The second session I attended was Multiscale Modeling for Complex Massive Data, with a modelling of brain connections through a non-parametric mixture by David Dunson. And a machine learning talk by Mauro Maggioni on a projection cum optimisation technique to fight the curse of dimension. Who proposed a solution to an optimal transport problem that is much more convincing than the one I discussed a while ago. Unfortunately, this made me miss the Biometrics showcase session, where Debashis Mondal presented a joint work with Julian Besag on Exact Goodness-of-Fit Tests for Markov Chains. And where both my friends Michael Newton and Peter Green were discussants… An idle question that came to me during this last talk was about the existence of particle filters for spatial Markov structures (rather than the usual ones on temporal Markov models).
After a [no] lunch break spent on pondering over a conjecture laid to me by Natesh Pillai yesterday, I eventually joined the Feature Allocation session. Eventually as I basically had to run the entire perimeter of the conference centre! The three talks by Finale Doshi-Velez, Tamara Broderick, and Yuan Ji were all impressive and this may have been my best session so far at JSM! Thanks to Peter Müller for organising it! Tamara Broderick focussed on a generic way to build conjugate priors for non-parametric models, with all talks involving Indian buffets. Maybe a suggestion for tonight’s meal..! (In the end, great local food onn Harvard Square.)


