Archive for impact factor

Nature tidbits [Jan 2025]

Posted in Statistics with tags , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , , on April 13, 2025 by xi'an

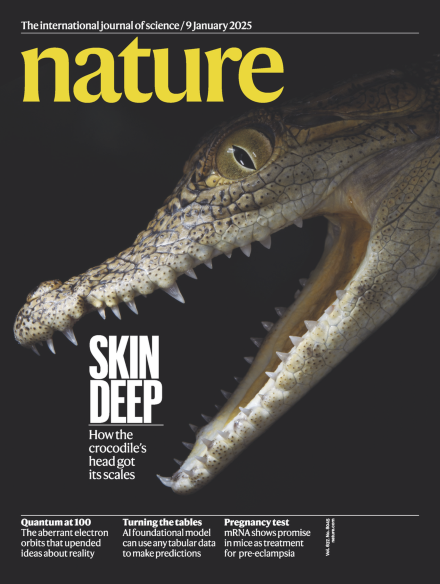
Entries of these two January issues on

– yet another 100th anniversary!, namely the founding paper of Heisenberg’s quantum mechanics paper in Zeitschrift für Physik, written on the Instagrammable island of Heligoland. With celebrations at the UNESCO in Paris, Anaheim (CA), Kumasi (Ghana), and Salvador de Bahia (Brazil)!;

– some bird species decorating their nest with shed snakeskins, to frighten predators;

– climate predictions for Trump 2.0, albeit the only certainty being it will get worse and worse (and only the beginning of a flow of articles on the Trumpian attacks on science and scientists);

– the curious plight of the open access journal elife loosing its impact factor after getting too open for Clarivate and then seeing submission from China falter;

– the first European cities from 6000 years ago being found in Ukraine (and Romania) within the Cucuteni-Trypillia culture, with apparently an equalitarian structure with no temple or elite, although the lack of written documents (besides beautiful clay figures whose style evolved over the period);

  • an AI tool that interprets spreadsheets (which I would find most useful, given my distaste of said spreadsheets!);

and how to help lab workers facing substance disorders. And break the attached taboos. Which reminded me of a colleague in that situation when I was head of a lab, years and years ago. And of the difficulty of handling the case all by myself…

Also

– a quick report on a Physics Review Letters paper about simulating elections results to spot whether or not margins of victory were properly distributed, having a distribution (for the scaled margins) mostly depending on voter turnout, with a universal shape! The concept behind this analysis is one of universality borrowed from statistical physics. (The fit does not work for the Ethiopian election of 2010 and the Belarus elections during 2004–2019, no wonder!);

– another book review of David Spiegelhalter’s Art of Uncertainty, by Yongyi Min, a statistician from the UN Statistics Division;

  • creating a DNA base for identifying children kidnapped during a conflict, as for the 20,000 Ukrainian children forcibly deported to Russia over the past three years;

  • a substantial survey article on neuromorphic computing (submitted in 2023!), about new forms of computing based on hardware/software co-design;

  • with more technologies to watch in 2025, and another long article (and the cover) on the strong impact of small-scale fisheries on sustainable development.


    Elsevier in the frontline

    Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on January 27, 2017 by xi'an

    “Viewed this way, the logo represents, in classical symbolism, the symbiotic relationship between publisher and scholar. The addition of the Non Solus inscription reinforces the message that publishers, like the elm tree, are needed to provide sturdy support for scholars, just as surely as scholars, the vine, are needed to produce fruit. Publishers and scholars cannot do it alone. They need each other. This remains as apt a representation of the relationship between Elsevier and its authors today – neither dependent, nor independent, but interdependent.”

    There were two items of news related with the publishark Elsevier in the latest issue of Nature I read. One was that Germany, Peru, and Taiwan had no longer access to Elsevier journals, after negotiations or funding stopped. Meaning the scientists there have to find alternative ways to procure the papers, from the authors’ webpage [I do not get why authors fail to provide their papers through their publication webpage!] to peer-to-peer platforms like Sci-Hub. Beyond this short term solution, I hope this pushes for the development of arXiv-based journals, like Gower’s Discrete Analysis. Actually, we [statisticians] should start planing a Statistics version of it!

    The second item is about  Elsevier developing its own impact factor index, CiteScore. While I do not deem the competition any more relevant for assessing research “worth”, seeing a publishark developing its own metrics sounds about as appropriate as Breithart News starting an ethical index for fake news. I checked the assessment of Series B on that platform, which returns the journal as ranking third, with the surprising inclusion of the Annual Review of Statistics and its Application [sic], a review journal that only started two years ago, of Annals of Mathematics, which does not seem to pertain to the category of Statistics, Probability, and Uncertainty, and of Statistics Surveys, an IMS review journal that started in 2009 (of which I was blissfully unaware). And the article in Nature points out that, “scientists at the Eigenfactor project, a research group at the University of Washington, published a preliminary calculation finding that Elsevier’s portfolio of journals gains a 25% boost relative to others if CiteScore is used instead of the JIF“. Not particularly surprising, eh?!

    When looking for an illustration of this post, I came upon the hilarious quote given at the top: I particularly enjoy the newspeak reversal between the tree and the vine,  the parasite publishark becoming the support and the academics the (invasive) vine… Just brilliant! (As a last note, the same issue of Nature mentions New Zealand aiming at getting rid of all invasive predators: I wonder if publishing predators are also included!)

    a discovery that mean can be impacted by extreme values

    Posted in University life with tags , , , , , , on August 6, 2016 by xi'an

    A surprising editorial in Nature about the misleading uses of impact factors, since as means they are heavily impacted by extreme values. With the realisation that the mean is not the median for skewed distributions…

    To be fair(er), Nature published a subsequent paper this week about publishing additional metrics like the two-year median.

    statistical modelling of citation exchange between statistics journals

    Posted in Books, Statistics, University life with tags , , , , , on April 10, 2015 by xi'an

    Cristiano Varin, Manuela Cattelan and David Firth (Warwick) have written a paper on the statistical analysis of citations and index factors, paper that is going to be Read at the Royal Statistical Society next May the 13th. And hence is completely open to contributed discussions. Now, I have written several entries on the ‘Og about the limited trust I set to citation indicators, as well as about the abuse made of those. However I do not think I will contribute to the discussion as my reservations are about the whole bibliometrics excesses and not about the methodology used in the paper.

    The paper builds several models on the citation data provided by the “Web of Science” compiled by Thompson Reuters. The focus is on 47 Statistics journals, with a citation horizon of ten years, which is much more reasonable than the two years in the regular impact factor. A first feature of interest in the descriptive analysis of the data is that all journals have a majority of citations from and to journals outside statistics or at least outside the list. Which I find quite surprising. The authors also build a cluster based on the exchange of citations, resulting in rather predictable clusters, even though JCGS and Statistics and Computing escape the computational cluster to end up in theory and methods along Annals of Statistics and JRSS Series B.

    In addition to the unsavoury impact factor, a ranking method discussed in the paper is the eigenfactor score that starts with a Markov exploration of articles by going at random to one of the papers in the reference list and so on. (Which shares drawbacks with the impact factor, e.g., in that it does not account for the good or bad reason the paper is cited.) Most methods produce the Big Four at the top, with Series B ranked #1, and Communications in Statistics A and B at the bottom, along with Journal of Applied Statistics. Again, rather anticlimactic.

    The major modelling input is based on Stephen Stigler’s model, a generalised linear model on the log-odds of cross citations. The Big Four once again receive high scores, with Series B still much ahead. (The authors later question the bias due to the Read Paper effect, but cannot easily evaluate this impact. While some Read Papers like Spiegelhalter et al. 2002 DIC do generate enormous citation traffic, to the point of getting re-read!, other journals also contain discussion papers. And are free to include an on-line contributed discussion section if they wish.) Using an extra ranking lasso step does not change things.

    In order to check the relevance of such rankings, the authors also look at the connection with the conclusions of the (UK) 2008 Research Assessment Exercise. They conclude that the normalised eigenfactor score and Stigler model are more correlated with the RAE ranking than the other indicators.  Which means either that the scores are good predictors or that the RAE panel relied too heavily on bibliometrics! The more global conclusion is that clusters of journals or researchers have very close indicators, hence that ranking should be conducted with more caution that it is currently. And, more importantly, that reverting the indices from journals to researchers has no validation and little information.

    Series B reaches 5.721 impact factor!

    Posted in Books, Statistics, University life with tags , , , on September 15, 2014 by xi'an

    I received this email from Wiley with the great figure that JRSS Series B has now reached a 5.721 impact factor. Which makes it the first journal in Statistics from this perspective. Congrats to editors Gareth Roberts, Piotr Fryzlewicz and Ingrid Van Keilegom for this achievement! An amazing jump from the 2009 figure of 2.84…!