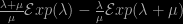Archive for unbiasedness

THAMES for mixtures, a reply from the authors

Posted in Books, pictures, R, Statistics, University life with tags , , , , , , , , , , , , , , on June 23, 2025 by xi'an

[Here is a reply to my comments on THAMES sent by the first author of the paper, Martin Metodiev. The above replica of the cover of Rivers of London is obviously unrelated with the reply or the original blog, beyond presenting a fantasy map of the Thames!]

Thank you for your review of our article! Adapting your previous work in this field has been a pleasure. Before I respond to your comments, I would like to emphasize that the simplicity of our estimator lies in its simple analytic expression (a truncated harmonic mean of reciprocal unnormalized posterior density values). Indeed, our package “thamesmix” (recently submitted to CRAN!) has a function to compute the marginal likelihood of any mixture model. This function requires only two parameters: the unnormalized log-posterior function (the logarithm of the prior plus the log-likelihood) and the MCMC simulations from the posterior.

Regarding your main comments:

1. “the evacuation of earlier methods as not simple or not universal enough is rather disingenuous. For instance, software that do not return (latent) allocation vectors can easily be post-processed.”

I could not find an example of post-process simulations on top of MCMC outputs applied to compute these methods. It sounds really interesting, and I would be happy to cite it. Is there a reference that you can recommend?

In any case, the point still stands. Most estimators which we cite with regards to this point do not just need allocation samplers, but also the analytic expressions of the distribution of the allocation vectors or the distribution of the data conditional on these allocation vectors that come with them. I do not think that a closed form of this distribution is available in general.

2.“the handling of the label switching issue—the reason why Larry Wasserman saw mixtures at the same magnitude of evil as tequila!—is problematic for several reasons.”

The fact that our estimator is invariant to label-switching is indeed the core of our method. The simple Gibbs sampler gets stuck in one mode, and this is why the classical version of bridge sampling is biased by a factor of G! in the simulation setting. As you point out, this is successfully resolved when using fully symmetric bridge sampling in the experiment section. However, the computation cost of this fully symmetric estimator rises super-exponentially with G, so I do not see how it could be evaluated for G=15, where the number of symmetric modes is equal to 15! (over one trillion). One of the main points of our article is that the symmetric THAMES can be evaluated in a feasible amount of time, even in such a high-dimensional multivariate setting.

3. “the (legitimate) purpose of using marginal likelihoods for selecting the number G of components is weakened by the intrusion of alternate proposals to assess G from the data”

I would like to point out that these alternate proposals do not in any way impact the definition of the THAMES. It is the simple definition given in Equation (5). They are only used to speed up the computation.

4. “several mentions are made of the other estimators being biased, which is indeed the case for bridge sampling (if not necessarily for importance sampling), but not necessarily a central issue”

The problem that we see with the classical, non-symmetric bridge sampling method in the setting of mixture models is not simply that it is biased. The problem is that the bias is persistent and often roughly equal to the factor of G! when the MCMC sampler failed to switch between modes. We have not had this experience with the THAMES: it converged even when the MCMC was stuck.

R[are]SS meeting

Posted in Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , on September 29, 2024 by xi'an


Yesterday, I happened to be at the right time in the right place, as I was in Warwick for a RSS local section meeting on rare event simulation. (If missing the aurora borealis and the moon eclipse on previous nights!) And hence attended a seminar by Francesca Crucinio in six days!, as she talked about a turnkey approach to unbiased estimation of transforms of a moment, or wlog a mean μ, f(μ). A recent article with Nicolas Chopin (CREST) and Sumeet Singh, where they resort to Taylor expansions to achieve unbiasedness, using the Russian roulette trick to stop the summation from running to infinity. (As it happens, I heard Nicolas talk about this idea in the recent past namely at the ISBA-Fusion Sunday morn at Ca’Foscari.) Using a Taylor expansion is obviously natural and mathematically correct, albeit fraught with potential dangers [imho]:

  • the Taylor expansion involves central moments up to a random order R, which are harder & harder to estimate with increasing orders (i.e., more & more uncertain, with the possibility of infinite variance estimators after a certain order)
  • I did not spot a discussion on the moment estimators, that seems to rely on k iid replicas for the k-th moment
  • a lot of calibration ensues, from the choice of the centre x⁰ to the (artificial) distribution of the stopping value R, to the parameterisation of the random variable attached to the moment μ
  • the paper insists on recycling simulations to stabilise the moment estimators and ensure consistency, as a primary level of Rao-Blackwellisation, but this only applies to the smallest order moments and could be devised in many different ways, with varying computing costs
  • consistency of the estimate is not necessarily needed, as for instance for pseudo-marginal applications
  • as often with Russian roulette, positive quantities may receive negative estimations that are dominated by truncations to the positive real line (and alternating series offer the use of sandwiching estimators)
  • for the above reason, it is not always reasonable to tunnel vision on unbiasedness and alternative estimates like bridge sampling solutions could be integrating towards improving the quality of the estimator (especially since the conditions for finite variance involve unknown quantities)
  • while f-Taylored solutions like harmonic mean estimators for f(x)=1/x are not necessarily a panacea, they could be included in the comparison or as control variates

The first talk by Mathias Rousset was investigating adaptive multilevel sampling, a form of nested sampler, at the theoretical level, while the third talk by Tobias Grafke was a repetition of a talk he gave at the masterclass the interface between computational physics and computational statistics, last April.

max vs. min

Posted in Books, Kids, Statistics with tags , , , , , , , , on March 26, 2022 by xi'an

Another intriguing question on X validated (about an exercise in Jun Shao’s book) that made me realise a basic fact about exponential distributions. When considering two Exponential random variables X and Y with possibly different parameters λ and μ,  Z⁺=max{X,Y} is dependent on the event X>Y while Z⁻=min{X,Y} is not (and distributed as an Exponential variate with parameter λ+μ.) Furthermore, Z⁺ is distributed from a signed mixture

\frac{\lambda+\mu}{\mu}\mathcal Exp(\lambda)-\frac{\lambda}{\mu}\mathcal Exp(\lambda+\mu)

conditionally on the event X>Y, meaning that there is no sufficient statistic of fixed dimension when given a sample of n realisations of Z⁺’s along with the indicators of the events X>Y…. This may explain why there exists an unbiased estimator of λ⁻¹-μ⁻¹ in this case and (apparently) not when replacing Z⁺ by Z⁻. (Even though the exercise asks for the UMVUE.)

invertible flow non equilibrium sampling (InFiNE)

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on May 21, 2021 by xi'an

With Achille Thin and a few other coauthors [and friends], we just arXived a paper on a new form of importance sampling, motivated by a recent paper of Rotskoff and Vanden-Eijnden (2019) on non-equilibrium importance sampling. The central ideas of this earlier paper are the introduction of conformal Hamiltonian dynamics, where a dissipative term is added to the ODE found in HMC, namely
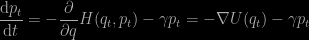
\dfrac{\text d p_t}{\text dt}=-\dfrac{\partial}{\partial q}H(q_t,p_t)-\gamma p_t=-\nabla U(q_t)-\gamma p_t

which means that all orbits converge to fixed points that satisfy ∇U(q) = 0 as the energy eventually vanishes. And the property that, were T be a conformal Hamiltonian integrator associated with H, i.e. perserving the invariant measure, averaging over orbits of T would improve the precision of Monte Carlo unbiased estimators, while remaining unbiased. The fact that Rotskoff and Vanden-Eijnden (2019) considered only continuous time makes their proposal hard to implement without adding approximation error, while our approach is directly set in discrete-time and preserves unbiasedness. And since measure preserving transforms are too difficult to come by, a change of variable correction, as in normalising flows, allows for an arbitrary choice of T, while keeping the estimator unbiased. The use of conformal maps makes for a natural choice of T in this context.

The resulting InFiNE algorithm is an MCMC particular algorithm which can be represented as a  partially collapsed Gibbs sampler when using the right auxiliary variables. As in Andrieu, Doucet and Hollenstein (2010) and their ISIR algorithm. The algorithm can be used for estimating normalising constants, comparing favourably with AIS, sampling from complex targets, and optimising variational autoencoders and their ELBO.

I really appreciated working on this project, with links to earlier notions like multiple importance sampling à la Owen and Zhou (2000), nested sampling, non-homogeneous normalising flows, measure estimation à la Kong et al. (2002), on which I worked in a more or less distant past.

re-reading Halmos (1946)

Posted in Books, Kids, Statistics, University life with tags , , , on May 16, 2020 by xi'an

Based on a (basic) question on X validated, I re-read Halmos‘ (1946) famous paper on the non-existence of centred moments of order larger than the sample size. While the exposition may sound a wee bit daunting, the reasoning is essentially based on a recursion and the binomial theorem, since expanding the kth power leads to lesser moments, all of which can be estimated from a subsample.