Archive for big data

Nature (statistical) tidbits

Posted in Statistics with tags , , , , , , , , , , , , , , , , , , , , , , , , , , on January 3, 2025 by xi'an

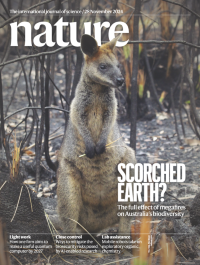
In the 28 November issue of Nature, with this black wallaby left with little to survive after the massive wildfires of 2020, which I read on my way to Nice, several entries related with statistics at large:

Privacy-preserving Computing [book review]

Posted in Books, Statistics with tags , , , , , , , , , , , , , , on May 13, 2024 by xi'an

Privacy-preserving Computing for Big Data Analytics and AI, by Kai Chen and Qiang Yang, is a rather short 2024 CUP book translated from the 2022 Chinese version (by the authors).  It covers secret sharing, homomorphic encryption, oblivious transfer, garbled circuit, differential privacy, trusted execution environment, federated learning, privacy-preserving computing platforms, and case studies. The style is survey-like, meaning it often is too light for my liking, with too many lists of versions and extensions, and more importantly lacking in detail to rely (solely) on it for a course. At several times standing closer to a Wikipedia level introduction to a topic. For instance, the chapter on homomorphic encryption [Chap.5] does not connect with the (presumably narrow) picture I have of this method. And the chapter on differential privacy [Chap.6] does not get much further than Laplace and Gaussian randomization, as in eg the stochastic gradient perturbation of Abadi et al. (2016) the privacy requirement is hardly discussed. The chapter on federated leaning [Chap.8] is longer if not much more detailed, being based on a entire book on Federated learning whose Qiang Yang is the primary author. (With all figures in that chapter being reproduced from said book.)  The next chapter [Chap.9] describes to some extent several computing platforms that can be used for privacy purposes, such as FATE, CryptDB, MesaTEE, Conclave, and PrivPy, while the final one goes through case studies from different areas, but without enough depth to be truly formative for neophyte readers and students. Overall, too light for my liking.

[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Books Review section in CHANCE.]

if then [reading a book self-review]

Posted in Statistics with tags , , , , , , , , , , , , , on October 26, 2020 by xi'an

Nature of 17 September 2020 has a somewhat surprising comment section where an author, Jill Lepore from Harvard University, actually summarises her own book, If Then: How the Simulmatics Corporation invented the Future. This book is the (hi)story of a precursor of Big Data Analytics, Simulmatics, which used as early as 1959 clustering and simulation to predict election results and if possible figure out discriminant variables. Which apparently contributed to John F. Kennedy’ s victory over Richard Nixon in 1960. Rather than admiring the analytic abilities of such precursors (!), the author is blaming them for election interference. A criticism that could apply to any kind of polling, properly or improperly conducted. The article also describes how Simulmatics went into advertising, econometrics and counter-insurgency, vainly trying to predict the occurence and location of riots (at home) and revolutions (abroad). And argues in a all-encompassing critique against any form of data-analytics applied to human behaviour. And praises the wisdom of 1968 protesters over current Silicon Valley researchers (whose bosses may have been among these 1968 protesters!)… (Stressing again that my comments come from reading and reacting to the above Nature article, not the book itself!)

Calling Bullshit: The Art of Scepticism in a Data‑Driven World [EJ’s book review]

Posted in Books, Statistics with tags , , , , , on August 26, 2020 by xi'an

“…this book will train readers to be statistically savvy at a time when immunity to misinformation is essential: not just for the survival of liberal democracy, as the authors assert, but for survival itself.Perhaps a crash course on bullshit detection should be a mandatory part of the school curriculum.”

In the latest issue of Nature, EJ Wagenmaker has written a book review of the book Calling Bullshit, by  Carl Bergstrom and Jevin West. Book written out of a course taught by the authors at the University of Washington during Spring Quarter 2017 and aimed at teaching students how to debunk bullshit, that is, misleading exploitation of statistics and machine learning. And subsequently turned into a book. Which I have not read. In his overall positive review EJ regrets the poor data visualisation scholarship of the authors, who could have demonstrated and supported the opportunity for a visual debunking of the original data. And the lack of alternative solutions like Bayesian analysis to counteract p-fishing. Of course, the need for debunking and exposing statistically sounding misinformation has never been so present.

Expectation Propagation as a Way of Life on-line

Posted in pictures, Statistics, University life with tags , , , , , , , , , , , , , on March 18, 2020 by xi'an

After a rather extended shelf-life, our paper expectation propagation as a way of life: a framework for Bayesian inference on partitioned data which was started when Andrew visited Paris in… 2014!, and to which I only marginally contributed, has now appeared in JMLR! Which happens to be my very first paper in this journal.