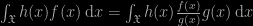
Archive for John von Neumann

Nature tidbits [and garbage out]

Posted in Books, Kids, Mountains, pictures, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , on October 25, 2024 by xi'an

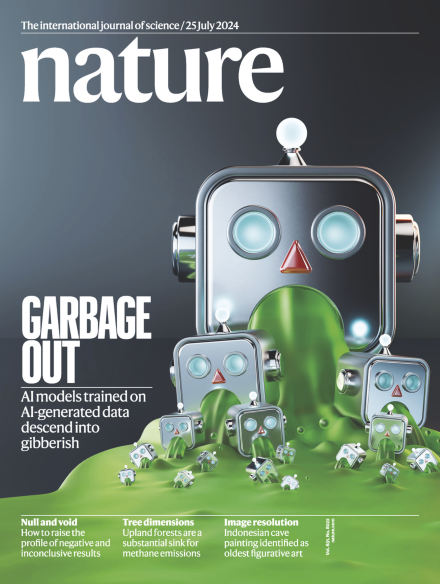
Many bits of interest in the 25 July issue of Nature that stayed under a pile of journals for PNW reasons! Even though the cover is rather off-putting…

  • A call by the editors (and computer scientist Cal Newport) for scientists to “stop, drop, and think” (and the paperback version of Newport’s Slow Productivity has a nice cover that looks very much like Moraine Lake in Banff National Parc!)
  • Another call by a Science Po’ sociologist to the (then highly prospective) French government to increase research budget for French universities, which is not particularly original since this is a constant line on all unions’ desiderata, except for the argument that it would make a tuition fees increase more palatable, and to leave more freedom to researchers, with the oft-used argument that “fundamental research may have unexpected implications”. Except that a massive public deficit is going to impose budget squeezes in all spending lines of the Barnier government.
  • Worries of Indian and non-Indian demographers about the continued postponement of India’s national census, with the latest one dating from 2011. With strong repercussions on public policies, especially since the administrative data systems are rarely reliable. The article suggests that more than an estimated 100 million inhabitants are excluded from food subsidies as a consequence. This seems like an opportunity to develop open source alternatives that run the census from indirect observations, bypassing the reluctance of the Modi Government to launch the much delayed census. (Which could have been coupled with the electoral process earlier this year.)
  • An insight on four female “PhD influencers” from the Universities of Pennsylvania, Exeter, Hertfordshire, and Hong Kong (CUHK). Which has a plus side of exposing the life and interests of a PhD student. And a downside of being a social media product, with the many biases that come along posting to the general public.
  • A call for publishing more papers about negative results! Supporting (pre)registration of experiments.
  • A positive book review of The MANIAC of Benjamin Labatut around John von Neumann’s life, analysed by Karl Sigmund
  • A four-page long comment on the importance of preserving scientific US-China relations, despite the growing suspicion in the US that any scientific collaboration with Chinese institutions will benefit Chinese (State) interests. Without falling for a naive approach to such collaborations, and acknowledging the porous boundaries between fundamental and military research, one should acknowledge the great leap forward accomplished by Chinese universities in the past decade that set their researchers at the forefront of science in many fields.
  • A paper related with the cover on model collapse in AIs learning from AI-generated data. Just like MCMC learning a proposal from earlier simulations. A natural consequence of over-fitting.
  • Another paper on the phase (or quantum) transition of the two-dimensional Ising spin glass (model).
  • and the article on predatory conferences I already discussed in August.

[very] simple rejection Monte Carlo

Posted in Books, pictures, R, University life with tags , , , , , , , , on March 29, 2024 by xi'an

“In recent years, the Rejection Monte Carlo (RMC) algorithm has emerged sporadically in literature under alternative names such as screening sampling or reject-accept sampling algorithms”

First, I was intrigued enough by a new arXival spotted in the Thalys train from Brussels to take a deeper look at it, but soon realised there was nothing of substance in the paper. Which solely recalls the fundamental of (accept-)reject algorithms, invented in the early days of computer simulation by von Neumann (even though the preprint refers to much more recent publications).  Without providing the average acceptance probability as being equal to the inverse of the bounding constant [independently of the dimension of the random variable] and no mention of The Bible either… But with a standard depiction of accepted vs rejected points as uniformly dispersed on the subgraph of the proposal (as in the above taken from our very own Monte Carlo statistical Methods). Funnily enough, the most basic rejection algorithm, that is, the one based on a uniform sampling from a bounding (hyper)box is illustrated for a Normal target, although the latter has infinite support. And the paper seems to conclude on the appeal of using uniform proposals over bounding boxes, even though the increasing inefficiency against the dimension is well-known. A very simple rejection then, indeed!

of first importance

Posted in Books, Kids, Statistics, University life with tags , , , , , , , , , , , , , on June 14, 2022 by xi'an

My PhD student Charly Andral came with the question of the birthdate of importance sampling. I was under the impression that it had been created at the same time as the plain Monte Carlo method, being essentially the same thing since

\int_{\mathfrak X} h(x)f(x)\,\text dx = \int_{\mathfrak X} h(x)\frac{f(x)}{g(x)}g(x)\,\text dx

hence due to von Neumann or Ulam, but he could not find a reference earlier than a 1949 proceeding publication by Hermann Kahn in a seminar on scientific computation run by IBM. Despite writing a series of Monte Carlo papers in the late 1940’s and 1950’s, Kahn is not well-known in these circles (although mentioned in Fishman’s book), while being popular to some extent for his theorisation of nuclear war escalation and deterence. (I wonder if the concept is developed in some of his earlier 1948 papers. In a 1951 paper with Goertzel, a footnote signals than the approach was called quota sampling in their earlier papers. Charly has actually traced the earliest proposal as being Kahn’s, in a 14 June 1949 RAND preprint, beating Goertzel’s Oak Ridge National Laboratory preprint on quota sampling and importance functions by five days.)

(As a further marginalia, Kahn wrote with T.E. Harris an earlier preprint on Monte Carlo methods in April 1949, the same Harris as in Harris recurrence.)

a film about Stan [not a film review]

Posted in Statistics with tags , , , , , , , , , , , , , on December 17, 2021 by xi'an

poster of Adventures of a Mathematician

R rexp()

Posted in Books, R, Statistics with tags , , , , , , , on May 18, 2021 by xi'an

Following a question on X validated about the reasons for coding rexp() following Ahrens & Dieter (1972) version, I re-read Luc Devroye’s explanations. Which boils down to an optimised implementation of von Neumann’s Exponential generator. The central result is that, for any μ>0, M a Geometric variate with failure probability exp(-μ) and Z a positive Poisson variate with parameter μ

\mu(M+\min(U_1,\ldots,U_Z))

is distributed as an Exp(1) random variate. Meaning that for every scale μ, the integer part and the fractional part of an Exponential variate are independent, the former a Geometric. A refinement of the above consists in choosing

exp(-μ) =½

as the generation of M then consists in counting the number of 0’s before the first 1 in the binary expansion of U∼U(0,1). Actually the loop used in Ahrens & Dieter (1972) seems to be much less efficient than counting these 0’s

> benchmark("a"={u=runif(1)
    while(u<.5){
     u=2*u
     F=F+log(2)}},
  "b"={v=as.integer(rev(intToBits(2^31*runif(1))))
     sum(cumprod(!v))},
  "c"={sum(cumprod(sample(c(0,1),32,rep=T)))},
  "g"={rgeom(1,prob=.5)},replications=1e4)
  test elapsed relative user.self 
1    a  32.92  557.966    32.885
2    b  0.123    2.085     0.122
3    c  0.113    1.915     0.106
4    g  0.059    1.000     0.058

Obviously, trying to code the change directly in R resulted in much worse performances than the resident rexp(), coded in C.