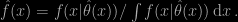Archive for Shannonś information

JSM 2024, Portland, Day 1

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , , , , , , on August 6, 2024 by xi'an

Strolling through the Oregon Conference Centre on 5 Aug, I am as always amazed at how the JSM conference centres have the ability to swallow in thousands of participants without giving an impression of overcrowding! (And appreciating the moderate air conditioning, which for once does not require wearing a fleece indoors!), I must admit that my first impressions of the city itself have been rather poor, as I was (unsuccessfully) seeking an after-hour grocery near the conference centre, I walked through run-down areas and kept passing homeless people, most in a sorry state. And hearing throughout the night, And again this morning in the warehouse maze I jogged through  before hitting the Willamette River path, which goes uninterrupted for miles. And showed me an unexpected spot, the Kevin Duckworth dock, where swimming the Willamette is feasible. Hopefully attempting a morn swim before I leave Portland.

I attended the quantum computing session, with a rather light introduction without bringing much light on the nature of qubits for storage and computing. In particular, the role of the complex coefficients of the 0 and 1 states. Then my friend Brani Vidakovic gave us an hand-on demonstration (almost hand-on as the conference facilities were unable to let a code run live!, eons away from quantum performances!!). Using Qiskit and Anaconda. He pointed out that measuring a qubit is destroying its quantum nature, the very equivalent of Schrôdinger’s cat. But does not make it clear whether or not the qubit later returns to a random entity, since frequency stabilisation is assumed, witness the histograms displayed by Brani. or a Nature paper of last year.

Went to a (poorly attended) privacy panel session next. With a defence of the value of differential privacy (Jordan Awan, Purdue) somewhat connected with our own (Ocean) work, although utility not understood in a decision-theoretic sense. And privacy remaining in an one-suits-all sense. With Michael Hawes from the US Census Bureau introducing more dimensions than mere DP (coarsening, suppression, swapping, &tc.), with legal aspects (Title 13) of disclosure risk. With the positive (for me) notion of providing a meaningful assessment of disclosure, with some records being more vulnerable than others. And another one on the cumulative disclosure risk over time. If short in quantitative entries. With Valbona Bejleri (USDA NASS, with a Census of their own) on cell suppressions and metrics for assessing disclosure, eg Shannon’s information entropy. And with Gary Howarth (Privacy Engineering Program, NIST). whose point remained rather unclear to me, like the apparently obvious point that adding features increase dispersion between populations. Although presenting tools for convincing experts and actors of the efficiency of privacy protection techniques.

Which continued (sort of) on the afternoon with a synthetic data for preserving privacy panel session. With Bradley Malin (Vanderbilt U) on the dangers of (Nature Communication paper of 2022). And Harrison Quick using a posterior predictive to achieve differential privacy, albeit considering the posterior predictive as the statistical analysis outcome does not seem the right focus (and recoup my earlier criticism of differential privacy requiring bending one’s prior beliefs). Indeed, as a Bayesian aiming at inference rather than merely at not releasing raw data, I would use synthetic data generated from that posterior predictive to return a posterior on the parameters of interest. And Joshua Snoke (RAND) with cautionary warnings. Like producing “invalid” inference because the reliance on a specific model (but isn’t that the case for most of statistics?). And Roee Gutman (Brown U), discussing the special case of record linkage. More into the difficulties in creating synthetic data. (Like the issue with missingness.) Somehow disappointing in not reaching a more statistical and quantitative perspective, eg by sticking to a Bayesian perspective the whole way.

On a non-technical side, I am surprised at hardly anyone adopting the bring-your-own-container policy in the OCC cafés, or outside, given the large number of attendees carrying one or several liquid containers.

Turing’s Bayesian contributions

Posted in Books, Kids, pictures, Running, Statistics, University life with tags , , , , , , , , , , , , on March 17, 2015 by xi'an

Following The Imitation Game, this recent movie about Alan Turing played by Benedict “Sherlock” Cumberbatch, been aired in French theatres, one of my colleagues in Dauphine asked me about the Bayesian contributions of Turing. I first tried to check in Sharon McGrayne‘s book, but realised it had vanished from my bookshelves, presumably lent to someone a while ago. (Please return it at your earliest convenience!) So I told him about the Bayesian principle of updating priors with data and prior probabilities with likelihood evidence in code detecting algorithms and ultimately machines at Bletchley Park… I could not got much farther than that and hence went checking on Internet for more fodder.

“Turing was one of the independent inventors of sequential analysis for which he naturally made use of the logarithm of the Bayes factor.” (p.393)

I came upon a few interesting entries but the most amazìng one was a 1979 note by I.J. Good (assistant of Turing during the War) published in Biometrika retracing the contributions of Alan Mathison Turing during the War. From those few pages, it emerges that Turing’s statistical ideas revolved around the Bayes factor that Turing used “without the qualification `Bayes’.” (p.393) He also introduced the notion of ban as a unit for the weight of evidence, in connection with the town of Banbury (UK) where specially formatted sheets of papers were printed “for carrying out an important classified process called Banburismus” (p.394). Which shows that even in 1979, Good did not dare to get into the details of Turing’s work during the War… And explains why he was testing simple statistical hypothesis against simple statistical hypothesis. Good also credits Turing for the expected weight of evidence, which is another name for the Kullback-Leibler divergence and for Shannon’s information, whom Turing would visit in the U.S. after the War. In the final sections of the note, Turing is also associated with Gini’s index, the estimation of the number of species (processed by Good from Turing’s suggestion in a 1953 Biometrika paper, that is, prior to Turing’s suicide. In fact, Good states in this paper that “a very large part of the credit for the present paper should be given to [Turing]”, p.237), and empirical Bayes.

optimal estimation of parameters (book review)

Posted in Books, Statistics with tags , , , , , , , on September 12, 2013 by xi'an

As I had read some of Jorma Rissanen’s papers in the early 1990’s when writing The Bayesian Choice, I was quite excited to learn that Rissanen had written a book on the optimal estimation of parameters, where he presents and develops his own approach to statistical inference (estimation and testing). As explained in the Preface this was induced by having to deliver the 2009 Shannon Lecture at the Information Theory Society conference.

“Very few statisticians have been studying information theory, the result of which, I think, is the disarray of the present discipline of statistics.” J. Rissanen (p.2)

Now that I have read the book (between Venezia in the peaceful and shaded Fundamenta Sacca San Girolamo and Hong Kong, so maybe in too a leisurely and off-handed manner), I am not so excited… It is not that the theory presented in optimal estimation of parameters is incomplete or ill-presented: the book is very well-written and well-designed, if in a highly personal (and borderline lone ranger) style. But the approach Rissanen advocates, namely maximum capacity as a generalisation of maximum likelihood, does not seem to relate to my statistical perspective and practice. Even though he takes great care to distance himself from Bayesian theory by repeating that the prior distribution is not necessary for his theory of optimal estimation (“priors are not needed in the general MDL principle”, p.4). my major source of incomprehension lies with the choice of incorporating the estimator within the data density to produce a new density, as in

\hat{f}(x) = f(x|\hat{\theta}(x)) / \int f(x|\hat{\theta}(x))\,\text{d}x\,.

Indeed, this leads to (a) replace a statistical model with a structure that mixes the model and the estimation procedure and (b) peak the new distribution by always choosing the most appropriate (local) value of the parameter. For a normal sample with unknown mean θ, this produces for instance to a joint normal distribution that is degenerate since

\hat{f}(x)\propto f(x|\bar{x}).

(For a single observation it is not even defined.) In a similar spirit, Rissanen defines this estimated model for dynamic data in a sequential manner, which means in the end that x1 is used n times, x2 n-1 times, and so on.., This asymmetry does not sound logical, especially when considering sufficiency.

“…the misunderstanding that the more parameters there are in the model the better it is because it is closer to the `truth’ and the `truth’ obviously is not simple” J. Rissanen (p.38)

Another point of contention with the approach advocated in optimal estimation of parameters is the inherent discretisation of the parameter space, which seems to exclude large dimensional spaces and complex models. I somehow subscribe to the idea that a given sample (hence a given sample size) induces a maximum precision in the estimation that can be translated into using a finite number of parameter values, but the implementation suggested in the book is essentially unidimensional. I also find the notion of optimality inherent to the statistical part of optimal estimation of parameters quite tautological as it ends up being a target that leads to the maximum likelihood estimator (or its pseudo-Bayesian counterpart).

“The BIC criterion has neither information nor a probability theoretic interpretation, and it does not matter which measure for consistency is selected.” J. Rissanen (p.64)

The first part of the book is about coding and information theory; it amounts in my understanding to a justification of the Kullback-Leibler divergence, with an early occurrence (p.27) of the above estimation distribution. (The channel capacity is the normalising constant of this weird density.)

“…in hypothesis testing [where] the assumptions that the hypotheses are  `true’ has misguided the entire field by generating problems which do not exist and distorting rational solutions to problems that do exist.” J. Rissanen (p.41)

I have issues with the definition of confidence intervals as they rely on an implicit choice of a measure and have a constant coverage that decreases with the parameter dimension. This notion also seem to clash with the subsequent discretisation of the parameter space. Hypothesis testing à la Rissanen reduces to an assessment of a goodness of fit, again with fixed coverage properties. Interestingly, the acceptance and rejection regions are based on two quantities, the likelihood ratio and the KL distance (p. 96), which leads to a delayed decision if they do not agree wrt fixed bounds.

“A drawback of the prediction formulas is that they require the knowledge of the ARMA parameters.” J. Rissanen (p.141)

A final chapter on sequential (or dynamic) models reminded me that Rissanen was at the core of inventing variable order Markov chains. The remainder of this chapter provides some properties of the sequential normalised maximum likelihood estimator advocated by the author in the same spirit as the earlier versions.  The whole chapter feels (to me) somewhat disconnected from

In conclusion, Rissanen’s book is a definitely  interesting  entry on a perplexing vision of statistics. While I do not think it will radically alter our understanding and practice of statistics, it is worth perusing, if only to appreciate there are still people (far?) out there attempting to bring a new vision of the field.