Archive for Cramèr-von Mises distance

dynamic mixtures and frequentist ABC

Posted in Statistics with tags , , , , , , , , , , , , , , , on November 30, 2022 by xi'an

This early morning in NYC, I spotted this new arXival by Marco Bee (whom I know from the time he was writing his PhD with my late friend Bernhard Flury) and found he has been working for a while on ABC related problems. The mixture model he considers therein is a form of mixture of experts, where the weights of the mixture components are not constant but functions on (0,1) of the entry as well. This model was introduced by Frigessi, Haug and Rue in 2002 and is often used as a benchmark for ABC methods, since it is missing its normalising constant as in e.g.
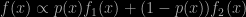
f(x) \propto p(x) f_1(x) + (1-p(x)) f_2(x)

even with all entries being standard pdfs and cdfs. Rather than using a (costly) numerical approximation of the “constant” (as a function of all unknown parameters involved), Marco follows the approximate maximum likelihood approach of my Warwick colleagues, Javier Rubio [now at UCL] and Adam Johansen. It is based on the [SAME] remark that under a uniform prior and using an approximation to the actual likelihood the MAP estimator is also the MLE for that approximation. The approximation is ABC-esque in that a pseudo-sample is generated from the true model (attached to a simulation of the parameter) and the pair is accepted if the pseudo-sample stands close enough to the observed sample. The paper proposes to use the Cramér-von Mises distance, which only involves ranks. Given this “posterior” sample, an approximation of the posterior density is constructed and then numerically optimised. From a frequentist view point, a direct estimate of the mode would be preferable. From my Bayesian perspective, this sounds like a step backwards, given that once a posterior sample is available, reconnecting with an approximate MLE does not sound highly compelling.

likelihood-free and summary-free?

Posted in Books, Mountains, pictures, Statistics, Travel with tags , , , , , , , , , , , , , on March 30, 2021 by xi'an

My friends and coauthors Chris Drovandi and David Frazier have recently arXived a paper entitled A comparison of likelihood-free methods with and without summary statistics. In which they indeed compare these two perspectives on approximate Bayesian methods like ABC and Bayesian synthetic likelihoods.

“A criticism of summary statistic based approaches is that their choice is often ad hoc and there will generally be an  inherent loss of information.”

In ABC methods, the recourse to a summary statistic is often advocated as a “necessary evil” against the greater evil of the curse of dimension, paradoxically providing a faster convergence of the ABC approximation (Fearnhead & Liu, 2018). The authors propose a somewhat generic selection of summary statistics based on [my undergrad mentors!] Gouriéroux’s and Monfort’s indirect inference, using a mixture of Gaussians as their auxiliary model. Summary-free solutions, as in our Wasserstein papers, rely on distances between distributions, hence are functional distances, that can be seen as dimension-free as well (or criticised as infinite dimensional). Chris and David consider energy distances (which sound very much like standard distances, except for averaging over all permutations), maximum mean discrepancy as in Gretton et al. (2012), Cramèr-von Mises distances, and Kullback-Leibler divergences estimated via one-nearest-neighbour formulas, for a univariate sample. I am not aware of any degree of theoretical exploration of these functional approaches towards the precise speed of convergence of the ABC approximation…

“We found that at least one of the full data approaches was competitive with or outperforms ABC with summary statistics across all examples.”

The main part of the paper, besides a survey of the existing solutions, is to compare the performances of these over a few chosen (univariate) examples, with the exact posterior as the golden standard. In the g & k model, the Pima Indian benchmark of ABC studies!, Cramèr does somewhat better. While it does much worse in an M/G/1 example (where Wasserstein does better, and similarly for a stereological extremes example of Bortot et al., 2007). An ordering inversed again for a toad movement model I had not seen before. While the usual provision applies, namely that this is a simulation study on unidimensional data and a small number of parameters, the design of the four comparison experiments is very careful, eliminating versions that are either too costly or too divergence, although this could be potentially criticised for being unrealistic (i.e., when the true posterior is unknown). The computing time is roughly the same across methods, which essentially remove the call to kernel based approximations of the likelihood. Another point of interest is that the distance methods are significantly impacted by transforms on the data, which should not be so for intrinsic distances! Demonstrating the distances are not intrinsic…