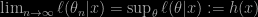Archive for maximum likelihood estimation

A modern introduction to probability and statistics [book review]

Posted in Books, R, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , , on July 12, 2025 by xi'an

In the plane to Bengaluru, I read through the book A modern introduction to probability and statistics, by Graham Upton—whose Measuring Animal Abundance I reviewed for CHANCE a while ago—, which is based on the earlier Understanding Statistics, written jointly with Ian Cook. (Not to be confused with A modern introduction to probability and statistics by Dekking et al.) The subtitle is understanding statistical principles in the computer age. Sorry, in the age of the computer. While the cover is most pleasant (and modern), as noticed by an AF flight attendant, the contents are very very standard and could have been written decades ago since the main concession to “the” computer age is the inclusion of a few R commands at the end of most chapters. There are even a few distribution tables here and there (in case “the” computer is not available). But there is no other connection with computational statistics or statistical computing.

The classicism of the contents and the intended audience mean there is little therein on which to either object or criticise. The mixture of elementary probability and basic statistics in a single textbook always feels awkward to me and I think I would have trouble teaching solely from this material. Apart from the glaring typo on the variance of the sum of two correlated random variables on page 87, missing the factor 2 in front of the covariance, while correct(ed) p97 (and the inevitable “the the” typo spotted once). My main criticisms are on the potential confusion between samples and populations in the early chapters, when some statistics are used as motivational examples, as for instance in a (hidden) Monte Carlo stabilisation to the limiting values (p57), way before the Law of Large Numbers is introduced,, the variable mileage in mathematical rigour (while being uncertain that first year students can handle integrals and derivatives), the textbook examples, and the amount of the book contents spent on descriptive statistics and even more on the “classical” tests, with no critical perspective on using point nulls or p-values. The book concludes with a four page (benevolent) chapter on Bayesian statistics that is superfluous imho, or even counterproductive since my experience with a rushed introduction to Bayesian principles almost always result in a rejection of said principles. Plus, the illustration with the coin tossing is not particularly helpful since Andrew maintains that one can load a die, but cannot bias a coin. (A similar reservation on the half-page 289 coverage on pseudo-random generation and Monte Carlo principles for computing p-values.)

Minor (mostly idiosyncratic) remarks follow: CLT prior to LLN,   n-1 in sample sd, little to no model criticism (ntbcf goodness of fit), missing an opportunity when mentioning the varying probability of a day being a birthday (p31) in contrast with BDA cover story, and another opportunity to cite the 2024 Ig Nobel Prize for coin tossing around the LLN, an unclear definition for random variables( p53) and a potentially confusing introduction of Poisson distributions through a informal reference to Poisson processes (and no reason why the years of accession of the kings of Sussex and England till Guillaume—making a return on p178 with the Domesday Book—in 1066 should follow such a process as suggested in Figure 3.5), a surprising definition of the constant e as the special case of exp(x) when x=1 and its series expansion (p70), omitting proofs on laws of sums of iid rv’s by introducing moment generating functions rather late, another obscure reference to a 16th German treatise on surveying as a precursor of the CLT (p131), a proof for the normalising constant of the Normal density that will most likely escape most first year students, a introduction of the t, F, and χ² distributions with no mention of their respective densities (pp141-147), never defining a joint Normal distribution density, insisting on unbiasedness without noting that maximum likelihood—with a strange motivation that it “makes the next sample of n observations most likely to resemble the data in the current sample (p228)—estimators are almost always biased, an abundance of footnotes that may prove of little interest for the youngest readers.

[Disclaimer about potential self-plagiarism as usual: this post or an edited version will eventually appear in my Books Review section in CHANCE.]

potato tomato [w/o ABC]

Posted in Books, pictures, Statistics with tags , , , , , , on July 8, 2022 by xi'an

“The default parameter of KaKs_Calculator was set to estimate the Ka/Ks values, which means that the Ka/Ks value was the average of the output from 15 available algorithms comprising 7 original approximate methods and one maximum likelihood method.”

In their analysis of the philogenic evolution of the potato species, the Nature authors resort to a multiple analysis (à la EJ!) in the above sense, by averaging several results. I remain puzzled by the approach that treats all methods on an equal basis, without trying to ascertain precision and bias by X validation or other tools. (Approximate Bayesian Computing was not used as one of the methods.)

individualised polychotomous logistic regression

Posted in Books, Statistics, University life with tags , , , , , on May 17, 2022 by xi'an

A recent submission to Biometrika made me read the 1984 Biometrika paper of Begg and Gray on the individualisation of polychotomous regression, namely the idea that when considering this model with T categories, the regression parameters could be estimated by considering only the pairs (0,i), 0 being the baseline category (with no parameter), since the (true) probability to be in category i conditional on being in either category 0 or category i is logistic with the same coefficient as in the polychotomous model. While I see no issue with this remark (contrary to the submission author), it is of course producing (much quicker) a different estimate of the polychotomous parameter, when compared with the full likelihood approach. Not only because it does not exploit the entire information contained in the data but also because it operates with a pseudo-likelihood.

likelihood inference with no MLE

Posted in Books, R, Statistics with tags , , , , on July 29, 2021 by xi'an

“In a regular full discrete exponential family, the MLE for the canonical parameter does not exist when the observed value of the canonical statistic lies on the boundary of its convex support.”

Daniel Eck and Charlie Geyer just published an interesting and intriguing paper on running efficient inference for discrete exponential families when the MLE does not exist.  As for instance in the case of a complete separation between 0’s and 1’s in a logistic regression model. Or more generally, when the estimated Fisher information matrix is singular. Not mentioning the Bayesian version, which remains a form of likelihood inference. The construction is based on a MLE that exists on an extended model, a notion which I had not heard previously. This model is defined as a limit of likelihood values

\lim_{n\to\infty} \ell(\theta_n|x) = \sup_\theta \ell(\theta|x) := h(x)

called the MLE distribution. Which remains a mystery to me, to some extent. Especially when this distribution is completely degenerate. Examples provided within the paper alas do not help, as they mostly serve as illustration for the associated rcdd R package. Intriguing, indeed!


training energy based models

Posted in Books, Statistics with tags , , , , , , , on April 7, 2021 by xi'an

This recent arXival by Song and Kingma covers different computational approaches to semi-parametric estimation, but also exposes imho the chasm existing between statistical and machine learning perspectives on the problem.

“Energy-based models are much less restrictive in functional form: instead of specifying a normalized probability, they only specify the unnormalized negative log-probability (…) Since the energy function does not need to integrate to one, it can be parameterized with any nonlinear regression function.”

The above in the introduction appears first as a strange argument, since the mass one constraint is the least of the problems when addressing non-parametric density estimation. Problems like the convergence, the speed of convergence, the computational cost and the overall integrability of the estimator. It seems however that the restriction or lack thereof is to be understood as the ability to use much more elaborate forms of densities, which are then black-boxes whose components have little relevance… When using such mega-over-parameterised representations of densities, such as neural networks and normalising flows, a statistical assessment leads to highly challenging questions. But convergence (in the sample size) does not appear to be a concern for the paper. (Except for a citation of Hyvärinen on p.5.)

Using MLE in this context appears to be questionable, though, since the base parameter θ is not unlikely to remain identifiable. Computing the MLE is therefore a minor issue, in this regard, a resolution based on simulated gradients being well-chartered from the earlier era of stochastic optimisation as in Robbins & Monro (1954), Duflo (1996) or Benveniste & al. (1990). (The log-gradient of the normalising constant being estimated by the opposite of the gradient of the energy at a random point.)

“Running MCMC till convergence to obtain a sample x∼p(x) can be computationally expensive.”

Contrastive divergence à la Hinton (2002) is presented as a solution to the convergence problem by stopping early, which seems reasonable given the random gradient is mostly noise. With a possible correction for bias à la Jacob & al. (missing the published version).

An alternative to MLE is the 2005 Hyvärinen score, notorious for bypassing the normalising constant. But blamed in the paper for being costly in the dimension d of the variate x, due to the second derivative matrix. Which can be avoided by using Stein’s unbiased estimator of the risk (yay!) if using randomized data. And surprisingly linked with contrastive divergence as well, if a Taylor expansion is good enough an approximation! An interesting byproduct of the discussion on score matching is to turn it into an unintended form of ABC!

“Many methods have been proposed to automatically tune the noise distribution, such as Adversarial Contrastive Estimation (Bose et al., 2018), Conditional NCE (Ceylan and Gutmann, 2018) and Flow Contrastive Estimation (Gao et al., 2020).”

A third approach is the noise contrastive estimation method of Gutmann & Hyvärinen (2010) that connects with both others. And is a precursor of GAN methods, mentioned at the end of the paper via a (sort of) variational inequality.