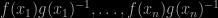Archive for SIR

mostly Monte Carlo, the return²⁵

Posted in pictures, Statistics, University life with tags , , , , , , , , , , , , , , on October 9, 2025 by xi'an

Our local Mostly (and monthly) Monte Carlo seminar is back for a new academic year, now organized by Antoine Luciano and Timothy Johnston. The first session will take place at the PariSanté Campus on Friday 17 October 2025 (3:00pm, room 07), with the organisers opening the dance, with two talks:

3pm Timothy Johnston (CEREMADE, Université Paris Dauphine–PSL): Differential Privacy of Markov Chains

Joint work with Andrea Bertazzi, Alain Durmus and Gareth Roberts

In this talk we shall discuss differential privacy, a framework for quantifying the extent to which a random output depends on the information used to produce it. After introducing several related definition of differential privacy, we shall discuss techniques used to show the differential privacy of both trajectories and single draws from Markov Chains. In doing so we shall touch on a perturbation technique which allows for Wasserstein type bounds to be converted into stronger distances like the KL and Renyi divergence.

4pm Antoine Luciano (CEREMADE, Université Paris Dauphine–PSL): Permutations accelerate Approximate Bayesian Computation

Joint work with Charly Andral, Christian P. Robert and Robin J. Ryder

Approximate Bayesian Computation (ABC) methods have become essential tools for performing inference when likelihood functions are intractable or computationally prohibitive. However, their scalability remains a major challenge in hierarchical or high-dimensional models. In this paper, we introduce permABC, a new ABC framework designed for settings with both global and local parameters, where observations are grouped into exchangeable compartments. Building upon the Sequential Monte Carlo ABC (ABC-SMC) framework, permABC exploits the exchangeability of compartments through permutation-based matching, significantly improving computational efficiency. We then develop two further, complementary sequential strategies: Over Sampling, which facilitates early-stage acceptance by temporarily increasing the number of simulated compartments, and Under Matching, which relaxes the acceptance condition by matching only subsets of the data. These techniques allow for robust and scalable inference even in high-dimensional regimes. Through synthetic and real-world experiments – including a hierarchical Susceptible-Infectious-Recover model of the early COVID-19 epidemic across 94 French departments – we demonstrate the practical gains in accuracy and efficiency achieved by our approach.

permutations accelerate ABC!

Posted in Books, Kids, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , on July 9, 2025 by xi'an

Yesterday a arXival by Antoine Luciano, Charly Andral (both PhD students, now or then, at Paris Dauphine), Robin Ryder (formerly at Paris Dauphine, now at Imperial College London) and myself got posted. It proposes to improve the scalability of ABC methods by exploiting the (full or partial) exchangeability in the data by implementing permutation-based matching between observed and simulated samples. This significantly improves computational efficiency, which is further enhanced by sequential strategies such as over-sampling, which facilitates early-stage acceptance by temporarily increasing the number of simulated compartments, and under-matching, which relaxes the acceptance condition by matching only subsets of the data. The map of France appears in connection with an application of the method to estimating SIR parameters, department by department. (It is also reminding me of the cover of Markov Chain Monte Carlo methods in practice, the 1996 contributed book edited by Wally Gilks, Sylvia Richardson and David Spiegelhalter.)

[Nature on] simulations driving the world’s response to COVID-19

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , on April 30, 2020 by xi'an

Nature of 02 April 2020 has a special section on simulation methods used to assess and predict the pandemic evolution. Calling for caution as the models used therein, like the standard ODE S(E)IR models, which rely on assumptions on the spread of the data and very rarely on data, especially in the early stages of the pandemic. One epidemiologist is quote stating “We’re building simplified representations of reality” but this is not dire enough, as “simplified” evokes “less precise” rather than “possibly grossly misleading”. (The graph above is unrelated to the Nature cover and appears to me as particularly appalling in mixing different types of data, time-scale, population at risk, discontinuous updates, and essentially returning no information whatsoever.)

“[the model] requires information that can be only loosely estimated at the start of an epidemic, such as the proportion of infected people who die, and the basic reproduction number (…) rough estimates by epidemiologists who tried to piece together the virus’s basic properties from incomplete information in different countries during the pandemic’s early stages. Some parameters, meanwhile, must be entirely assumed.”

The report mentions that the team at Imperial College, which predictions impacted the UK Government decisions, also used an agent-based model, with more variability or stochasticity in individual actions, which require even more assumptions or much more refined, representative, and trustworthy data.

“Unfortunately, during a pandemic it is hard to get data — such as on infection rates — against which to judge a model’s projections.”

Unfortunately, the paper was written in the early days of the rise of cases in the UK, which means predictions were not much opposed to actual numbers of deaths and hospitalisations. The following quote shows how far off they can fall from reality:

“the British response, Ferguson said on 25 March, makes him “reasonably confident” that total deaths in the United Kingdom will be held below 20,000.”

since the total number as of April 29 is above 21,000 24,000 29,750 and showing no sign of quickly slowing down… A quite useful general public article, nonetheless.

ABC on COVID-19

Posted in Books, pictures, Statistics, Travel with tags , , , , , , , , on March 20, 2020 by xi'an

The paper “The effect of travel restrictions on the spread of the 2019 novel coronavirus (COVID-19) outbreak”, published in Science on 06 March by Matteo Chinazzi and co-authors, considers the impact of travel restriction in Wuhan on the propagation of the virus. (Terrible graph by the way since the overall volume of traffic dropped considerably after the ban.)

“The travel quarantine of Wuhan delayed the overall epidemic progression by only 3 to 5 days in Mainland China, but has a more marked effect at the international scale, where case importations were reduced by nearly 80% until mid February.”

They use a SLIR (susceptible-latent-infectious-removed) pattern of transmission, along with a travel flow network based on 2019 air and ground travel statistics, resorting to ABC for approximating the posterior distribution of the basic reproductive number. It is however unclear to me that the model is particularly accurate at the levels of the transmission pattern (which now seems to occur much earlier than when the symptoms appear) and of the detection rates (which vary greatly from one place to another).

sampling-importance-resampling is not equivalent to exact sampling [triste SIR]

Posted in Books, Kids, Statistics, University life with tags , , , , , , on December 16, 2019 by xi'an

Following an X validated question on the topic, I reassessed a previous impression I had that sampling-importance-resampling (SIR) is equivalent to direct sampling for a given sample size. (As suggested in the above fit between a N(2,½) target and a N(0,1) proposal.)  Indeed, when one produces a sample

x_1,\ldots,x_n \stackrel{\text{i.i.d.}}{\sim} g(x)

and resamples with replacement from this sample using the importance weights

f(x_1)g(x_1)^{-1},\ldots,f(x_n)g(x_n)^{-1}

the resulting sample

y_1,\ldots,y_n

is neither “i.” nor “i.d.” since the resampling step involves a self-normalisation of the weights and hence a global bias in the evaluation of expectations. In particular, if the importance function g is a poor choice for the target f, meaning that the exploration of the whole support is imperfect, if possible (when both supports are equal), a given sample may well fail to reproduce the properties of an iid example ,as shown in the graph below where a Normal density is used for g while f is a Student t⁵ density: