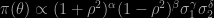Archive for Amsterdam

automatic variational ABC

Posted in pictures, Statistics with tags , , , , , , , , , , on July 8, 2016 by xi'an

Amster11“Stochastic Variational inference is an appealing alternative to the inefficient sampling approaches commonly used in ABC.”

Moreno et al. [including Ted Meeds and Max Welling] recently arXived a paper merging variational inference and ABC. The argument for turning variational is computational speedup. The traditional (in variational inference) divergence decomposition of the log-marginal likelihood is replaced by an ABC version, parameterised in terms of intrinsic generators (i.e., generators that do not depend on cyber-parameters, like the U(0,1) or the N(0,1) generators). Or simulation code in the authors’ terms. Which leads to the automatic aspect of the approach. In the paper the derivation of the gradient is indeed automated.

“One issue is that even assuming that the ABC likelihood is an unbiased estimator of the true likelihood (which it is not), taking the log introduces a bias, so that we now have a biased estimate of the lower bound and thus biased gradients.”

I wonder how much of an issue this is, since we consider the variational lower bound. To be optimised in terms of the parameters of the variational posterior. Indeed, the endpoint of the analysis is to provide an optimal variational approximation, which remains an approximation whether or not the likelihood estimator is unbiased. A more “severe” limitation may be in the inversion constraint, since it seems to eliminate Beta or Gamma distributions. (Even though calling qbeta(runif(1),a,b) definitely is achievable… And not rejected by a Kolmogorov-Smirnov test.)

Incidentally, I discovered through the paper the existence of the Kumaraswamy distribution, which main appeal seems to be the ability to produce a closed-form quantile function, while bearing some resemblance with the Beta distribution. (Another arXival by Baltasar Trancón y Widemann studies some connections between those, but does not tell how to select the parameters to optimise the similarity.)

data challenge in Sardinia

Posted in Books, Kids, R, Statistics, Travel, University life with tags , , , , , , on June 9, 2016 by xi'an

In what I hope is the first occurrence of a new part of ISBA conferences, Booking.com is launching a data challenge at ISBA 2016 next week. The prize being a trip to take part in their monthly hackathon. In Amsterdam. It would be terrific if our Bayesian conferences, including BayesComp, could gather enough data and sponsors to host an hackathon on site! (I was tempted to hold such a challenge for our estimating constants workshop last month, but Iain Murray pointed out to me the obvious difficulties of organising it from scratch…) Details will be available during the conference.

R typos

Posted in Books, Kids, R, Statistics, Travel, University life with tags , , , , , , , , on January 27, 2016 by xi'an

Amster14At MCMskv, Alexander Ly (from Amsterdam) pointed out to me some R programming mistakes I made in the introduction to Metropolis-Hastings algorithms I wrote a few months ago for the Wiley on-line encyclopedia! While the outcome (Monte Carlo posterior) of the corrected version is moderately changed this is nonetheless embarrassing! The example (if not the R code) was a mixture of a Poisson and a Geometric distributions borrowed from our testing as mixture paper. Among other things, I used a flat prior on the mixture weights instead of a Beta(1/2,1/2) prior and a simple log-normal random walk on the mean parameter instead of a more elaborate second order expansion discussed in the text. And I also inverted the probabilities of success and failure for the Geometric density. The new version is now available on arXiv, and hopefully soon on the Wiley site, but one (the?) fact worth mentioning here is that the (right) corrections in the R code first led to overflows, because I was using the Beta random walk Be(εp,ε(1-p)) which major drawback I discussed here a few months ago. With the drag that nearly zero or one values of the weight parameter produced infinite values of the density… Adding 1 (or 1/2) to each parameter of the Beta proposal solved the problem. And led to a posterior on the weight still concentrating on the correct corner of the unit interval. In any case, a big thank you to Alexander for testing the R code and spotting out the several mistakes…

re-revisiting Jeffreys

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , on October 16, 2015 by xi'an

Amster12Analytic Posteriors for Pearson’s Correlation Coefficient was arXived yesterday by Alexander Ly , Maarten Marsman, and Eric-Jan Wagenmakers from Amsterdam, with whom I recently had two most enjoyable encounters (and dinners!). And whose paper on Jeffreys’ Theory of Probability I recently discussed in the Journal of Mathematical Psychology.

The paper re-analyses Bayesian inference on the Gaussian correlation coefficient, demonstrating that for standard reference priors the posterior moments are (surprisingly) available in closed form. Including priors suggested by Jeffreys (in a 1935 paper), Lindley, Bayarri (Susie’s first paper!), Berger, Bernardo, and Sun. They all are of the form

\pi(\theta)\propto(1+\rho^2)^\alpha(1-\rho^2)^\beta\sigma_1^\gamma\sigma_2^\delta

and the corresponding profile likelihood on ρ is in “closed” form (“closed” because it involves hypergeometric functions). And only depends on the sample correlation which is then marginally sufficient (although I do not like this notion!). The posterior moments associated with those priors can be expressed as series (of hypergeometric functions). While the paper is very technical, borrowing from the Bateman project and from Gradshteyn and Ryzhik, I like it if only because it reminds me of some early papers I wrote in the same vein, Abramowitz and Stegun being one of the very first books I bought (at a ridiculous price in the bookstore of Purdue University…).

Two comments about the paper: I see nowhere a condition for the posterior to be proper, although I assume it could be the n>1+γ−2α+δ constraint found in Corollary 2.1 (although I am surprised there is no condition on the coefficient β). The second thing is about the use of this analytic expression in simulations from the marginal posterior on ρ: Since the density is available, numerical integration is certainly more efficient than Monte Carlo integration [for quantities that are not already available in closed form]. Furthermore, in the general case when β is not zero, the cost of computing infinite series of hypergeometric and gamma functions maybe counterbalanced by a direct simulation of ρ and both variance parameters since the profile likelihood of this triplet is truly in closed form, see eqn (2.11). And I will not comment the fact that Fisher ends up being the most quoted author in the paper!

importance sampling with multiple MCMC sequences

Posted in Mountains, pictures, Statistics, Travel, University life with tags , , , , , , , , , , on October 2, 2015 by xi'an

Vivek Roy, Aixian Tan and James Flegal arXived a new paper, Estimating standard errors for importance sampling estimators with multiple Markov chains, where they obtain a central limit theorem and hence standard error estimates when using several MCMC chains to simulate from a mixture distribution as an importance sampling function. Just before I boarded my plane from Amsterdam to Calgary, which gave me the opportunity to read it completely (along with half a dozen other papers, since it is a long flight!) I first thought it was connecting to our AMIS algorithm (on which convergence Vivek spent a few frustrating weeks when he visited me at the end of his PhD), because of the mixture structure. This is actually altogether different, in that a mixture is made of unnormalised complex enough densities, to act as an importance sampler, and that, due to this complexity, the components can only be simulated via separate MCMC algorithms. Behind this characterisation lurks the challenging problem of estimating multiple normalising constants. The paper adopts the resolution by reverse logistic regression advocated in Charlie Geyer’s famous 1994 unpublished technical report. Beside the technical difficulties in establishing a CLT in this convoluted setup, the notion of mixing importance sampling and different Markov chains is quite appealing, especially in the domain of “tall” data and of splitting the likelihood in several or even many bits, since the mixture contains most of the information provided by the true posterior and can be corrected by an importance sampling step. In this very setting, I also think more adaptive schemes could be found to determine (estimate?!) the optimal weights of the mixture components.