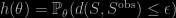Approximate Bayesian Computation (ABC) typically employs summary statistics to measure the discrepancy among the observed data and the synthetic data generated from each proposed value of the parameter of interest. However, finding good summary statistics (that are close to sufficiency) is non-trivial for most of the models for which ABC is needed. In this paper, we investigate the properties of ABC based on integral probability semi-metrics, including MMD and Wasserstein distances. We exhibit conditions ensuring the contraction of the approximate posterior. Moreover, we prove that MMD with an adequate kernel leads to very strong robustness properties.
Archive for approximate Bayesian inference
Concentration and robustness of discrepancy-based ABC [One World ABC ‘minar, 28 April]
Posted in Statistics, University life with tags ABC, Approximate Bayesian computation, approximate Bayesian inference, discrepancy, Japan, One World ABC Seminar, RIKEN, sufficiency, Tokyo, University of Warwick, Wasserstein distance, webinar on April 15, 2022 by xi'anBig Bayes postdoctoral position in Oxford [UK]
Posted in Statistics with tags ABC, approximate Bayesian inference, asymptotic Bayesian methods, big Bayes, computational complexity, ERC, European Research Council, high dimensions, Oxford, postdoctoral position, United Kingdom, University of Oxford on March 3, 2022 by xi'an
Forwarding a call for postdoctoral applications from Prof Judith Rousseau, with deadline 30 March:
Seeking a Postdoctoral Research Assistant, to join our group at the Department of Statistics. The Postdoctoral Research Assistant will be carrying out research for the ERC project General Theory for Big Bayes, reporting to Professor Judith Rousseau. They will provide guidance to junior members of the research group such as PhD students, and/or project volunteers.
The aim of this project is to develop a general theory for the analysis of Bayesian methods in complex and high (or infinite) dimensional models which will cover not only fine understanding of the posterior distributions but also an analysis of the output of the algorithms used to implement the approaches. The main objectives of the project are (briefly): 1) Asymptotic analysis of the posterior distribution of complex high dimensional models 2) Interactions between the asymptotic theory of high dimensional posterior distributions and computational complexity. We will also enrich these theoretical developments by 3) strongly related domains of applications, namely neuroscience, terrorism and crimes, and ecology.
The postholder will hold or be close to completion of a PhD/DPhil in statistics together with relevant experience. They will have the ability to manage own academic research and associated activities and have previous experience of contributing to publications/presentations. They will contribute ideas for new research projects and research income generation. Ideally, the postholder will also have experience in theoretical properties of Bayesian procedures and/or approximate Bayesian methods.
robust inference using posterior bootstrap
Posted in Books, Statistics, University life with tags approximate Bayesian inference, Bayesian GANs, cut models, Edgeworth expansions, evidence, fractional Bayes factor, harmonic mean estimator, marginal likelihood, misspecification, penalisation, Read paper, reparameterisation, seminar, University of Oxford, University of Warwick, webinar on February 18, 2022 by xi'an
The famous 1994 Read Paper by Michael Newton and Adrian Raftery was entitled Approximate Bayesian inference, where the boostrap aspect is in randomly (exponentially) weighting each observation in the iid sample through a power of the corresponding density, a proposal that happened at about the same time as Tony O’Hagan suggested the related fractional Bayes factor. (The paper may also be equally famous for suggesting the harmonic mean estimator of the evidence!, although it only appeared as an appendix to the paper.) What is unclear to me is the nature of the distribution g(θ) associated with the weighted bootstrap sample, conditional on the original sample, since the outcome is the result of a random Exponential sample and of an optimisation step. With no impact of the prior (which could have been used as a penalisation factor), corrected by Michael and Adrian via an importance step involving the estimation of g(·).
At the Algorithm Seminar today in Warwick, Emilie Pompe presented recent research, including some written jointly with Pierre Jacob, [which I have not yet read] that does exactly that inclusion of the log prior as penalisation factor, along with an extra weight different from one, as motivated by the possibility of a misspecification. Including a new approach to cut models. An alternative mentioned during the talk that reminds me of GANs is to generate a pseudo-sample from the prior predictive and add it to the original sample. (Some attendees commented on the dependence of the later version on the chosen parameterisation, which is an issue that had X’ed my mind as well.)
noisy importance sampling
Posted in Statistics with tags approximate Bayesian inference, approximate likelihood, importance sampling, Monte Carlo integration on February 14, 2022 by xi'anA recent short arXival by Fernando Llorente, Luca Martino, Jesse Read, and David Delgado–Gómez in which they analyse settings where (only) a noisy version of the target density is available. Not necessarily in an unbiased fashion although the paper is somewhat unclear as to which integral is targeted in (6), since the integrand is not the original target p(x). The following development is about finding the optimal importance function, which differs from the usual due to the random nature of the approximation, but it does not seem to reconnect with the true target p(x), except when the noisy realisation is unbiased… To me this is a major issue in simulation methodology in that getting away from the unbiasedness constraint opens (rather obviously) a much wider choice of techniques.
finding our way in the dark
Posted in Books, pictures, Statistics with tags AMIS, approximate Bayesian inference, approximate MCMC, Bayesian Analysis, Bayesian synthetic likelihood, conditional density, k nearest neighour, knn estimator, random forests, storm on November 18, 2021 by xi'an
The paper Finding our Way in the Dark: Approximate MCMC for Approximate Bayesian Methods by Evgeny Levi and (my friend) Radu Craiu, recently got published in Bayesian Analysis. The central motivation for their work is that both ABC and synthetic likelihood are costly methods when the data is large and does not allow for smaller summaries. That is, when summaries S of smaller dimension cannot be directly simulated. The idea is to try to estimate
since this is the substitute for the likelihood used for ABC. (A related idea is to build an approximate and conditional [on θ] distribution on the distance, idea with which Doc. Stoehr and I played a wee bit without getting anything definitely interesting!) This is a one-dimensional object, hence non-parametric estimates could be considered… For instance using k-nearest neighbour methods (which were already linked with ABC by Gérard Biau and co-authors.) A random forest could also be used (?). Or neural nets. The method still requires a full simulation of new datasets, so I wonder at the gain unless the replacement of the naïve indicator with h(θ) brings clear improvement to the approximation. Hence much fewer simulations. The ESS reduction is definitely improved, esp. since the CPU cost is higher. Could this be associated with the recourse to independent proposals?
In a sence, Bayesian synthetic likelihood does not convey the same appeal, since is a bit more of a tough cookie: approximating the mean and variance is multidimensional. (BSL is always more expensive!)
As a side remark, the authors use two chains in parallel to simplify convergence proofs, as we did a while ago with AMIS!