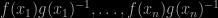Archive for asymptotics

sampling-importance-resampling is not equivalent to exact sampling [triste SIR]

Posted in Books, Kids, Statistics, University life with tags , , , , , , on December 16, 2019 by xi'an

Following an X validated question on the topic, I reassessed a previous impression I had that sampling-importance-resampling (SIR) is equivalent to direct sampling for a given sample size. (As suggested in the above fit between a N(2,½) target and a N(0,1) proposal.)  Indeed, when one produces a sample

x_1,\ldots,x_n \stackrel{\text{i.i.d.}}{\sim} g(x)

and resamples with replacement from this sample using the importance weights

f(x_1)g(x_1)^{-1},\ldots,f(x_n)g(x_n)^{-1}

the resulting sample

y_1,\ldots,y_n

is neither “i.” nor “i.d.” since the resampling step involves a self-normalisation of the weights and hence a global bias in the evaluation of expectations. In particular, if the importance function g is a poor choice for the target f, meaning that the exploration of the whole support is imperfect, if possible (when both supports are equal), a given sample may well fail to reproduce the properties of an iid example ,as shown in the graph below where a Normal density is used for g while f is a Student t⁵ density:

asymptotics of M³C²L

Posted in Statistics with tags , , , , , , , on August 19, 2018 by xi'an
In a recent arXival, Blazej Miasojedow, Wojciech Niemiro and Wojciech Rejchel establish the convergence of a maximum likelihood estimator based on an MCMC approximation of the likelihood function. As in intractable normalising constants. The main result in the paper is a Central Limit theorem for the M³C²L estimator that incorporates an additional asymptotic variance term for the Monte Carlo error. Where both the sample size n and the number m of simulations go to infinity. Independently so. However, I do not fully perceive the relevance of using an MCMC chain to target an importance function [which is used in the approximation of the normalising constant or otherwise for the intractable likelihood], relative to picking an importance function h(.) that can be directly simulated.

a paradox about likelihood ratios?

Posted in Books, pictures, Statistics, University life with tags , , , , , , , on January 15, 2018 by xi'an

Aware of my fascination for paradoxes (and heterodox publications), Ewan Cameron sent me the link to a recent arXival by Louis Lyons (Oxford) on different asymptotic distributions of the likelihood ratio. Which is full of approximations. The overall point of the note is hard to fathom… Unless it simply plans to illustrate Betteridge’s law of headlines, as suggested by Ewan.

For instance, the limiting distribution of the log-likelihood of an exponential sample at the true value of the parameter τ is not asymptotically Gaussian but almost surely infinite. While the log of the (Wilks) likelihood ratio at the true value of τ is truly (if asymptotically) a Χ² variable with one degree of freedom. That it is not a Gaussian is deemed a “paradox” by the author, explained by a cancellation of first order terms… Same thing again for the common Gaussian mean problem!

talk at Trinity College

Posted in pictures, Statistics, Travel, University life with tags , , , , , , , on May 7, 2017 by xi'an

Tomorrow noon, I will give a talk at Trinity College Dublin on the asymptotic properties of ABC. (Here are the slides from the talk I gave in Berlin last month.)

SAS on Bayes

Posted in Books, Kids, pictures, R, Statistics, University life with tags , , , , , , , on November 8, 2016 by xi'an

Following a question on X Validated, I became aware of the following descriptions of the pros and cons of Bayesian analysis, as perceived by whoever (Tim Arnold?) wrote SAS/STAT(R) 9.2 User’s Guide, Second Edition. I replied more specifically on the point

It [Bayesian inference] provides inferences that are conditional on the data and are exact, without reliance on asymptotic approximation. Small sample inference proceeds in the same manner as if one had a large sample. Bayesian analysis also can estimate any functions of parameters directly, without using the “plug-in” method (a way to estimate functionals by plugging the estimated parameters in the functionals).

which I find utterly confusing and not particularly relevant. The other points in the list are more traditional, except for this one

It provides interpretable answers, such as “the true parameter θ has a probability of 0.95 of falling in a 95% credible interval.”

that I find somewhat unappealing in that the 95% probability has only relevance wrt to the resulting posterior, hence has no absolute (and definitely no frequentist) meaning. The criticisms of the prior selection

It does not tell you how to select a prior. There is no correct way to choose a prior. Bayesian inferences require skills to translate subjective prior beliefs into a mathematically formulated prior. If you do not proceed with caution, you can generate misleading results.

It can produce posterior distributions that are heavily influenced by the priors. From a practical point of view, it might sometimes be difficult to convince subject matter experts who do not agree with the validity of the chosen prior.

are traditional but nonetheless irksome. Once acknowledged there is no correct or true prior, it follows naturally that the resulting inference will depend on the choice of the prior and has to be understood conditional on the prior, which is why the credible interval has for instance an epistemic rather than frequentist interpretation. There is also little reason for trying to convince a fellow Bayesian statistician about one’s prior. Everything is conditional on the chosen prior and I see less and less why this should be an issue.