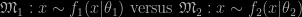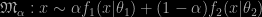
Archive for Bayesian hypothesis testing

eliminating an important obstacle to creative thinking: statistics…

Posted in Books, Kids, Statistics, University life with tags , , , , , , , , , , , , , on March 12, 2015 by xi'an

“We hope and anticipate that banning the NHSTP will have the effect of increasing the quality of submitted manuscripts by liberating authors from the stultified structure of NHSTP thinking thereby eliminating an important obstacle to creative thinking.”

About a month ago, David Trafimow and Michael Marks, the current editors of the journal Basic and Applied Social Psychology published an editorial banning all null hypothesis significance testing procedures (acronym-ed into the ugly NHSTP which sounds like a particularly nasty venereal disease!) from papers published by the journal. My first reaction was “Great! This will bring more substance to the papers by preventing significance fishing and undisclosed multiple testing! Power to the statisticians!” However, after reading the said editorial, I realised it was inspired by a nihilistic anti-statistical stance, backed by an apparent lack of understanding of the nature of statistical inference, rather than a call for saner and safer statistical practice. The editors most clearly state that inferential statistical procedures are no longer needed to publish in the journal, only “strong descriptive statistics”. Maybe to keep in tune with the “Basic” in the name of the journal!

“In the NHSTP, the problem is in traversing the distance from the probability of the finding, given the null hypothesis, to the probability of the null hypothesis, given the finding. Regarding confidence intervals, the problem is that, for example, a 95% confidence interval does not indicate that the parameter of interest has a 95% probability of being within the interval.”

The above quote could be a motivation for a Bayesian approach to the testing problem, a revolutionary stance for journal editors!, but it only illustrate that the editors wish for a procedure that would eliminate the uncertainty inherent to statistical inference, i.e., to decision making under… erm, uncertainty: “The state of the art remains uncertain.” To fail to separate significance from certainty is fairly appalling from an epistemological perspective and should be a case for impeachment, were any such thing to exist for a journal board. This means the editors cannot distinguish data from parameter and model from reality! Even more fundamentally, to bar statistical procedures from being used in a scientific study is nothing short of reactionary. While encouraging the inclusion of data is a step forward, restricting the validation or in-validation of hypotheses to gazing at descriptive statistics is many steps backward and does completely jeopardize the academic reputation of the journal, which editorial may end up being the last quoted paper. Is deconstruction now reaching psychology journals?! To quote from a critic of this approach, “Thus, the general weaknesses of the deconstructive enterprise become self-justifying. With such an approach I am indeed not sympathetic.” (Searle, 1983).

“The usual problem with Bayesian procedures is that they depend on some sort of Laplacian assumption to generate numbers where none exist (…) With respect to Bayesian procedures, we reserve the right to make case-by-case judgments, and thus Bayesian procedures are neither required nor banned from BASP.”

The section of Bayesian approaches is trying to be sympathetic to the Bayesian paradigm but again reflects upon the poor understanding of the authors. By “Laplacian assumption”, they mean Laplace´s Principle of Indifference, i.e., the use of uniform priors, which is not seriously considered as a sound principle since the mid-1930’s. Except maybe in recent papers of Trafimow. I also love the notion of “generat[ing] numbers when none exist”, as if the prior distribution had to be grounded in some physical reality! Although it is meaningless, it has some poetic value… (Plus, bringing Popper and Fisher to the rescue sounds like shooting Bayes himself in the foot.)  At least, the fact that the editors will consider Bayesian papers in a case-by-case basis indicate they may engage in a subjective Bayesian analysis of each paper rather than using an automated p-value against the 100% rejection bound!

[Note: this entry was suggested by Alexandra Schmidt, current ISBA President, towards an incoming column on this decision of Basic and Applied Social Psychology for the ISBA Bulletin.]


Harold Jeffreys’ default Bayes factor [for psychologists]

Posted in Books, Statistics, University life with tags , , , , , , on January 16, 2015 by xi'an

“One of Jeffreys’ goals was to create default Bayes factors by using prior distributions that obeyed a series of general desiderata.”

The paper Harold Jeffreys’s default Bayes factor hypothesis tests: explanation, extension, and application in Psychology by Alexander Ly, Josine Verhagen, and Eric-Jan Wagenmakers is both a survey and a reinterpretation cum explanation of Harold Jeffreys‘ views on testing. At about the same time, I received a copy from Alexander and a copy from the journal it had been submitted to! This work starts with a short historical entry on Jeffreys’ work and career, which includes four of his principles, quoted verbatim from the paper:

  1. “scientific progress depends primarily on induction”;
  2. “in order to formalize induction one requires a logic of partial belief” [enters the Bayesian paradigm];
  3. “scientific hypotheses can be assigned prior plausibility in accordance with their complexity” [a.k.a., Occam’s razor];
  4. “classical “Fisherian” p-values are inadequate for the purpose of hypothesis testing”.

“The choice of π(σ)  therefore irrelevant for the Bayes factor as long as we use the same weighting function in both models”

A very relevant point made by the authors is that Jeffreys only considered embedded or nested hypotheses, a fact that allows for having common parameters between models and hence some form of reference prior. Even though (a) I dislike the notion of “common” parameters and (b) I do not think it is entirely legit (I was going to write proper!) from a mathematical viewpoint to use the same (improper) prior on both sides, as discussed in our Statistical Science paper. And in our most recent alternative proposal. The most delicate issue however is to derive a reference prior on the parameter of interest, which is fixed under the null and unknown under the alternative. Hence preventing the use of improper priors. Jeffreys tried to calibrate the corresponding prior by imposing asymptotic consistency under the alternative. And exact indeterminacy under “completely uninformative” data. Unfortunately, this is not a well-defined notion. In the normal example, the authors recall and follow the proposal of Jeffreys to use an improper prior π(σ)∝1/σ on the nuisance parameter and argue in his defence the quote above. I find this argument quite weak because suddenly the prior on σ becomes a weighting function... A notion foreign to the Bayesian cosmology. If we use an improper prior for π(σ), the marginal likelihood on the data is no longer a probability density and I do not buy the argument that one should use the same measure with the same constant both on σ alone [for the nested hypothesis] and on the σ part of (μ,σ) [for the nesting hypothesis]. We are considering two spaces with different dimensions and hence orthogonal measures. This quote thus sounds more like wishful thinking than like a justification. Similarly, the assumption of independence between δ=μ/σ and σ does not make sense for σ-finite measures. Note that the authors later point out that (a) the posterior on σ varies between models despite using the same data [which shows that the parameter σ is far from common to both models!] and (b) the [testing] Cauchy prior on δ is only useful for the testing part and should be replaced with another [estimation] prior when the model has been selected. Which may end up as a backfiring argument about this default choice.

“Each updated weighting function should be interpreted as a posterior in estimating σ within their own context, the model.”

The re-derivation of Jeffreys’ conclusion that a Cauchy prior should be used on δ=μ/σ makes it clear that this choice only proceeds from an imperative of fat tails in the prior, without solving the calibration of the Cauchy scale. (Given the now-available modern computing tools, it would be nice to see the impact of this scale γ on the numerical value of the Bayes factor.) And maybe it also proceeds from a “hidden agenda” to achieve a Bayes factor that solely depends on the t statistic. Although this does not sound like a compelling reason to me, since the t statistic is not sufficient in this setting.

In a differently interesting way, the authors mention the Savage-Dickey ratio (p.16) as a way to represent the Bayes factor for nested models, without necessarily perceiving the mathematical difficulty with this ratio that we pointed out a few years ago. For instance, in the psychology example processed in the paper, the test is between δ=0 and δ≥0; however, if I set π(δ=0)=0 under the alternative prior, which should not matter [from a measure-theoretic perspective where the density is uniquely defined almost everywhere], the Savage-Dickey representation of the Bayes factor returns zero, instead of 9.18!

“In general, the fact that different priors result in different Bayes factors should not come as a surprise.”

The second example detailed in the paper is the test for a zero Gaussian correlation. This is a sort of “ideal case” in that the parameter of interest is between -1 and 1, hence makes the choice of a uniform U(-1,1) easy or easier to argue. Furthermore, the setting is also “ideal” in that the Bayes factor simplifies down into a marginal over the sample correlation only, under the usual Jeffreys priors on means and variances. So we have a second case where the frequentist statistic behind the frequentist test[ing procedure] is also the single (and insufficient) part of the data used in the Bayesian test[ing procedure]. Once again, we are in a setting where Bayesian and frequentist answers are in one-to-one correspondence (at least for a fixed sample size). And where the Bayes factor allows for a closed form through hypergeometric functions. Even in the one-sided case. (This is a result obtained by the authors, not by Jeffreys who, as the proper physicist he was, obtained approximations that are remarkably accurate!)

“The fact that the Bayes factor is independent of the intention with which the data have been collected is of considerable practical importance.”

The authors have a side argument in this section in favour of the Bayes factor against the p-value, namely that the “Bayes factor does not depend on the sampling plan” (p.29), but I find this fairly weak (or tongue in cheek) as the Bayes factor does depend on the sampling distribution imposed on top of the data. It appears that the argument is mostly used to defend sequential testing.

“The Bayes factor (…) balances the tension between parsimony and goodness of fit, (…) against overfitting the data.”

In fine, I liked very much this re-reading of Jeffreys’ approach to testing, maybe the more because I now think we should get away from it! I am not certain it will help in convincing psychologists to adopt Bayes factors for assessing their experiments as it may instead frighten them away. And it does not bring an answer to the vexing issue of the relevance of point null hypotheses. But it constitutes a lucid and innovative of the major advance represented by Jeffreys’ formalisation of Bayesian testing.

the demise of the Bayes factor

Posted in Books, Kids, Statistics, Travel, University life with tags , , , , , , , , on December 8, 2014 by xi'an

alphaPost1nalphaPost2n

With Kaniav Kamary, Kerrie Mengersen, and Judith Rousseau, we have just arXived (and submitted) a paper entitled “Testing hypotheses via a mixture model”. (We actually presented some earlier version of this work in Cancũn, Vienna, and Gainesville, so you may have heard of it already.) The notion we advocate in this paper is to replace the posterior probability of a model or an hypothesis with the posterior distribution of the weights of a mixture of the models under comparison. That is, given two models under comparison,

\mathfrak{M}_1:x\sim f_1(x|\theta_1) \text{ versus } \mathfrak{M}_2:x\sim f_2(x|\theta_2)

we propose to estimate the (artificial) mixture model

\mathfrak{M}_{\alpha}:x\sim\alpha f_1(x|\theta_1) + (1-\alpha) f_2(x|\theta_2)

and in particular derive the posterior distribution of α. One may object that the mixture model is neither of the two models under comparison but this is the case at the boundary, i.e., when α=0,1. Thus, if we use prior distributions on α that favour the neighbourhoods of 0 and 1, we should be able to see the posterior concentrate near 0 or 1, depending on which model is true. And indeed this is the case: for any given Beta prior on α, we observe a higher and higher concentration at the right boundary as the sample size increases. And establish a convergence result to this effect. Furthermore, the mixture approach offers numerous advantages, among which [verbatim from the paper]:

Continue reading →

posterior likelihood ratio is back

Posted in Statistics, University life with tags , , , , , , , , , on June 10, 2014 by xi'an

“The PLR turns out to be a natural Bayesian measure of evidence of the studied hypotheses.”

Isabelle Smith and André Ferrari just arXived a paper on the posterior distribution of the likelihood ratio. This is in line with Murray Aitkin’s notion of considering the likelihood ratio

f(x|\theta_0) / f(x|\theta)

as a prior quantity, when contemplating the null hypothesis that θ is equal to θ0. (Also advanced by Alan Birnbaum and Arthur Dempster.) A concept we criticised (rather strongly) in our Statistics and Risk Modelling paper with Andrew Gelman and Judith Rousseau.  The arguments found in the current paper in defence of the posterior likelihood ratio are quite similar to Aitkin’s:

  • defined for (some) improper priors;
  • invariant under observation or parameter transforms;
  • more informative than tthe posterior mean of the posterior likelihood ratio, not-so-incidentally equal to the Bayes factor;
  • avoiding using the posterior mean for an asymmetric posterior distribution;
  • achieving some degree of reconciliation between Bayesian and frequentist perspectives, e.g. by being equal to some p-values;
  • easily computed by MCMC means (if need be).

One generalisation found in the paper handles the case of composite versus composite hypotheses, of the form

\int\mathbb{I}\left( p(x|\theta_1)<p(x|\theta_0)\right)\pi(\text{d}\theta_1|x)\pi(\text{d}\theta_0|x)

which brings back an earlier criticism I raised (in Edinburgh, at ICMS, where as one-of-those-coincidences, I read this paper!), namely that using the product of the marginals rather than the joint posterior is no more a standard Bayesian practice than using the data in a prior quantity. And leads to multiple uses of the data. Hence, having already delivered my perspective on this approach in the past, I do not feel the urge to “raise the flag” once again about a paper that is otherwise well-documented and mathematically rich.