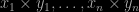Archive for Benford’s Law

More on Benford’s Law

Posted in Statistics with tags , , , , on July 10, 2009 by xi'an

In connection with an earlier post on Benford’s Law, i.e. the probability that the first digit of a random variable X is1\le k\le 9is approximately\log\{(k+1)/k\}—you can easily check that the sum of those probabilities is 1—, I want to signal a recent entry on Terry Tiao’s impressive blog. Terry points out that Benford’s Law is the Haar measure in that setting, but he also highlights a very peculiar absorbing property which is that, ifXfollows Benford’s Law, thenXYalso follows Benford’s Law for any random variableYthat is independent fromX… Now, the funny thing is that, if you take a normal samplex_1,\ldots,x_nand check whether or not Benford’s Law applies to this sample, it does not. But if you take a second normal sampley_1,\ldots,y_nand consider the product samplex_1\times y_1,\ldots,x_n\times y_n, then Benford’s Law applies almost exactly. If you repeat the process one more time, it is difficult to spot the difference. Here is the [rudimentary—there must be a more elegant way to get the first significant digit!] R code to check this:

x=abs(rnorm(10^6))
b=trunc(log10(x)) -(log(x)<0)
plot(hist(trunc(x/10^b),breaks=(0:9)+.5)$den,log10((2:10)/(1:9)),
    xlab="Frequency",ylab="Benford's Law",pch=19,col="steelblue")
abline(a=0,b=1,col="tomato",lwd=2)
x=abs(rnorm(10^6)*x)
b=trunc(log10(x)) -(log(x)<0)
points(hist(trunc(x/10^b),breaks=(0:9)+.5,plot=F)$den,log10((2:10)/(1:9)),
    pch=19,col="steelblue2")
x=abs(rnorm(10^6)*x)
b=trunc(log10(x)) -(log(x)<0)
    points(hist(trunc(x/10^b),breaks=(0:9)+.5,plot=F)$den,log10((2:10)/(1:9)),
pch=19,col="steelblue3")

Even better, if you change rnorm to another generator like rcauchy or rexp at any of the three stages, the same pattern occurs.

More/less incriminating digits from the Iranian election

Posted in Statistics with tags , , , , , , on June 21, 2009 by xi'an

Following my previous post where I commented on Roukema’s use of Benford’s Law on the first digits of the counts, I saw on Andrew Gelman’s blog a pointer to a paper in the Washington Post, where the arguments are based instead on the last digit. Those should be uniform, rather than distributed from Benford’s Law, There is no doubt about the uniformity of the last digit, but the claim for “extreme unlikeliness” of the frequencies of those digits made in the paper is not so convincing. Indeed, when I uniformly sampled 116 digits in {0,..,9}, my very first attempt produced the highest frequency to be 20.5% and the lowest to be 5.9%. If I run a small Monte Carlo experiment with the following R program,

fre=0
for (t in 1:10^4){
   h=hist(sample(0:9,116,rep=T),plot=F)$inten;
   fre=fre+(max(h)>.16)*(min(h)<.05)
   }

the percentage of cases when this happens is 15%, so this is not “extremely unlikely” (unless I made a terrible blunder in the above!!!)… Even moving the constraint to

(max(h)>.169)*(min(h)<.041)

does not produce a very unlikely probability, since it is then 0.0525.

The second argument looks at the proportion of last and second-to-last digits that are adjacent, i.e. with a difference of ±1 or ±9. Out of the 116 Iranian results, 62% are made of non-adjacent digits. If I sample two vectors of 116 digits in {0,..,9} and if I consider this occurrence, I do see an unlikely event. Running the Monte Carlo experiment

repa=NULL
for (t in 1:10^5){
    dife=(sample(0:9,116,rep=T)-sample(0:9,116,rep=T))^2
    repa[t]=sum((dife==1))+sum((dife==81))
    }
repa=repa/116

shows that the distribution of repa is centered at .20—as it should, since for a given second-to-last digit, there are two adjacent last digits—, not .30 as indicated in the paper, and that the probability of having a frequency of .38 or more of adjacent digit is estimated as zero by this Monte Carlo experiment. (Note that I took 0 and 9 to be adjacent and that removing this occurrence would further lower the probability.)

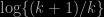
Benford’s Law satisfies Stigler’s Law

Posted in Books, Statistics, University life with tags , , , , on June 18, 2009 by xi'an

Looking around for other entries on Benford’s Law, I found this nice entry that attributes Benford’s Law to the astronomer Simon Newcomb, instead of Benford (who rediscovered the distribution fifty years later). This is quite in line with Stigler’s Law of Eponymy, which states that (almost) no scientific law is named after its original discoverer. The post of Peter Coles also covers the connection between Benford’s Law and Jeffreys’ prior for scale parameters, which is discussed in Jim Berger’s Statistical Decision Theory and Bayesian Analysis.

Anomalies in the Iranian election

Posted in Statistics with tags , , on June 17, 2009 by xi'an

While the results of the recent Iranian presidential election are currently severely contested, with accusations of fraud and manipulations, and with an level of protest unheard of in Iran, I had not so far seen a statistical analysis of the votes. This is over: Boudewijn Roukema, a cosmologist with the University of Toruń (Poland), has produced an analysis of the figures published by the Iranian Ministry of the Interior, based on Benford’s Law for the repartition of the first digit i in decimal representations of real numbers, which should be

f(i) \propto \log_{10}(1+\frac{1}{i})

for the proportion of votes for a candidate among the four in competition. Roukema exhibits a very unlikely discrepancy on Mehdi Karoubi’s votes, with an extremely high occurence of the digit 7. There is also a discrepancy for Mahmoud Ahmadinejad’s frequencies of 1’s and 2’s that is harder to detect because of the higher frequency of votes for this candidate in the Iranian Ministry of the Interior data. But looking at the most populous districts, Roukema concludes that several million votes could have been added to Ahmadinejad’s votes in those areas, if Benford’s Law holds…

I find this analysis produced merely five days after the election quite astounding, even though the validity of applying Benford’s Law in those circumstances needs more backup…