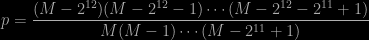Archive for birthday

five years ‘Oggin’…!

Posted in Books, Kids, Linux, Mountains, pictures, Running, Statistics, Travel, University life, Wines with tags , on October 2, 2013 by xi'an

(past) sunset over Kata Tjuta (Mounts Olga); Northern Territory, Australia, Aug. 6, 2012I have just been reminded by wordpress that it has been five years since I started this blog,.. With about 2500 posts, more than 800,000 views and 4,500 comments (thanks to Deborah, Dan, Julien, and Arnaud!). Thanks to all readers for being supportive and to the hardcore readers for being always there, despite the lack of constancy, the unreasonable amount of silly posts, and the abuse of saturated pictures. I cannot predict if the ‘Og will last much longer, for the times they are a-changin’, but those have been fun five years!

Come writers and critics
Who prophesize with your pen
And keep your eyes wide
The chance won’t come again
And don’t speak too soon
For the wheel’s still in spin
And there’s no tellin’ who
That it’s namin’
For the loser now
Will be later to win
For the times they are a-changin’.

Singapore sunset

Posted in Kids, pictures, Travel with tags , , , on August 25, 2012 by xi'an

the birthday problem [X’idated]

Posted in R, Statistics, University life with tags , , , on February 1, 2012 by xi'an

The birthday problem (i.e. looking at the distribution of the birthdates in a group of n persons, assuming [wrongly] a uniform distribution of the calendar dates of those birthdates) is always a source of puzzlement [for me]! For instance, here is a recent post on Cross Validated:

I have 360 friends on facebook, and, as expected, the distribution of their birthdays is not uniform at all. I have one day with that has 9 friends with the same birthday. So, given that some days are more likely for a birthday, I’m assuming the number of 23 is an upperbound.

The figure 9 sounded unlikely, so I ran the following computation:

[sourcecode language=”r” gutter=”false”]
extreme=rep(0,360)
for (t in 1:10^5){
i=max(diff((1:360)[!duplicated(sort(sample(1:365,360,rep=TRUE)))]))
extreme[i]=extreme[i]+1
}
extreme=extreme/10^5
barplot(extreme,xlim=c(0,30),names=1:360)
[/sourcecode]

whose output shown on the above graph. (Actually, I must confess I first forgot the sort in the code, which led me to then believe that 9 was one of the most likely values and post it on Cross Validated! The error was eventually picked by one administrator. I should know better than trust my own R code!) According to this simulation, observing 9 or more people having the same birthdate has an approximate probability of 0.00032… Indeed, fairly unlikely!

Incidentally, this question led me to uncover how to print the above on this webpage. And to learn from the X’idated moderator whuber the use of tabulate. Which avoids the above loop:

[sourcecode language=”r” gutter=”false”]
> system.time(test(10^5)) #my code above
user  system elapsed
26.230   0.028  26.411
> system.time(table(replicate(10^5, max(tabulate(sample(1:365,360,rep=TRUE))))))
user  system elapsed
5.708   0.044   5.762
[/sourcecode]

Common ancestors

Posted in Statistics with tags , , , , on June 8, 2011 by xi'an

In conjunction with President Obama’s visit to Ireland two weeks ago and in particular to his ancestral Irish town, I happened to glance at his family tree and saw that he shared a common ancestor with George W. Bush. (They are 11th cousins, meaning that a 12th-order ancestor is common to both their  family trees.) This sounds at first amazing, but it is another occurrence of the (von Mises) birthday problem. (The fact that it is not that amazing is demonstrated by the simultaneous presence of [French!] ancestors of Dick Cheney in the same tree.) If we consider President Obama’s mother side, the probability that all of her 11th-order ancestors differ from all of George W. Bush’s 12th-order ancestors is

p=\dfrac{(M-2^{12})(M-2^{12}-1)\cdots(M-2^{12}-2^{11}+1)}{M(M-1)\cdots(M-2^{11}+1)}

where M denotes the whole population of potential ancestors at this period. If we consider all those ancestors as coming from the British Isles, then about 1650, the population was about 8 million. This would lead to a probability of p=0.35, i.e. there is a 65% chance that they share a 12th-order ancestor. If instead we consider the whole European population at that time (if only to include German and French ancestors to President Obama), M is about 100 million and the probability increases to p=0.92, so there is then an 8% probability for them to share an ancestor. Obviously, this rough calculation relies on simplifying assumptions, avoiding the issue of inbreeding which means that the potential 2¹¹ ancestors are in fact much less than 2¹¹, and the fact that their ancestors are necessarily emigrants, which reduces the value of M… (This post appeared yesterday on the Statistics Forum.)

Typo in Chapter 5

Posted in Books, R, Statistics with tags , , , , , , on September 9, 2010 by xi'an

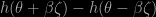
Gilles Guillot from Technical University of Denmark taught a course based on our R book and he pointed out to me several typos in Chapter 5 of “Introducing Monte Carlo Methods with R”:
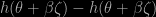
  • p.137 second equation from bottom

    h(\theta+\beta \zeta) - h(\theta+\beta \zeta)

    should be

    h(\theta+\beta \zeta) - h(\theta-\beta \zeta)

    [right, another victim of cut-and-paste]

  • p. 138  Example 5.7 denominator in the gradient should be 2*beta [yes, the error actually occurs twice. And once again in the R code]
  • p. 138 : First paragraph Not a typo but a lack of details: are the conditions on \alpha and \beta necessary and sufficient? [indeed, they are sufficient]
  • demo(Chapter.5) triggers an error message [true, the shortcut max=TRUE instead of maximise=TRUE in optimise does not work with R version 2.11.1]

Continue reading →