 The recent arXival by Takashi Goda of Computing the variance of a conditional expectation via non-nested Monte Carlo led me to read it as I could not be certain of the contents from only reading the title! The short paper considers the issue of estimating the variance of a conditional expectation when able to simulate the joint distribution behind the quantity of interest. The second moment E(E[f(X)|Y]²) can be written as a triple integral with two versions of x given y and one marginal y, which means that it can approximated in an unbiased manner by simulating a realisation of y then conditionally two realisations of x. The variance requires a third simulation of x, which the author seems to deem too costly and that he hence replaces with another unbiased version based on two conditional generations only. (He notes that a faster biased version is available with bias going down faster than the Monte Carlo error, which makes the alternative somewhat irrelevant, as it is also costly to derive.) An open question after reading the paper stands with the optimal version of the generic estimator (5), although finding the optimum may require more computing time than it is worth spending. Another one is whether or not this version of the expected conditional variance is more interesting (computation-wise) that the difference between the variance and the expected conditional variance as reproduced in (3) given that both quantities can equally be approximated by unbiased Monte Carlo…
Archive for debiasing
Computing the variance of a conditional expectation via non-nested Monte Carlo
Posted in Books, pictures, Statistics, University life with tags conditional probability, debiasing, Monte Carlo approximations, Monte Carlo Statistical Methods, Rao-Blackwellisation on May 26, 2016 by xi'anmore e’s [and R’s]
Posted in Kids, pictures, R, Statistics with tags cross validated, debiasing, George Forsythe, Monte Carlo Statistical Methods, R, Russian roulette, simulation, unbiased estimation on February 22, 2016 by xi'an Alex Thiéry suggested debiasing the biased estimate of e by Rhee and Glynn truncated series method, so I tried the method to see how much of an improvement (if any!) this would bring. I first attempted to naïvely implement the raw formula of Rhee and Glynn
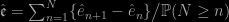
with a (large) Poisson distribution on the stopping rule N, but this took ages. I then realised that the index n did not have to be absolute, i.e. to start at n=1 and proceed snailwise one integer at a time: the formula remains equally valid after a change of time, i.e. n=can start at an arbitrary value and proceeds by steps of arbitrary size, which obviously speeds things up! Continue reading


