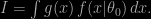Archive for decision theory

is atheism irrational?

Posted in Books, Kids with tags , , , , , , , on March 2, 2014 by xi'an

“If a belief is as likely to be false as to be true, we’d have to say the probability that any particular belief is true is about 50 percent. Now suppose we had a total of 100 independent beliefs (of course, we have many more). Remember that the probability that all of a group of beliefs are true is the multiplication of all their individual probabilities. Even if we set a fairly low bar for reliability — say, that at least two-thirds (67 percent) of our beliefs are true — our overall reliability, given materialism and evolution, is exceedingly low: something like .0004. So if you accept both materialism and evolution, you have good reason to believe that your belief-producing faculties are not reliable.”

On the (New York Times) philosophy blog The Stone, I spotted this entry and first wondered if I had misread the title, as atheism sounds (to me) as a most rational position. I then read the piece and found it mostly missing, even though a few points rang true(r). First, theism is never properly defined. (Even though the author Alvin Plantinga seems to stick to monotheist religions.) This is a not-so-subtle trick as it makes atheism appear as the extreme position, since it is rejecting any form of theism! Then, the interviewee is mostly using a sequence of sophisms as arguments that atheists are irrational, see e.g. the even-star-ism and a-moonism and a-teapotism entries. Further, some of his entries very strongly resemble intelligent design arguments, e.g. the “fine-tuning” line that the universe is too perfectly suited to human life to be due to randomness. Even though Plantinga also resorts to evolution when needed, as in the above quote. (The interviewer is not doing a great job either, by referring to evil, or the need (or lack thereof) of God versus science to explain the world. Rather than resorting to rational arguments. And without mentioning the fundamental point in favour of atheism that the existence of a sentient being driving the whole universe while remaining hidden to us humans requires an infinitely stronger step than arguing this is impossibly incompatible with the laws of Physics and the accumulated corpus of experience since the dawn of humanity.) The whole strategy of Plantinga is actually to turn atheism into another kind of belief “that materialism and evolution are true” and then to rank it equal with the theisms. A very poor philosophical performance. As also (and better) pointed out in this other post. (And as my daughter remarked, fresh from writing a philosophy essay, Plantinga is missing the best argument of all, namely Pascal’s wager, an early instance of decision theory applied to religion.)

robust Bayesian FDR control with Bayes factors

Posted in Statistics, University life with tags , , , , on December 20, 2013 by xi'an

Here are a few comments on a recently arXived paper on FDRs by Xioaquan Wen (who asked for them!). Although there is less frenzy about false discovery rates in multiple testing now than in the 1990s, and I have not done anything on it since our 2004 JASA paper, this is still a topic of interest to me. Although maybe not in the formalised way the model is constructed here.

“Although the Bayesian FDR control is conceptually straightforward, its practical performance is susceptible to alternative model misspecifications. In comparison, the p-value based frequentist FDR control procedures demand only adequate behavior of p-values under the null models and generally ensure targeted FDR control levels, regardless of the distribution of p-values under the assumed alternatives.”

Now, I find the above quote of interest as it relates to Val Johnson’s argument for his uniformly most powerful “Bayesian” tests (now sufficiently discussed on the ‘Og!). This is a rather traditional criticism of using Bayes factors that they depend on the prior modelling, to the point it made it to the introduction of my tutorial yesterday. Actually, the paper has similar arguments to Johnson’s (who is quoted in the paper for earlier works) in that the criteria for validating a point estimator of the proportion of positives is highly frequentist. And does not care much about the alternative hypothesis. Besides, the modelling used therein is puzzling in that there seems to be a single parameter in the model, namely the true proportion of positives, which sounds to me as an hyper-stylised representation of real experiments. To the point of being useless… (Even if there are extra-parameters, they differ for each observation.) In addition, the argument leading to the proposed procedure is unclear: if the Bayes factors are to be consistent under the null and the proportion of positives needs an asymptotically guaranteed upper bound, the choice of a estimate equal to 1 does the job. (This is noticed on page 9.) So the presentation seems to miss a counter-factor to avoid this trivial solution.

“On the other hand, the Bayes factors from the true alternative models with reasonable powers should be, on average, greater than 1 (i.e., favoring the alternative over the null models). Therefore, the sample mean of the observed Bayes factors carries information regarding the mixture percentage.”

The estimator of this true proportion ends up being the proportion of Bayes factors less than 1, an anti-climactic proposal as it means accepting the null each time the Bayes factor is less than 1. (I did not check the proof that it overestimates the true proportion. ) Or the one of Storey (2003). However, the above quote shows it is validated only when the (true) alternative connects with the Bayes factor. So I do not see how this agrees with the robustness property of behaving well “under misspecifications of parametric alternative models”. Furthermore, in the specific framework adopted by the paper, the “misspecifications” are difficult to fathom, as they would mean that the parameter-free distributions of the observations under the alternatives are wrong and thus may render the Bayes factors to be arbitrary. Hence jeopardising the validity of the selection process. So there is something missing in the picture, I fear.

Thus, while the second half of the paper is dedicated to an extensive simulation study, what I found the most interesting direction in the paper is the question of the distribution of the Bayes factors (under the null or not), albeit not a Bayesian question, as it relates to the use and the calibration of ABC model choice (and the proposal by Fearnhead and Prangle of using the Bayes factor as the summary statistics). The fact that the (marginal) expectation of the Bayes factor under the null (marginal) is noteworthy but not as compelling as the author argues, because (a) it is only an expectation and (b) it tells nothing about the alternative. The distribution of the Bayes factor does depend upon the alternative through the Bayes factor, so mileage [of the quantile Bayes factor] may vary (as shown by the assumption “for Bayes factors with reasonable power”, p.14). Drawing Bayesian inference based on Bayes factors only is nonetheless an area worth investigating!

a general framework for updating belief functions [reply from the authors]

Posted in Statistics, University life with tags , , , , , , on July 16, 2013 by xi'an

Here is the reply by Chris and Steve about my comments from yesterday:

Thanks to Christian for the comments and feedback on our paper “A General Framework for Updating Belief Distributions“. We agree with Christian that starting with a summary statistic, or statistics, is an anchor for inference or learning, providing direction and guidance for models, avoiding the alternative vague notion of attempting to model a complete data set. The latter idea has dominated the Bayesian methodology for decades, but with the advent of large and complex data sets, this is becoming increasingly challenging, if not impossible.

However, in order to do work with statistics of interest, we need to find a framework in which this direct approach can be supported by a learning strategy when the formal use of Bayes theorem is not applicable. We achieve this in the paper for a general class of loss functions, which connect observations with a target of interest. A point raised by Christian is how arbitrary these loss functions are. We do not see this at all; for if a target has been properly identified then the most primitive construct between observations informing about a target and the target would come in the form of a loss function. One should always be able to assess the loss of ascertaining a value of \theta as an action and providing the loss in the presence of observation x. The question to be discussed is whether loss functions are objective, as in the case of the median loss,
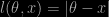
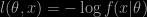
l(\theta,x)=|\theta-x|

or subjective, in the case of the choice between loss functions for estimating a location of a distribution; mean, median or mode? But our work is situated in the former position.

Previous work on loss functions, mostly in the classical literature, has spent a lot of space working out what are optimal loss functions for targets of interest. We are not really dealing with novel targets and so we can draw on the classic literature here. The work can be thought of as the Bayesian version of the M-estimator and associated ideas. In this respect we are dealing with two loss functions for updating belief distributions, one for the data, which we have just discussed, and one for the prior information, which, due to coherence principles, must be the Kullback-Leibler divergence. This raises the thorny issue of how to calibrate the two loss functions. We discuss this in the paper.

To then deal with the statistic problem, mentioned at the start of this discussion, we have found a nice way to proceed by using the loss function l(\theta,x)=-\log f(x|\theta). How this loss function, combined with the use of the exponential family, can be used to estimate functionals of the type

I=\int g(x)\,f_0(x)\, dx

is provided in the Walker talk at Bayes 250 in London, titled “The Misspecified Bayesian”, since the “model” f(x|\theta) is designed to be misspecified, a tool to estimate and learn about I only. The basic idea is to evaluate I by ensuring that we learn about the \theta_0 for which

I=\int g(x)\,f(x|\theta_0)\, dx.

This is the story of the background, we would now like to pick up in more detail on three important points that you raise in your post:

  1. The arbitrariness in selecting the loss function.
  2. The relative weighting of loss-to-data vs. loss-to-prior.
  3. The selection of the loss in the M-free case.

In the absence of complete knowledge of the data generating mechanism, i.e. outside of M-closed,

  1. We believe the statistician should weigh up the relative arbitrariness in selecting a loss function targeting the statistic of interest versus the arbitrariness of selecting a misspecified model, known not to be true, for the complete data generating mechanism. There is a wealth of literature on how to select optimal loss functions that target specific statistics, e.g. Hüber (2009) provides a comprehensive overview of how this should be done. As far as we are aware, we know of no formal procedures (that do not rely on loss functions) to select a false sampling distribution f(x|\theta) for the whole of x; see Key, Pericchi and Smith (1999).
  2. The relative weighting of loss-to-data vs. loss-to-prior. This is an interesting open problem. Our framework shows in the absence of M-closed or the use of self-information loss that the analyst must select this weighting. In our paper we suggest some default procedures. We have nowhere claimed these were “correct”. You raise concerns regards parameterisation and we agree with you that care is needed, but many of these issues equally hold for existing “Objective” or “Default” Bayes procedures, such as unit-information priors.
  3. The selection of the loss in M-free. You say “….there is no optimal choice for the substitute to the loss function…”. We disagree. Our approach is to select an established loss function that directly targets the statistic of interest, and elicit prior beliefs directly on the unknown value of this statistic. There is no notion here of a a pseudo-likelihood or where this converges to.

Thank you again to Christian for his critical observations!

mathematical statistics books with Bayesian chapters [incomplete book reviews]

Posted in Books, Statistics, University life with tags , , , , , , , , on July 9, 2013 by xi'an

I received (in the same box) two mathematical statistics books from CRC Press, Understanding Advanced Statistical Methods by Westfall and Henning, and Statistical Theory A Concise Introduction by Abramovich and Ritov. For review in CHANCE. While they are both decent books for teaching mathematical statistics at undergraduate borderline graduate level, I do not find enough of a novelty in them to proceed to a full review. (Given more time, I could have changed my mind about the first one.) Instead, I concentrate here on their processing of the Bayesian paradigm, which takes a wee bit more than a chapter in either of them. (And this can be done over a single métro trip!) The important following disclaimer applies: comparing both books is highly unfair in that it is only because I received them together. They do not necessarily aim at the same audience. And I did not read the whole of either of them.

First, the concise Statistical Theory  covers the topic in a fairly traditional way. It starts with a warning about the philosophical nature of priors and posteriors, which reflect beliefs rather than frequency limits (just like likelihoods, no?!). It then introduces priors with the criticism that priors are difficult to build and assess. The two classes of priors analysed in this chapter are unsurprisingly conjugate priors (which hyperparameters have to be determined or chosen or estimated in the empirical Bayes heresy [my words!, not the authors’]) and “noninformative (objective) priors”.  The criticism of the flat priors is also traditional and leads to the  group invariant (Haar) measures, then to Jeffreys non-informative priors (with the apparent belief that Jeffreys only handled the univariate case). Point estimation is reduced to posterior expectations, confidence intervals to HPD regions, and testing to posterior probability ratios (with a warning about improper priors). Bayes rules make a reappearance in the following decision-theory chapter, as providers of both admissible and minimax estimators. This is it, as Bayesian techniques are not mentioned in the final “Linear Models” chapter. As a newcomer to statistics, I think I would be as bemused about Bayesian statistics as when I got my 15mn entry as a student, because here was a method that seemed to have a load of history, an inner coherence, and it was mentioned as an oddity in an otherwise purely non-Bayesian course. What good could this do to the understanding of the students?! So I would advise against getting this “token Bayesian” chapter in the book…

“You are not ignorant! Prior information is what you know prior to collecting the data.” Understanding Advanced Statistical Methods (p.345)

Second, Understanding Advanced Statistical Methods offers a more intuitive entry, by justifying prior distributions as summaries of prior information. And observations as a mean to increase your knowledge about the parameter. The Bayesian chapter uses a toy but very clear survey examplew to illustrate the passage from prior to posterior distributions. And to discuss the distinction between informative and noninformative priors. (I like the “Ugly Rule of Thumb” insert, as it gives a guideline without getting too comfy about it… E.g., using a 90% credible interval is good enough on p.354.) Conjugate priors are mentioned as a result of past computational limitations and simulation is hailed as a highly natural tool for analysing posterior distributions. Yay! A small section discusses the purpose of vague priors without getting much into details and suggests to avoid improper priors by using “distributions with extremely large variance”, a concept we dismissed in Bayesian Core! For how large is “extremely large”?!

“You may end up being surprised to learn in later chapters (..) that, with classical methods, you simply cannot perform the types of analyses shown in this section (…) And that’s the answer to the question, “What good is Bayes?””Understanding Advanced Statistical Methods (p.345)

Then comes the really appreciable part, a section entitled “What good is Bayes?”—it actually reads “What Good is Bayes?” (p.359), leading to a private if grammatically poor joke since I.J. Good was one of the first modern Bayesians, working with Turing at Bletchley Park…—  The authors simply skip the philosophical arguments to give the reader a showcase of examples where the wealth of the Bayesian toolbox: logistic regression, VaR (Value at Risk), stock prices, drug profit prediction. Concluding with arguments in favour of the frequentist methods: (a) not requiring priors, (b) easier with generic distributifrequentistons, (c) easier to understand with simulation, and (d) easier to validate with validation. I do not mean to get into a debate about those points as my own point is that the authors are taking a certain stand about the pros and cons of the frequentist/Bayesian approaches and that they are making their readers aware of it. (Note that the Bayesian chapter comes before the frequentist chapter!) A further section is “Comparing the Bayesian and frequentist paradigms?” (p.384), again with a certain frequentist slant, but again making the distinctions and similarities quite clear to the reader. Of course, there is very little (if any) about Bayesian approaches in the next chapters but this is somehow coherent with the authors’ perspective. Once more, a perspective that is well-spelled and comprehensible for the reader. Even the novice statistician. In that sense, having a Bayesian chapter inside a general theory book makes sense.  (The second book has a rather detailed website, by the way! Even though handling simulations in Excel and drawing graphs in SAS could be dangerous to your health…)

beware, nefarious Bayesians threaten to take over frequentism using loss functions as Trojan horses!

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on November 12, 2012 by xi'an

“It is not a coincidence that textbooks written by Bayesian statisticians extol the virtue of the decision-theoretic perspective and then proceed to present the Bayesian approach as its natural extension.” (p.19)

“According to some Bayesians (see Robert, 2007), the risk function does represent a legitimate frequentist error because it is derived by taking expectations with respect to [the sampling density]. This argument is misleading for several reasons.” (p.18)

During my R exam, I read the recent arXiv posting by Aris Spanos on why “the decision theoretic perspective misrepresents the frequentist viewpoint”. The paper is entitled “Why the Decision Theoretic Perspective Misrepresents Frequentist Inference: ‘Nuts and Bolts’ vs. Learning from Data” and I found it at the very least puzzling…. The main theme is the one caricatured in the title of this post, namely that the decision-theoretic analysis of frequentist procedures is a trick brought by Bayesians to justify their own procedures. The fundamental argument behind this perspective is that decision theory operates in a “for all θ” referential while frequentist inference (in Spanos’ universe) is only concerned by one θ, the true value of the parameter. (Incidentally, the “nuts and bolt” refers to the only case when a decision-theoretic approach is relevant from a frequentist viewpoint, namely in factory quality control sampling.)

“The notions of a risk function and admissibility are inappropriate for frequentist inference because they do not represent legitimate error probabilities.” (p.3)

“An important dimension of frequentist inference that has not been adequately appreciated in the statistics literature concerns its objectives and underlying reasoning.” (p.10)

“The factual nature of frequentist reasoning in estimation also brings out the impertinence of the notion of admissibility stemming from its reliance on the quantifier ‘for all’.” (p.13)

One strange feature of the paper is that Aris Spanos seems to appropriate for himself the notion of frequentism, rejecting the choices made by (what I would call frequentist) pioneers like Wald, Neyman, “Lehmann and LeCam [sic]”, Stein. Apart from Fisher—and the paper is strongly grounded in neo-Fisherian revivalism—, the only frequentists seemingly finding grace in the eyes of the author are George Box, David Cox, and George Tiao. (The references are mostly to textbooks, incidentally.) Modern authors that clearly qualify as frequentists like Bickel, Donoho, Johnstone, or, to mention the French school, e.g., Birgé, Massart, Picard, Tsybakov, none of whom can be suspected of Bayesian inclinations!, do not appear either as satisfying those narrow tenets of frequentism. Furthermore, the concept of frequentist inference is never clearly defined within the paper. As in the above quote, the notion of “legitimate error probabilities” pops up repeatedly (15 times) within the whole manifesto without being explicitely defined. (The closest to a definition is found on page 17, where the significance level and the p-value are found to be legitimate.) Aris Spanos even rejects what I would call the von Mises basis of frequentism: “contrary to Bayesian claims, those error probabilities have nothing to to do with the temporal or the physical dimension of the long-run metaphor associated with repeated samples” (p.17), namely that a statistical  procedure cannot be evaluated on its long term performance… Continue reading →