
“The expected value is hardly ever expected.” The Search for Certainty, page 207.
Following the advice of an Og’s reader, Erkan, I read Krzysztof Burdzy’s The Search for Certainty over the past weeks (and mostly in the métro). The author is primarily a probabilist, but he has set upon launching a radical criticism of the philosophical foundations of Statistics, the book subtitle being (somehow misleadingly) put as On the Clash of Science and Philosophy of Probability. Or so he thinks. (The introduction to the book is available on the author’s webpage and he has also started a blog related with the book. The cover is made of seven dices all showing sixes, with on top the probability p=0.0000036… of such an event, provided the dice is fair. And provided one does not take into account the suspicious fives all facing the reader!)
“Of the four well crystallized philosophies of probability, two chose the certainty as their intellectual holy grail. Those are the failed theories of von Mises and de Finetti.” The Search for Certainty, page 30.
Although I have read the book with a pen, I will not go at this stage into a detailed analysis of The Search for Certainty. Indeed, I found the book both annoying and unconvincing, for reasons not very different from the criticisms addressed at Taleb’s The Black Swan. The book aims at demonstrating that the philosophical arguments underlying both frequentist and Bayesian Statistics are wrong. Unsurprisingly (!), I find the book lacking in this demonstration and overall poor from a scholarly perspective. It compares with Taleb’s The Black Swan in that the attempts at philosophy are more related to everyday “common sense” than to deep (and scholarly) philosophy (and they also involve the apparently inevitable Karl Popper, “the champion of the propensity theory of probability”, p.43!). The main point made in The Search for Certainty is very narrow in that Burdzy concentrates on two very specific entries to frequentism and subjectivism, namely von Mises’ and de Finetti’s, respectively, while those are not your average statistician’s references. For instance, von Mises bases his definition of frequency properties on the notion of collectives, a notion I had not previously encountered. Similarly, de Finetti’s statement “Probability does not exist” cannot be seen as the core principle of many Bayesian statisticians and I certainly do not relate to his all-subjective perspective for conducting Bayesian inference.
“Mr. Winston is unique because we know something about him that we do not know about any other individual in the population.” The Search for Certainty, page 66.
The style of The Search for Certainty is fairly annoying, if of a different sort than Taleb‘s. It is predominantly non-technical, the worked-out examples being always of the coin and balls-in-an-urn type. Arguments are never more than one paragraph long and metaphors and weak analogies are more confusing than helpful. The book criticises a lot decision-theory and the related coherence of Bayesian procedures, ie against the Dutch Book argument, but it misses the connections between frequentist optimality(ies) and Bayesian procedures, like Wald’s complete class theorem, Welch and Peers (1964) matching priors, or the more recent Berger’s frequentist-Bayesian perspective. There are also (in my opinion) confusions, as when the basis for the frequency approach to probability is criticised for being connected with an unrealistic infinity of events, thus confusing concepts with experiments (indeed, the Large Law of Large Numbers cannot be proved by an experiment), the existence of a model versus its assessment (“Kolmogorov’s axioms say nothing on how to match the mathematical results with reality”, p.31), the use of a probability against its “truth”, the inclusion of time (and thus model shifts) into mathematical axioms, the assimilation of frequentist statistics to unbiased estimators, a somehow diffuse belief that some priors can be proven to be better than others, an argument that they can be evaluated by their predictive performances… The insistence in adding new axioms to Kolmogorov’s is furthermore puzzling:
(L4) If there exists a symmetry on the space of possible outcomes which maps an event A onto an event B then the two events have equal probabilities, that is, P(A) = P(B).
(L5) An event has probability 0 if and only if it cannot occur. An event has probability 1 if and only if it must occur.
The axiom (L4) relates to both the Principle of Insufficient Reasons, whose limitations are the cause for much debate in the selection of prior distributions, and to invariance principles that lead to Haar measures as default noninformative priors. But I do not see the point in adding such an axiom into the tenets of probability. (And (L5) is more psychological than mathematical…)
“There is no justification for the use of the Bayes theorem in the subjective theory.” The Search for Certainty, page 144.
In conclusion, it is hopefully obvious that I did not overly enjoy this The Search for Certainty and that I do not consider it makes a significant contribution to the foundations of statistical inference and in particular to Bayesian analysis. Being examined by an outsider to our discipline certainly has a strong appeal, but only if done at a deep enough level.
Ps-Be warned that there is a homonymous book with full titlde The Search for Certainty: A Philosophical Account of Foundations of Mathematics on issues related with Gödel’s incompleteness theorem, by Marcus Gianquinto, book that I mistakenly bought for The Search for Certainty discussed here. Professor Gianquinto is actually a professor of philosophy at UCL, who specialises in epistemology so he could also comment on this book.
 For the final day of the meeting, after a good one hour run to the end of the Benidorm bay (for me at least!), we got treated to great talks, culminating with the fitting conclusion given by the conference originator, José Bernardo. The first talk of the day was Guido Consonni’s, who introduced a new class of non-local priors to deal with variable selection. From my understanding, those priors avoid a neighbourhood of zero by placing a polynomial prior on the regression coefficients in order to discriminate better between the null and the alternative,


 under a flat prior is
 , for instance
 , but if one use a logit parameterisation instead
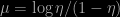
 can be quite distinct from
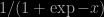 , for instance leading to
 when


