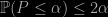Archive for DIC

model selection and multiple testing

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , on October 23, 2015 by xi'an


Ritabrata Dutta, Malgorzata Bogdan and Jayanta Ghosh recently arXived a survey paper on model selection and multiple testing. Which provides a good opportunity to reflect upon traditional Bayesian approaches to model choice. And potential alternatives. On my way back from Madrid, where I got a bit distracted when flying over the South-West French coast, from Biarritz to Bordeaux. Spotting the lake of Hourtain, where I spent my military training month, 29 years ago!

“On the basis of comparison of AIC and BIC, we suggest tentatively that model selection rules should be used for the purpose for which they were introduced. If they are used for other problems, a fresh justification is desirable. In one case, justification may take the form of a consistency theorem, in the other some sort of oracle inequality. Both may be hard to prove. Then one should have substantial numerical assessment over many different examples.”

The authors quickly replace the Bayes factor with BIC, because it is typically consistent. In the comparison between AIC and BIC they mention the connundrum of defining a prior on a nested model from the prior on the nesting model, a problem that has not been properly solved in my opinion. The above quote with its call to a large simulation study reminded me of the paper by Arnold & Loeppky about running such studies through ecdfs. That I did not see as solving the issue. The authors also discuss DIC and Lasso, without making much of a connection between those, or with the above. And then reach the parametric empirical Bayes approach to model selection exemplified by Ed George’s and Don Foster’s 2000 paper. Which achieves asymptotic optimality for posterior prediction loss (p.9). And which unifies a wide range of model selection approaches.

A second part of the survey considers the large p setting, where BIC is not a good approximation to the Bayes factor (when testing whether or not all mean entries are zero). And recalls that there are priors ensuring consistency for the Bayes factor in this very [restrictive] case. Then, in Section 4, the authors move to what they call “cross-validatory Bayes factors”, also known as partial Bayes factors and pseudo-Bayes factors, where the data is split to (a) make the improper prior proper and (b) run the comparison or test on the remaining data. They also show the surprising result that, provided the fraction of the data used to proper-ise the prior does not converge to one, the X validated Bayes factor remains consistent [for the special case above]. The last part of the paper concentrates on multiple testing but is more tentative and conjecturing about convergence results, centring on the differences between full Bayes and empirical Bayes. Then the plane landed in Paris and I stopped my reading, not feeling differently about the topic than when the plane started from Madrid.

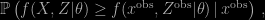
a unified treatment of predictive model comparison

Posted in Books, Statistics, University life with tags , , , , , , , , , on June 16, 2015 by xi'an

“Applying various approximation strategies to the relative predictive performance derived from predictive distributions in frequentist and Bayesian inference yields many of the model comparison techniques ubiquitous in practice, from predictive log loss cross validation to the Bayesian evidence and Bayesian information criteria.”

Michael Betancourt (Warwick) just arXived a paper formalising predictive model comparison in an almost Bourbakian sense! Meaning that he adopts therein a very general representation of the issue, with minimal assumptions on the data generating process (excluding a specific metric and obviously the choice of a testing statistic). He opts for an M-open perspective, meaning that this generating process stands outside the hypothetical statistical model or, in Lindley’s terms, a small world. Within this paradigm, the only way to assess the fit of a model seems to be through the predictive performances of that model. Using for instance an f-divergence like the Kullback-Leibler divergence, based on the true generated process as the reference. I think this however puts a restriction on the choice of small worlds as the probability measure on that small world has to be absolutely continuous wrt the true data generating process for the distance to be finite. While there are arguments in favour of absolutely continuous small worlds, this assumes a knowledge about the true process that we simply cannot gather. Ignoring this difficulty, a relative Kullback-Leibler divergence can be defined in terms of an almost arbitrary reference measure. But as it still relies on the true measure, its evaluation proceeds via cross-validation “tricks” like jackknife and bootstrap. However, on the Bayesian side, using the prior predictive links the Kullback-Leibler divergence with the marginal likelihood. And Michael argues further that the posterior predictive can be seen as the unifying tool behind information criteria like DIC and WAIC (widely applicable information criterion). Which does not convince me towards the utility of those criteria as model selection tools, as there is too much freedom in the way approximations are used and a potential for using the data several times.

Posterior predictive p-values and the convex order

Posted in Books, Statistics, University life with tags , , , , , , , , , on December 22, 2014 by xi'an

Patrick Rubin-Delanchy and Daniel Lawson [of Warhammer fame!] recently arXived a paper we had discussed with Patrick when he visited Andrew and I last summer in Paris. The topic is the evaluation of the posterior predictive probability of a larger discrepancy between data and model

\mathbb{P}\left( f(X|\theta)\ge f(x^\text{obs}|\theta) \,|\,x^\text{obs} \right)

which acts like a Bayesian p-value of sorts. I discussed several times the reservations I have about this notion on this blog… Including running one experiment on the uniformity of the ppp while in Duke last year. One item of those reservations being that it evaluates the posterior probability of an event that does not exist a priori. Which is somewhat connected to the issue of using the data “twice”.

“A posterior predictive p-value has a transparent Bayesian interpretation.”

Another item that was suggested [to me] in the current paper is the difficulty in defining the posterior predictive (pp), for instance by including latent variables

\mathbb{P}\left( f(X,Z|\theta)\ge f(x^\text{obs},Z^\text{obs}|\theta) \,|\,x^\text{obs} \right)\,,

which reminds me of the multiple possible avatars of the BIC criterion. The question addressed by Rubin-Delanchy and Lawson is how far from the uniform distribution stands this pp when the model is correct. The main result of their paper is that any sub-uniform distribution can be expressed as a particular posterior predictive. The authors also exhibit the distribution that achieves the bound produced by Xiao-Li Meng, Namely that

\mathbb{P}(P\le \alpha) \le 2\alpha

where P is the above (top) probability. (Hence it is uniform up to a factor 2!) Obviously, the proximity with the upper bound only occurs in a limited number of cases that do not validate the overall use of the ppp. But this is certainly a nice piece of theoretical work.

reading classics (#1)

Posted in Books, Statistics, University life with tags , , , , , , , , , on October 31, 2013 by xi'an

Here we are, back in a new school year and with new students reading the classics. Today, Ilaria Masiani started the seminar with a presentation of Spiegelhalter et al. 2002 DIC paper, already heavily mentioned on this blog. Here are the slides, posted on slideshare (if you know of another website housing and displaying slides, let me know: the incompatibility between Firefox and slideshare drives me crazy!, well, almost…)

I have already said a lot about DIC on this blog so will not add a repetition of my reservations. I enjoyed the link with the log scores and the Kullback-Leibler divergence, but failed to see a proper intuition for defining the effective number of parameters the way it is defined in the paper… The presentation was quite faithful to the original and, as is usual in the reading seminars (esp. the first one of the year), did not go far enough (for my taste) in the critical evaluation of the themes therein. Maybe an idea for next year would be to ask one of my PhD students to give the zeroth seminar…

can you help?

Posted in Statistics, University life with tags , , , , , , , on October 12, 2013 by xi'an

An email received a few days ago:

Can you help me answering my query about AIC and DIC?

I want to compare the predictive power of a non Bayesian model (GWR, Geographically weighted regression) and a Bayesian hierarchical model (spLM).
For GWR, DIC is not defined, but AIC is.
For  spLM, AIC is not defined, but DIC is.

How can I compare the predictive ability of these two models? Does it make sense to compare AIC of one with DIC of the other?

I did not reply as the answer is in the question: the numerical values of AIC and DIC do not compare. And since one estimation is Bayesian while the other is not, I do not think the predictive abilities can be compared. This is not even mentioning my reluctance to use DIC…as renewed in yesterday’s post.