Archive for Error and Inference

E&I review in Theory and Decision

Posted in Statistics, University life with tags , , , , , on March 16, 2012 by xi'an

A few days ago, while in Roma, I got the good news that my review of Error and Inference had been accepted by Theory and Decision. Great! Then today I got a second email asking me to connect to a Springer site entitled “Services for Authors” with the following message:

Dear Christian Robert!
Thank you for publishing your paper in one of Springer’s journals.

Article Title: Error and Inference: an outsider stand on a frequentist philosophy
Journal: Theory and Decision
DOI: 10.1007/s11238-012-9298-3

Make your Choice

In order to facilitate the production and publication of your article we need further information from you relating to:

  • Please indicate if you would like to publish your article as open access with Springer’s Open Choice option (by paying a publication fee or as a result of an agreement between your funder/institution and Springer). I acknowledge that publishing my article with open access costs € 2000 / US $3000 and that this choice is final and cannot be cancelled later.
  • Please transfer the copyright, if you do not publish your articles as open access.
  • Please indicate if you would like to have your figures printed in color.
  • Please indicate if you would like to order offprints. You have the opportunity to order a poster of your article against a fee of €50 per poster. The poster features the cover page of the issue your article is published in together with the article title and the names of all contributing authors.

Now I feel rather uncomfortable with the above options since I do not see why I should pay a huge amount € 2000 € for having my work/review made again available. Since it is already freely accessible on arXiv. And it is only a book-review, for Gutenberg’s sake! Last year, we made our PNAS paper available as Open Access, but this was (a) cheaper and (b) an important result, or so we thought! The nice part of the message was that for once I did not have to sign and send back a paper copy of the copyright agreement as with so many journals and as if we still were in the 19th Century… (I do not see the point in the poster, though!)

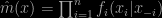
on using the data twice…

Posted in Books, Statistics, University life with tags , , , , , , , , on January 13, 2012 by xi'an

As I was writing my next column for CHANCE, I decided I will include a methodology box about “using the data twice”. Here is the draft. (The second part is reproduced verbatim from an earlier post on Error and Inference.)

Several aspects of the books covered in this CHANCE review [i.e., Bayesian ideas and data analysis, and Bayesian modeling using WinBUGS] face the problem of “using the data twice”. What does that mean? Nothing really precise, actually. The accusation of “using the data twice” found in the Bayesian literature can be thrown at most procedures exploiting the Bayesian machinery without actually being Bayesian, i.e.~which cannot be derived from the posterior distribution. For instance, the integrated likelihood approach in Murray Aitkin’s Statistical Inference avoids the difficulties related with improper priors πi by first using the data x to construct (proper) posteriors πi(θi|x) and then secondly using the data in a Bayes factor

\int_{\Theta_1}f_1(x|\theta_1) \pi_1(\theta_1|x)\,\text{d}\theta_1\bigg/ \int_{\Theta_2}f_2(x|\theta_2)\pi_2(\theta_2|x)\,\text{d}\theta_2

as if the posteriors were priors. This obviously solves the improperty difficulty (see. e.g., The Bayesian Choice), but it creates a statistical procedure outside the Bayesian domain, hence requiring a separate validation since the usual properties of Bayesian procedures do not apply. Similarly, the whole empirical Bayes approach falls under this category, even though some empirical Bayes procedures are asymptotically convergent. The pseudo-marginal likelihood of Geisser and Eddy (1979), used in  Bayesian ideas and data analysis, is defined by

\hat m(x) = \prod_{i=1}^n f_i(x_i|x_{-i})

through the marginal posterior likelihoods. While it also allows for improper priors, it does use the same data in each term of the product and, again, it is not a Bayesian procedure.

Once again, from first principles, a Bayesian approach should use the data only once, namely when constructing the posterior distribution on every unknown component of the model(s).  Based on this all-encompassing posterior, all inferential aspects should be the consequences of a sequence of decision-theoretic steps in order to select optimal procedures. This is the ideal setting while, in practice,  relying on a sequence of posterior distributions is often necessary, each posterior being a consequence of earlier decisions, which makes it the result of a multiple (improper) use of the data… For instance, the process of Bayesian variable selection is on principle clean from the sin of “using the data twice”: one simply computes the posterior probability of each of the variable subsets and this is over. However, in a case involving many (many) variables, there are two difficulties: one is about building the prior distributions for all possible models, a task that needs to be automatised to some extent; another is about exploring the set of potential models. First, ressorting to projection priors as in the intrinsic solution of Pèrez and Berger (2002, Biometrika, a much valuable article!), while unavoidable and a “least worst” solution, means switching priors/posteriors based on earlier acceptances/rejections, i.e. on the data. Second, the path of models truly explored by a computational algorithm [which will be a minuscule subset of the set of all models] will depend on the models rejected so far, either when relying on a stepwise exploration or when using a random walk MCMC algorithm. Although this is not crystal clear (there is actually plenty of room for supporting the opposite view!), it could be argued that the data is thus used several times in this process…

Error and Inference [on wrong models]

Posted in Books, Statistics, University life with tags , , , , , , on December 6, 2011 by xi'an

In connection with my series of posts on the book Error and Inference, and my recent collation of those into an arXiv document, Deborah Mayo has started a series of informal seminars at the LSE on the philosophy of errors in statistics and the likelihood principle. and has also posted a long comment on my argument about only using wrong models. (The title is inspired from the Rolling Stones’ “You can’t always get what you want“, very cool!) The discussion about the need or not to take into account all possible models (which is the meaning of the “catchall hypothesis” I had missed while reading the book) shows my point was not clear. I obviously do not claim in the review that all possible models should be accounted for at once, this was on the opposite my understanding of Mayo’s criticism of the Bayesian approach (I thought the following sentence was clear enough: “According to Mayo, this alternative hypothesis should “include all possible rivals, including those not even though of” (p.37)”)! So I see the Bayesian approach as a way to put on the table a collection of reasonable (if all wrong) models and give to those models a posterior probability, with the purpose that improbable ones are eliminated. Therefore, I am in agreement with most of the comments in the post, esp. because this has little to do with Bayesian versus frequentist testing! Even rejecting the less likely models from a collection seems compatible with a Bayesian approach, model averaging is not always an appropriate solution, depending on the loss function!

Error and Inference [arXived]

Posted in Books, Statistics, University life with tags , , , , , , , on November 29, 2011 by xi'an

Following my never-ending series of posts on the book Error and Inference, (edited) by Deborah Mayo and Ari Spanos (and kindly sent to me by Deborah), I decided to edit those posts into a (slightly) more coherent document, now posted on arXiv. And to submit it as a book review to Siam Review, even though I had not high expectations it fits the purpose of the journal: the review was rejected between the submission to arXiv and the publication of this post!

the cult of significance

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on October 18, 2011 by xi'an

“Statistical significance is not a scientific test. It is a philosophical, qualitative test. It asks “whether”. Existence, the question of whether, is interesting. But it is not scientific.” S. Ziliak and D. McCloskey, p.5

The book, written by economists Stephen Ziliak and Deirdre McCloskey, has a theme bound to attract Bayesians and all those puzzled by the absolute and automatised faith in significance tests. The main argument of the authors is indeed that an overwhelming majority of papers stop at rejecting variables (“coefficients”) on the sole and unsupported basis of non-significance at the 5% level. Hence the subtitle “How the standard error costs us jobs, justice, and lives“… This is an argument I completely agree with, however, the aggressive style of the book truly put me off! As with Error and Inference, which also addresses a non-Bayesian issue, I could have let the matter go, however I feel the book may in the end be counter-productive and thus endeavour to explain why through this review.  (I wrote the following review in batches, before and during my trip to Dublin, so the going is rather broken, I am afraid…) Continue reading →