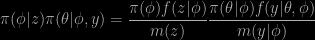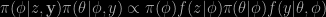Archive for JAGS

bridgesampling [R package]

Posted in pictures, R, Statistics, University life with tags , , , , , , , , , on November 9, 2017 by xi'an

Quentin F. Gronau, Henrik Singmann and Eric-Jan Wagenmakers have arXived a detailed documentation about their bridgesampling R package. (No wonder that researchers from Amsterdam favour bridge sampling!) [The package relates to a [52 pages] tutorial on bridge sampling by Gronau et al. that I will hopefully comment soon.] The bridge sampling methodology for marginal likelihood approximation requires two Monte Carlo samples for a ratio of two integrals. A nice twist in this approach is to use a dummy integral that is already available, with respect to a probability density that is an approximation to the exact posterior. This means avoiding the difficulties with bridge sampling of bridging two different parameter spaces, in possibly different dimensions, with potentially very little overlap between the posterior distributions. The substitute probability density is chosen as Normal or warped Normal, rather than a t which would provide more stability in my opinion. The bridgesampling package also provides an error evaluation for the approximation, although based on spectral estimates derived from the coda package. The remainder of the document exhibits how the package can be used in conjunction with either JAGS or Stan. And concludes with the following words of caution:

“It should also be kept in mind that there may be cases in which the bridge sampling procedure may not be the ideal choice for conducting Bayesian model comparisons. For instance, when the models are nested it might be faster and easier to use the Savage-Dickey density ratio (Dickey and Lientz 1970; Wagenmakers et al. 2010). Another example is when the comparison of interest concerns a very large model space, and a separate bridge sampling based computation of marginal likelihoods may take too much time. In this scenario, Reversible Jump MCMC (Green 1995) may be more appropriate.”

more of the same!

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , on December 10, 2015 by xi'an

aboriginal artist, NGV, Melbourne, July 30, 2012Daniel Seita, Haoyu Chen, and John Canny arXived last week a paper entitled “Fast parallel SAME Gibbs sampling on general discrete Bayesian networks“.  The distributions of the observables are defined by full conditional probability tables on the nodes of a graphical model. The distributions on the latent or missing nodes of the network are multinomial, with Dirichlet priors. To derive the MAP in such models, although this goal is not explicitly stated in the paper till the second page, the authors refer to the recent paper by Zhao et al. (2015), discussed on the ‘Og just as recently, which applies our SAME methodology. Since the paper is mostly computational (and submitted to ICLR 2016, which takes place juuust before AISTATS 2016), I do not have much to comment about it. Except to notice that the authors mention our paper as “Technical report, Statistics and Computing, 2002”. I am not sure the editor of Statistics and Computing will appreciate! The proper reference is in Statistics and Computing, 12:77-84, 2002.

“We argue that SAME is beneficial for Gibbs sampling because it helps to reduce excess variance.”

Still, I am a wee bit surprised at both the above statement and at the comparison with a JAGS implementation. Because SAME augments the number of latent vectors as the number of iterations increases, so should be slower by a mere curse of dimension,, slower than a regular Gibbs with a single latent vector. And because I do not get either the connection with JAGS: SAME could be programmed in JAGS, couldn’t it? If the authors means a regular Gibbs sampler with no latent vector augmentation, the comparison makes little sense as one algorithm aims at the MAP (with a modest five replicas), while the other encompasses the complete posterior distribution. But this sounds unlikely when considering that the larger the number m of replicas the better their alternative to JAGS. It would thus be interesting to understand what the authors mean by JAGS in this setup!

Shravan Vasishth at Bayes in Paris this week

Posted in Books, Statistics, University life with tags , , , , , , , , on October 20, 2014 by xi'an

Taking advantage of his visit to Paris this month, Shravan Vasishth, from University of Postdam, Germany, will give a talk at 10.30am, next Friday, October 24, at ENSAE on:

Using Bayesian Linear Mixed Models in Psycholinguistics: Some open issues

With the arrival of the probabilistic programming language Stan (and JAGS), it has become relatively easy to fit fairly complex Bayesian linear mixed models. Until now, the main tool that was available in R was lme4. I will talk about how we have fit these models in recently published work (Husain et al 2014, Hofmeister and Vasishth 2014). We are trying to develop a standard approach for fitting these models so that graduate students with minimal training in statistics can fit such models using Stan.

I will discuss some open issues that arose in the course of fitting linear mixed models. In particular, one issue is: should one assume a full variance-covariance matrix for random effects even when there is not enough data to estimate all parameters? In lme4, one often gets convergence failure or degenerate variance-covariance matrices in such cases and so one has to back off to a simpler model. But in Stan it is possible to assume vague priors on each parameter, and fit a full variance-covariance matrix for random effects. The advantage of doing this is that we faithfully express in the model how the data were generated—if there is not enough data to estimate the parameters, the posterior distribution will be dominated by the prior, and if there is enough data, we should get reasonable estimates for each parameter. Currently we fit full variance-covariance matrices, but we have been criticized for doing this. The criticism is that one should not try to fit such models when there is not enough data to estimate parameters. This position is very reasonable when using lme4; but in the Bayesian setting it does not seem to matter.

future of computational statistics

Posted in Books, pictures, R, Statistics, University life with tags , , , , , , , , , , , , , , on September 29, 2014 by xi'an

I am currently preparing a survey paper on the present state of computational statistics, reflecting on the massive evolution of the field since my early Monte Carlo simulations on an Apple //e, which would take a few days to return a curve of approximate expected squared error losses… It seems to me that MCMC is attracting more attention nowadays than in the past decade, both because of methodological advances linked with better theoretical tools, as for instance in the handling of stochastic processes, and because of new forays in accelerated computing via parallel and cloud computing, The breadth and quality of talks at MCMski IV is testimony to this. A second trend that is not unrelated to the first one is the development of new and the rehabilitation of older techniques to handle complex models by approximations, witness ABC, Expectation-Propagation, variational Bayes, &tc. With a corollary being an healthy questioning of the models themselves. As illustrated for instance in Chris Holmes’ talk last week. While those simplifications are inevitable when faced with hardly imaginable levels of complexity, I still remain confident about the “inevitability” of turning statistics into an “optimize+penalize” tunnel vision…  A third characteristic is the emergence of new languages and meta-languages intended to handle complexity both of problems and of solutions towards a wider audience of users. STAN obviously comes to mind. And JAGS. But it may be that another scale of language is now required…

If you have any suggestion of novel directions in computational statistics or instead of dead ends, I would be most interested in hearing them! So please do comment or send emails to my gmail address bayesianstatistics…

cut, baby, cut!

Posted in Books, Kids, Mountains, R, Statistics, University life with tags , , , , , , , , , , , , , on January 29, 2014 by xi'an

cutcutAt MCMSki IV, I attended (and chaired) a session where Martyn Plummer presented some developments on cut models. As I was not sure I had gotten the idea [although this happened to be one of those few sessions where the flu had not yet completely taken over!] and as I wanted to check about a potential explanation for the lack of convergence discussed by Martyn during his talk, I decided to (re)present the talk at our “MCMSki decompression” seminar at CREST. Martyn sent me his slides and also kindly pointed out to the relevant section of the BUGS book, reproduced above. (Disclaimer: do not get me wrong here, the title is a pun on the infamous “drill, baby, drill!” and not connected in any way to Martyn’s talk or work!)

I cannot say I get the idea any clearer from this short explanation in the BUGS book, although it gives a literal meaning to the word “cut”. From this description I only understand that a cut is the removal of an edge in a probabilistic graph, however there must/may be some arbitrariness in building the wrong conditional distribution. In the Poisson-binomial case treated in Martyn’s case, I interpret the cut as simulating from

\pi(\phi|z)\pi(\theta|\phi,y)=\dfrac{\pi(\phi)f(z|\phi)}{m(z)}\dfrac{\pi(\theta|\phi)f(y|\theta,\phi)}{m(y|\phi)}

instead of

\pi(\phi|z,\mathbf{y})\pi(\theta|\phi,y)\propto\pi(\phi)f(z|\phi)\pi(\theta|\phi)f(y|\theta,\phi)

hence loosing some of the information about φ… Now, this cut version is a function of φ and θ that can be fed to a Metropolis-Hastings algorithm. Assuming we can handle the posterior on φ and the conditional on θ given φ. If we build a Gibbs sampler instead, we face a difficulty with the normalising constant m(y|φ). Said Gibbs sampler thus does not work in generating from the “cut” target. Maybe an alternative borrowing from the rather large if disparate missing constant toolbox. (In any case, we do not simulate from the original joint distribution.) The natural solution would then be to make a independent proposal on φ with target the posterior given z and then any scheme that preserves the conditional of θ given φ and y; “any” is rather wistful thinking at this stage since the only practical solution that I see is to run a Metropolis-Hasting sampler long enough to “reach” stationarity… I also remain with a lingering although not life-threatening question of whether or not the BUGS code using cut distributions provide the “right” answer or not. Here are my five slides used during the seminar (with a random walk implementation that did not diverge from the true target…):

[speakerdeck https://speakerdeck.com/xianblog/slides-for-mcmski-4-decompression-seminar-at-crest%5D