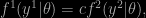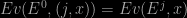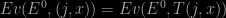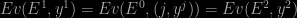Archive for Jim Berger

Cancún, ISBA 2014 [day #0]

Posted in Statistics, Travel, University life with tags , , , , , , , , on July 17, 2014 by xi'an

Day zero at ISBA 2014! The relentless heat outside (making running an ordeal, even at 5:30am…) made the (air-conditioned) conference centre the more attractive. Jean-Michel Marin and I had a great morning teaching our ABC short course and we do hope the ABC class audience had one as well. Teaching in pair is much more enjoyable than single as we can interact with one another as well as the audience. And realising unsuspected difficulties with the material is much easier this way, as the (mostly) passive instructor can spot the class’ reactions. This reminded me of the course we taught together in Oulu, northern Finland, in 2004 and that ended as the Bayesian Core. We did not cover the entire material we have prepared for this short course, but I think the pace was the right one. (Just tell me otherwise if you were there!) This was also the only time I had given a course wearing sunglasses, thanks to yesterday’s incident!

Waiting for a Spanish speaking friend to kindly drive with me downtown Cancún to check whether or not an optician could make me new prescription glasses, I attended Jim Berger’s foundational lecture on frequentist properties of Bayesian procedures but could only listen as the slides were impossible for me to read, with or without glasses. The partial overlap with the Varanasi lecture helped. I alas had to skip both Gareth Roberts’ and Sylvia Früwirth-Schnatter’s lectures, apologies to both of them!, but the reward was to get a new pair of prescription glasses within a few hours. Perfectly suited to my vision! And to get back just in time to read slides during Peter Müller’s lecture from the back row! Thanks to my friend Sophie for her negotiating skills! Actually, I am still amazed at getting glasses that quickly, given the time it would have taken in, e.g., France. All set for another 15 years with the same pair?! Only if I do not go swimming with them in anything but a quiet swimming pool!

The starting dinner happened to coincide with the (second) ISBA Fellow Award ceremony. Jim acted as the grand master of ceremony and he did great to add life and side stories to the written nominations for each and everyone of the new Fellows. The Fellowships honoured Bayesian statisticians who had contributed to the field as researchers and to the society since its creation. I thus feel very honoured (and absolutely undeserving) to be included in this prestigious list, along with many friends.  (But would have loved to see two more former ISBA presidents included, esp. for their massive contribution to Bayesian theory and methodology…) And also glad to wear regular glasses instead of my morning sunglasses.

[My Internet connection during the meeting being abysmally poor, the posts will appear with some major delay! In particular, I cannot include new pictures at times I get a connection… Hence a picture of northern Finland instead of Cancún at the top of this post!]

reading classics (#10 and #10bis)

Posted in Books, Statistics, University life with tags , , , , , , , , , on February 28, 2013 by xi'an

Today’s classics seminar was rather special as two students were scheduled to talk. It was even more special as both students had picked (without informing me) the very same article by Berger and Sellke (1987), Testing a point-null hypothesis: the irreconcilability of p-values and evidence, on the (deep?) discrepancies between frequentist p-values and Bayesian posterior probabilities. In connection with the Lindley-Jeffreys paradox. Here are Amira Mziou’s slides:

and Jiahuan Li’s slides:

for comparison.

It was a good exercise to listen to both talks, seeing two perspectives on the same paper, and I hope the students in the class got the idea(s) behind the paper. As you can see, there were obviously repetitions between the talks, including the presentation of the lower bounds for all classes considered by Jim Berger and Tom Sellke, and the overall motivation for the comparison. Maybe as a consequence of my criticisms on the previous talk, both Amira and Jiahuan put some stress on the definitions to formally define the background of the paper. (I love the poetic line: “To prevent having a non-Bayesian reality”, although I am not sure what Amira meant by this…)

I like the connection made therein with the Lindley-Jeffreys paradox since this is the core idea behind the paper. And because I am currently writing a note about the paradox. Obviously, it was hard for the students to take a more remote stand on the reason for the comparison, from questioning .the relevance of testing point null hypotheses and of comparing the numerical values of a p-value with a posterior probability, to expecting asymptotic agreement between a p-value and a Bayes factor when both are convergent quantities, to setting the same weight on both hypotheses, to the ad-hocquery of using a drift on one to equate the p-value with the Bayes factor, to use specific priors like Jeffreys’s (which has the nice feature that it corresponds to g=n in the g-prior,  as discussed in the new edition of Bayesian Core). The students also failed to remark on the fact that the developments were only for real parameters, as the phenomenon (that the lower bound on the posterior probabilities is larger than the p-value) does not happen so universally in larger dimensions.  I would have expected more discussion from the ground, but we still got good questions and comments on a) why 0.05 matters and b) why comparing  p-values and posterior probabilities is relevant. The next paper to be discussed will be Tukey’s piece on the future of statistics.

That the likelihood principle does not hold…

Posted in Statistics, University life with tags , , , , , , , , , , on October 6, 2011 by xi'an

Coming to Section III in Chapter Seven of Error and Inference, written by Deborah Mayo, I discovered that she considers that the likelihood principle does not hold (at least as a logical consequence of the combination of the sufficiency and of the conditionality principles), thus that  Allan Birnbaum was wrong…. As well as the dozens of people working on the likelihood principle after him! Including Jim Berger and Robert Wolpert [whose book sells for $214 on amazon!, I hope the authors get a hefty chunk of that ripper!!! Esp. when it is available for free on project Euclid…] I had not heard of  (nor seen) this argument previously, even though it has apparently created enough of a bit of a stir around the likelihood principle page on Wikipedia. It does not seem the result is published anywhere but in the book, and I doubt it would get past a review process in a statistics journal. [Judging from a serious conversation in Zürich this morning, I may however be wrong!]

The core of Birnbaum’s proof is relatively simple: given two experiments E¹ and E² about the same parameter θ with different sampling distributions f¹ and f², such that there exists a pair of outcomes (y¹,y²) from those experiments with proportional likelihoods, i.e. as a function of θ

f^1(y^1|\theta) = c f^2(y^2|\theta),

one considers the mixture experiment E⁰ where E¹ and E² are each chosen with probability ½. Then it is possible to build a sufficient statistic T that is equal to the data (j,x), except when j=2 and x=y², in which case T(j,x)=(1,y¹). This statistic is sufficient since the distribution of (j,x) given T(j,x) is either a Dirac mass or a distribution on {(1,y¹),(2,y²)} that only depends on c. Thus it does not depend on the parameter θ. According to the weak conditionality principle, statistical evidence, meaning the whole range of inferences possible on θ and being denoted by Ev(E,z), should satisfy

Ev(E^0, (j,x)) = Ev(E^j,x)

Because the sufficiency principle states that

Ev(E^0, (j,x)) = Ev(E^0,T(j,x))

this leads to the likelihood principle

Ev(E^1,y^1)=Ev(E^0, (j,y^j)) = Ev(E^2,y^2)

(See, e.g., The Bayesian Choice, pp. 18-29.) Now, Mayo argues this is wrong because

“The inference from the outcome (Ej,yj) computed using the sampling distribution of [the mixed experiment] E⁰ is appropriately identified with an inference from outcome yj based on the sampling distribution of Ej, which is clearly false.” (p.310)

This sounds to me like a direct rejection of the conditionality principle, so I do not understand the point. (A formal rendering in Section 5 using the logic formalism of A’s and Not-A’s reinforces my feeling that the conditionality principle is the one criticised and misunderstood.) If Mayo’s frequentist stance leads her to take the sampling distribution into account at all times, this is fine within her framework. But I do not see how this argument contributes to invalidate Birnbaum’s proof. The following and last sentence of the argument may bring some light on the reason why Mayo considers it does:

“The sampling distribution to arrive at Ev(E⁰,(j,yj)) would be the convex combination averaged over the two ways that yj could have occurred. This differs from the  sampling distributions of both Ev(E1,y1) and Ev(E2,y2).” (p.310)

Indeed, and rather obviously, the sampling distribution of the evidence Ev(E*,z*) will differ depending on the experiment. But this is not what is stated by the likelihood principle, which is that the inference itself should be the same for y¹ and y². Not the distribution of this inference. This confusion between inference and its assessment is reproduced in the “Explicit Counterexample” section, where p-values are computed and found to differ for various conditional versions of a mixed experiment. Again, not a reason for invalidating the likelihood principle. So, in the end, I remain fully unconvinced by this demonstration that Birnbaum was wrong. (If in a bystander’s agreement with the fact that frequentist inference can be built conditional on ancillary statistics.)

Publication from the frontier

Posted in Books, Statistics, Travel with tags , , , on September 29, 2010 by xi'an

In conjunction with the conference in San Antonio last March, I have received the book Frontiers of Statistical Decision Making and Bayesian Analysis: In Honor of James O. Berger edited by Ming-Hui Chen (University of Connecticut), Dipak K. Dey (University of Connecticut), Peter Müller (University of Texas M. D. Anderson Cancer Center), Dongchu Sun (University of Missouri- Columbia) and Keying Ye (University of Texas at San Antonio), who, incidentally, were are PhD students of Jim Berger at the time I visited Purdue University. The book has been edited in depth and so it reads very well, with contributions regrouped by chapters. Here is the table of contents:

  1. Introduction.
  2. Objective Bayesian inference with applications.
  3. Bayesian decision based estimation and predictive inference.
  4. Bayesian model selection and hypothesis tests.
  5. Bayesian computer models.
  6. Bayesian nonparametrics and semi-parametrics.
  7. Bayesian case influence and frequentist interface.
  8. Bayesian clinical trials.
  9. Bayesian methods for genomics, molecular, and systems biology.
  10. Bayesian data mining and machine learning.
  11. Bayesian inference in political and social sciences, finance, and marketing.
  12. Bayesian categorical data analysis.
  13. Bayesian geophysical, spatial, and temporal statistics.
  14. Posterior simulation and Monte Carlo methods.

whose final chapter (the only one missing Bayesian from the title!) contains our contribution with Jean-Michel Marin.

[more] impressions from the frontier

Posted in Statistics, Travel, University life with tags , , , , on March 20, 2010 by xi'an

Apart from my (theoretical) Bayes factor session, I attended non-parametric, and two other Bayes factor sessions  at Frontiers of Statistical Decision Making and Bayesian Analysis today! (I forgot to mention the talk of Kenneth Rice yesterday that related to my early 1990’s work with George Casella and Juinn Hwang on integrating estimation loss functions into testing losses). I liked very much Ed George’s extension of the g-prior, as well as Elias Moreno’s prior modelling of clustering models (along with Guido Consonni’s and Adrian Raftery’s talks in the same session). As commented by many participants to the conference, one major difficulty was to figure out which of the three parallel sessions to choose…  The plenary sessions were superb as well, with Steve Fienberg describing an analysis of a highly (highly) complex model on aging, and Persi Diaconis giving us the flavour of his lastest work with David Aldous on quasi-exchangeability, with exctracts from de Finetti.

on of the g-prior, as well as Elias Moreno’s prior modelling of clustering models (along with Guido Consonni’s and Adrian Raftery’s talks in the same session).