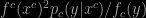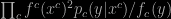Archive for Langevin diffusion

scalable Langevin exact algorithm [Read Paper]

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , on June 23, 2020 by xi'an


Murray Pollock, Paul Fearnhead, Adam M. Johansen and Gareth O. Roberts (CoI: all with whom I have strong professional and personal connections!) have a Read Paper discussion happening tomorrow [under relaxed lockdown conditions in the UK, except for the absurd quatorzine on all travelers|, but still in a virtual format] that we discussed together [from our respective homes] at Paris Dauphine. And which I already discussed on this blog when it first came out.

Here are quotes I spotted during this virtual Dauphine discussion but we did not come up with enough material to build a significant discussion, although wondering at the potential for solving the O(n) bottleneck, handling doubly intractable cases like the Ising model. And noticing the nice features of the log target being estimable by unbiased estimators. And of using control variates, for once well-justified in a non-trivial environment.

“However, in practice this simple idea is unlikely to work. We can see this most clearly with the rejection sampler, as the probability of survival will decrease exponentially with t—and thus the rejection probability will often be prohibitively large.”

“This can be viewed as a rejection sampler to simulate from μ(x,t), the distribution of the Brownian motion at time  t conditional on its surviving to time t. Any realization that has been killed is ‘rejected’ and a realization that is not killed is a draw from μ(x,t). It is easy to construct an importance sampling version of this rejection sampler.”

mean field Langevin system & neural networks

Posted in Statistics with tags , , , , , , , on February 4, 2020 by xi'an

A colleague of mine in Paris Dauphine, Zhenjie Ren, recently gave a talk on recent papers of his connecting neural nets and Langevin. Estimating the parameters of the NNs by mean-field Langevin dynamics. Following from an earlier paper on the topic by Mei, Montanari & Nguyen in 2018. Here are some notes I took during the seminar, not necessarily coherent as I was a bit under the weather that day. And had no previous exposure to most notions.

Fitting a one-layer network is turned into a minimisation programme over a measure space (when using loads of data). A reformulation that makes the problem convex. Adding a regularisation by the entropy and introducing derivatives of a functional against the measure. With a necessary and sufficient condition for the solution to be unique when the functional is convex. This reformulation leads to a Fokker-Planck equation, itself related with a Langevin diffusion. Except there is a measure in the Langevin equation, which stationary version is the solution of the original regularised minimisation programme.

A second paper contains an extension to deep NN, re-expressed as a problem in a random environment. Or with a marginal constraint (one marginal distribution being constrained). With a partial derivative wrt the marginal measure. Turning into a Langevin diffusion with an extra random element. Using optimal control produces a new Hamiltonian. Eventually producing the mean-field Langevin system as backward propagation. Coefficients being computed by chain rule, equivalent to a Euler scheme for Langevin dynamics.

This approach holds consequence for GANs with discriminator as one-layer NN and generator minimised over two measures. The discriminator is the invariant measure of the mean-field Langevin dynamics. Mentioning Metropolis-Hastings GANs which seem to require one full run of an MCMC algorithm at each iteration of the mean-field Langevin.

Monte Carlo fusion

Posted in Statistics with tags , , , , , , , , , on January 18, 2019 by xi'an

Hongsheng Dai, Murray Pollock (University of Warwick), and Gareth Roberts (University of Warwick) just arXived a paper we discussed together last year while I was at Warwick. Where fusion means bringing different parts of the target distribution

f(x)∝f¹(x)f²(x)…

together, once simulation from each part has been done. In the same spirit as in Scott et al. (2016) consensus Monte Carlo. Where for instance the components of the target cannot be computed simultaneously, either because of the size of the dataset, or because of privacy issues.The idea in this paper is to target an augmented density with the above marginal, using for each component of f, an auxiliary variable x¹,x²,…, and a target that is the product of the squared component, f¹(x¹)², f²(x²)², … by a transition density keeping f¹(.)²,f²(.)²,… invariant:

f^c(x^c)^2 p_c(y|x^c) / f_c(y)

as for instance the transition density of a Langevin diffusion. The marginal of

\prod_c f^c(x^c)^2 p_c(y|x^c) / f_c(y)

as a function of y is then the targeted original product. Simulating from this new extended target can be achieved by rejection sampling. (Any impact of the number of auxiliary variables on the convergence?) The practical implementation actually implies using the path-space rejection sampling methods in the Read Paper of Beskos et al. (2006). (An extreme case of the algorithm is actually an (exact) ABC version where the simulations x¹,x²,… from all components have to be identical and equal to y. The opposite extreme is the consensus Monte Carlo Algorithm, which explains why this algorithm is not an efficient solution.) An alternative is based on an Ornstein-Uhlenbeck bridge. While the paper remains at a theoretical level with toy examples, I heard from the same sources that applications to more realistic problems and implementation on parallel processors is under way.

Langevin on a wrong bend

Posted in Books, Statistics with tags , , , , , , , on October 19, 2017 by xi'an

Arnak Dalayan and Avetik Karagulyan (CREST) arXived a paper the other week on a focussed study of the Langevin algorithm [not MALA] when the gradient of the target is incorrect. With the following improvements [quoting non-verbatim from the paper]:

  1. a varying-step Langevin that reduces the number of iterations for a given Wasserstein precision, compared with recent results by e.g. Alan Durmus and Éric Moulines;
  2. an extension of convergence results for error-prone evaluations of the gradient of the target (i.e., the gradient is replaced with a noisy version, under some moment assumptions that do not include unbiasedness);
  3. a new second-order sampling algorithm termed LMCO’, with improved convergence properties.

What is particularly interesting to me in this setting is the use in all these papers of a discretised Langevin diffusion (a.k.a., random walk with a drift induced by the gradient of the log-target) without the original Metropolis correction. The results rely on an assumption of [strong?] log-concavity of the target, with “user-friendly” bounds on the Wasserstein distance depending on the constants appearing in this log-concavity constraint. And so does the adaptive step. (In the case of the noisy version, the bias and variance of the noise also matter. As pointed out by the authors, there is still applicability to scaling MCMC for large samples. Beyond pseudo-marginal situations.)

“…this, at first sight very disappointing behavior of the LMC algorithm is, in fact, continuously connected to the exponential convergence of the gradient descent.”

The paper concludes with an interesting mise en parallèle of Langevin algorithms and of gradient descent algorithms, since the convergence rates are the same.

non-reversible Langevin samplers

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , on February 6, 2017 by xi'an

In the train to Oxford yesterday night, I read through the recently arXived Duncan et al.’s Nonreversible Langevin Samplers: Splitting Schemes, Analysis and Implementation. Standing up the whole trip in the great tradition of British trains.

The paper is fairly theoretical and full of Foster-Lyapunov assumptions but aims at defending an approach based on a non-reversible diffusion. One idea is that the diffusion based on the drift {∇ log π(x) + γ(x)} is associated with the target π provided

∇ . {π(x)γ(x)} = 0

which holds for the Langevin diffusion when γ(x)=0, but produces a non-reversible process in the alternative. The Langevin choice γ(x)=0 happens to be the worst possible when considering the asymptotic variance. In practice however the diffusion need be discretised, which induces an approximation that may be catastrophic for convergence if not corrected, and a relapse into reversibility if corrected by Metropolis. The proposal in the paper is to use a Lie-Trotter splitting I had never heard of before to split between reversible [∇ log π(x)] and non-reversible [γ(x)] parts of the process. The deterministic part is chosen as γ(x)=∇ log π(x) [but then what is the point since this is Langevin?] or as the gradient of a power of π(x). Although I was mostly lost by that stage, the paper then considers the error induced by a numerical integrator related with this deterministic part, towards deriving asymptotic mean and variance for the splitting scheme. On the unit hypercube. Although the paper includes a numerical example for the warped normal target, I find it hard to visualise the implementation of this scheme. Having obviously not heeded Nicolas’ and James’ advice, the authors also analyse the Pima Indian dataset by a logistic regression!)