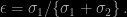Archive for Larry Wasserman

did I mean endemic? [pardon my French!]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , on June 26, 2014 by xi'an

clouds, Nov. 02, 2011Deborah Mayo wrote a Saturday night special column on our Big Bayes stories issue in Statistical Science. She (predictably?) focussed on the critical discussions, esp. David Hand’s most forceful arguments where he essentially considers that, due to our (special issue editors’) selection of successful stories, we biased the debate by providing a “one-sided” story. And that we or the editor of Statistical Science should also have included frequentist stories. To which Deborah points out that demonstrating that “only” a frequentist solution is available may be beyond the possible. And still, I could think of partial information and partial inference problems like the “paradox” raised by Jamie Robbins and Larry Wasserman in the past years. (Not the normalising constant paradox but the one about censoring.) Anyway, the goal of this special issue was to provide a range of realistic illustrations where Bayesian analysis was a most reasonable approach, not to raise the Bayesian flag against other perspectives: in an ideal world it would have been more interesting to get discussants produce alternative analyses bypassing the Bayesian modelling but obviously discussants only have a limited amount of time to dedicate to their discussion(s) and the problems were complex enough to deter any attempt in this direction.

As an aside and in explanation of the cryptic title of this post, Deborah wonders at my use of endemic in the preface and at the possible mis-translation from the French. I did mean endemic (and endémique) in a half-joking reference to a disease one cannot completely get rid of. At least in French, the term extends beyond diseases, but presumably pervasive would have been less confusing… Or ubiquitous (as in Ubiquitous Chip for those with Glaswegian ties!). She also expresses “surprise at the choice of name for the special issue. Incidentally, the “big” refers to the bigness of the problem, not big data. Not sure about “stories”.” Maybe another occurrence of lost in translation… I had indeed no intent of connection with the “big” of “Big Data”, but wanted to convey the notion of a big as in major problem. And of a story explaining why the problem was considered and how the authors reached a satisfactory analysis. The story of the Air France Rio-Paris crash resolution is representative of that intent. (Hence the explanation for the above picture.)
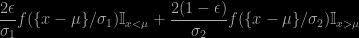
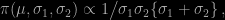
Jeffreys prior with improper posterior

Posted in Books, Statistics, University life with tags , , , , , , , , , , on May 12, 2014 by xi'an

In a complete coincidence with my visit to Warwick this week, I became aware of the paper “Inference in two-piece location-scale models with Jeffreys priors” recently published in Bayesian Analysis by Francisco Rubio and Mark Steel, both from Warwick. Paper where they exhibit a closed-form Jeffreys prior for the skewed distribution

\dfrac{2\epsilon}{\sigma_1}f(\{x-\mu\}/\sigma_1)\mathbb{I}_{x<\mu}+\dfrac{2(1-\epsilon)}{\sigma_2}f(\{x-\mu\}/\sigma_2) \mathbb{I}_{x>\mu}

where f is a symmetric density, namely

\pi(\mu,\sigma_1,\sigma_2) \propto 1 \big/ \sigma_1\sigma_2\{\sigma_1+\sigma_2\}\,,

where

\epsilon=\sigma_1/\{\sigma_1+\sigma_2\}\,.

only to show  immediately after that this prior does not allow for a proper posterior, no matter what the sample size is. While the above skewed distribution can always be interpreted as a mixture, being a weighted sum of two terms, it is not strictly speaking a mixture, if only because the “component” can be identified from the observation (depending on which side of μ is stands). The likelihood is therefore a product of simple terms rather than a product of a sum of two terms.

As a solution to this conundrum, the authors consider the alternative of the “independent Jeffreys priors”, which are made of a product of conditional Jeffreys priors, i.e., by computing the Jeffreys prior one parameter at a time with all other parameters considered to be fixed. Which differs from the reference prior, of course, but would have been my second choice as well. Despite criticisms expressed by José Bernardo in the discussion of the paper… The difficulty (in my opinion) resides in the choice (and difficulty) of the parameterisation of the model, since those priors are not parameterisation-invariant. (Xinyi Xu makes the important comment that even those priors incorporate strong if hidden information. Which relates to our earlier discussion with Kaniav Kamari on the “dangers” of prior modelling.)

Although the outcome is puzzling, I remain just slightly sceptical of the income, namely Jeffreys prior and the corresponding Fisher information: the fact that the density involves an indicator function and is thus discontinuous in the location μ at the observation x makes the likelihood function not differentiable and hence the derivation of the Fisher information not strictly valid. Since the indicator part cannot be differentiated. Not that I am seeing the Jeffreys prior as the ultimate grail for non-informative priors, far from it, but there is definitely something specific in the discontinuity in the density. (In connection with the later point, Weiss and Suchard deliver a highly critical commentary on the non-need for reference priors and the preference given to a non-parametric Bayes primary analysis. Maybe making the point towards a greater convergence of the two perspectives, objective Bayes and non-parametric Bayes.)

This paper and the ensuing discussion about the properness of the Jeffreys posterior reminded me of our earliest paper on the topic with Jean Diebolt. Where we used improper priors on location and scale parameters but prohibited allocations (in the Gibbs sampler) that would lead to less than two observations per components, thereby ensuring that the (truncated) posterior was well-defined. (This feature also remained in the Series B paper, submitted at the same time, namely mid-1990, but only published in 1994!)  Larry Wasserman proved ten years later that this truncation led to consistent estimators, but I had not thought about it in very long while. I still like this notion of forcing some (enough) datapoints into each component for an allocation (of the latent indicator variables) to be an acceptable Gibbs move. This is obviously not compatible with the iid representation of a mixture model, but it expresses the requirement that components all have a meaning in terms of the data, namely that all components contributed to generating a part of the data. This translates as a form of weak prior information on how much we trust the model and how meaningful each component is (in opposition to adding meaningless extra-components with almost zero weights or almost identical parameters).

As a marginalia, the insistence in Rubio and Steel’s paper that all observations in the sample be different also reminded me of a discussion I wrote for one of the Valencia proceedings (Valencia 6 in 1998) where Mark presented a paper with Carmen Fernández on this issue of handling duplicated observations modelled by absolutely continuous distributions. (I am afraid my discussion is not worth the $250 price tag given by amazon!)

estimating a constant

Posted in Books, Statistics with tags , , , , , , , , , on October 3, 2012 by xi'an

Paulo (a.k.a., Zen) posted a comment in StackExchange on Larry Wasserman‘s paradox about Bayesians and likelihoodists (or likelihood-wallahs, to quote Basu!) being unable to solve the problem of estimating the normalising constant c of the sample density, f, known up to a constant

f(x) = c g(x)

(Example 11.10, page 188, of All of Statistics)

My own comment is that, with all due respect to Larry!, I do not see much appeal in this example, esp. as a potential criticism of Bayesians and likelihood-wallahs…. The constant c is known, being equal to

1/\int_\mathcal{X} g(x)\text{d}x

If c is the only “unknown” in the picture, given a sample x1,…,xn, then there is no statistical issue whatsoever about the “problem” and I do not agree with the postulate that there exist estimators of c. Nor priors on c (other than the Dirac mass on the above value). This is not in the least a statistical problem but rather a numerical issue.That the sample x1,…,xn can be (re)used through a (frequentist) density estimate to provide a numerical approximation of c

\hat c = \hat f(x_0) \big/ g(x_0)

is a mere curiosity. Not a criticism of alternative statistical approaches: e.g., I could also use a Bayesian density estimate…

Furthermore, the estimate provided by the sample x1,…,xn is not of particular interest since its precision is imposed by the sample size n (and converging at non-parametric rates, which is not a particularly relevant issue!), while I could use importance sampling (or even numerical integration) if I was truly interested in c. I however find the discussion interesting for many reasons

  1. it somehow relates to the infamous harmonic mean estimator issue, often discussed on the’Og!;
  2. it brings more light on the paradoxical differences between statistics and Monte Carlo methods, in that statistics is usually constrained by the sample while Monte Carlo methods have more freedom in generating samples (up to some budget limits). It does not make sense to speak of estimators in Monte Carlo methods because there is no parameter in the picture, only “unknown” constants. Both fields rely on samples and probability theory, and share many features, but there is nothing like a “best unbiased estimator” in Monte Carlo integration, see the case of the “optimal importance function” leading to a zero variance;
  3. in connection with the previous point, the fascinating Bernoulli factory problem is not a statistical problem because it requires an infinite sequence of Bernoullis to operate;
  4. the discussion induced Chris Sims to contribute to StackExchange!

Normal deviate is on!

Posted in University life with tags , , , on June 16, 2012 by xi'an

Larry Wasserman has just started his own blog! It is called Normal deviate (and is hosted by WordPress). This is quite a good news as Larry’s opinions are always worth considering (even though I do not necessarily agree with them!). The themes of this blog are Statistics and Machine Learning.

down with referees, up with ???

Posted in Books, Statistics, University life, Wines with tags , , , , , , , , , , on April 18, 2012 by xi'an

Statisfaction made me realise I had missed the latest ISBA Bulletin when I read what Julyan posted about Larry’s tribune on a World without referees. While I agree on many of Larry’s points, first and foremost on his criticisms of the refereeing process which seems to worsen and worsen, here are a few items of dissension…

The argument that the system is 350 years old and thus must be replaced may be ok at the rethoretical level, but does not carry any serious weight! First, what is the right scale for a change: 100 years?! 200 years?! Should I burn down my great-grand-mother’s house because it is from the 1800’s and buy a camping-car instead?! Should I smash my 1690 Stradivarius and buy a Fender Stratocaster?! Further, given the intensity and the often under-the-belt level of the Newton vs. Leibniz dispute, maybe refereeing and publishing in the Philosophical Transactions of the Royal Society should have been abolished right away from the start. Anyway, this is about rethoric, not matter. (Same thing about the wine store ellipse. It is not even a good one:  Indeed, when I go to a wine store, I have to rely on (a) well-known brands; (b) brands I have already tried and appreciated; (c) someone else’s advice, like the owner, or friends, or Robert Parker…. In the former case, it can prove great or disastrous. But this is the most usual way to pick wines as one cannot hope [dream?] to sample all wines in the shop.)

My main issue with doing away with referees is the problem of sifting through the chaff. The amount of research documents published everyday is overwhelming. There is a maximal amount of time I can dedicate to looking at websites, blogs, twitter accounts like Scott Sisson’s and Richard Everitt’s, and such. And there clearly is a limited amount of trust I put in the opinions expressed in a blog (e.g., take the ‘Og where this anonymous X’racter writes about everything, mostly non-scientific stuff, and reviews papers with a definite bias!) Even keeping track of new arXiv postings sometimes get overwhelming. So, Larry’s “if you don’t check arXiv for new papers every day, then you are really missing out” means to me that missing arXiv for a few days and I cannot recover. One week away at an intense workshop or on vacations and I am letting some papers going by forever, even though I carry them in my bag for a while…. Noll’s suggestion to publish only on one’s own website is even more unrealistic: why should anyone bother to comment on poor or wrong papers, except when looking for ‘Og’s fodder?! So the fundamental problem is separating the wheat from the chaff, given the amount of chaff and the connected tendency to choke on it! Getting rid of referees and journals to rely on depositories like [the great, terrific, essential] arXiv forces me to also rely on other sources for ranking, selecting, and eliminating papers. Again with a component of arbitrariness, subjectivity, bias, variation, randomness, peer pressure, &tc. In addition, having no prior check of papers means reading a new paper a tremendous chore as one would have to check the references as well, leading to a sort of infinite regress… and forcing one to rely on reputation and peer opinions, once again! And imagine the inflation in reference letters! I already feel I have to write too many reference letters at the moment, but a world without (good and bad) journals would be the Hell of non-stop reference letters. I definitely prefer to referee (except for Elsevier!) and even more being a journal editor, because I can get an idea of the themes in the field and sometimes spot new trends, rather than writing over and over again about an old friend’s research achievements or having to assess from scratch the worth of a younger colleague’s work…

Furthermore, and this is a more general issue, I do not believe that the multiplication of blogs, websites, opinion posts, tribunes, &tc., is necessarily a “much more open, democratic approach”: everyone voicing an opinion on the Internet does not always get listened to and the loudest ones (or most popular ones) are not always the most reliable ones. A complete egalitarian principle means everyone talks/writes and no one listens/reads: I’d rather stick to the principles set by the Philosophical Transactions of the Royal Society!

Anyway, thanks to Larry for launching a worthwhile debate into discovering new ways of making academia a more rational and scientific place!