 Next summer of 2017, the biennial International Conference on Monte Carlo Methods and Applications (MCM) will take place in Montréal, Québec, Canada, on July 3-7. This is a mathematically-oriented meeting that works in alternance with MCqMC and that is “devoted to the study of stochastic simulation and Monte Carlo methods in general, from the theoretical viewpoint and in terms of their effective applications in different areas such as finance, statistics, machine learning, computer graphics, computational physics, biology, chemistry, and scientific computing in general. It is one of the most prominent conference series devoted to research on the mathematical aspects of stochastic simulation and Monte Carlo methods.” I attended one edition in Annecy three years ago and enjoyed very much the range of topics and backgrounds. The program is under construction and everyone is warmly invited to contribute talks or special sessions, with a deadline on January 20, 2017. In addition, Montréal is a Monte Carlo Mecca of sorts with leading researchers in the field like Luc Devroye and Pierre Lécuyer working there. (And a great place to visit in the summer!)
Archive for Luc Devroye
je reviendrai à Montréal [MCM 2017]
Posted in pictures, R, Running, Statistics, Travel with tags Annecy, Canada, conference, Luc Devroye, MCM, MCM 2017, MCQMC, Monte Carlo methods, Monte Carlo Statistical Methods, Montréal, Pierre Lecuyer, Québec, stochastic simulation on November 3, 2016 by xi'anratio-of-uniforms [#2]
Posted in Books, R, Statistics with tags Luc Devroye, mixtures of distributions, Non-Uniform Random Variate Generation, pseudo-random generator, R, ratio of uniform algorithm, slice sampler on October 31, 2016 by xi'an Following my earlier post on Kinderman’s and Monahan’s (1977) ratio-of-uniform method, I must confess I remain quite puzzled by the approach. Or rather by its consequences. When looking at the set A of (u,v)’s in R⁺×X such that 0≤u²≤ƒ(v/u), as discussed in the previous post, it can be represented by its parameterised boundary
u(x)=√ƒ(x),v(x)=x√ƒ(x) x in X
Similarly, since the simulation from ƒ(v/u) can also be derived [check Luc Devroye’s Non-uniform random variate generation in the exercise section 7.3] from a uniform on the set B of (u,v)’s in R⁺×X such that 0≤u≤ƒ(v+u), on the set C of (u,v)’s in R⁺×X such that 0≤u³≤ƒ(v/√u)², or on the set D of (u,v)’s in R⁺×X such that 0≤u²≤ƒ(v/u), which is actually exactly the same as A [and presumably many other versions!, for which I would like to guess the generic rule of construction], there are many sets on which one can consider running simulations. And one to pick for optimality?! Here are the three sets for a mixture of two normal densities:
 For instance, assuming slice sampling is feasible on every one of those three sets, which one is the most efficient? While I have no clear answer to this question, I found on Sunday night that a generic family of transforms is indexed by a differentiable monotone function h over the positive half-line, with the uniform distribution being taken over the set
H={(u,v);0≤u≤h(f(v/g(u))}
when the primitive G of g is the inverse of h, i.e., G(h(x))=x. [Here are the slides I gave at the Warwick reading group on Devroye’s book last week:]
ratio-of-uniforms
Posted in Books, pictures, R, Statistics with tags Luc Devroye, Non-Uniform Random Variate Generation, random number generation, ratio of uniform algorithm, University of Warwick on October 24, 2016 by xi'anOne approach to random number generation that had always intrigued me is Kinderman and Monahan’s (1977) ratio-of-uniform method. The method is based on the result that the uniform distribution on the set A of (u,v)’s in R⁺xX such that
0≤u²≤ƒ(v/u)
induces the distribution with density proportional to ƒ on V/U. Hence the name. The proof is straightforward and the result can be seen as a consequence of the fundamental lemma of simulation, namely that simulating from the uniform distribution on the set B of (w,x)’s in R⁺xX such that
0≤w≤ƒ(x)
induces the marginal distribution with density proportional to ƒ on X. There is no mathematical issue with this result, but I have difficulties with picturing the construction of efficient random number generators based on this principle.
 I thus took the opportunity of the second season of [the Warwick reading group on] Non-uniform random variate generation to look anew at this approach. (Note that the book is freely available on Luc Devroye’s website.) The first thing I considered is the shape of the set A. Which has nothing intuitive about it! Luc then mentions (p.195) that the boundary of A is given by
u(x)=√ƒ(x),v(x)=x√ƒ(x)
which then leads to bounding both ƒ and x→x²ƒ(x) to create a box around A and an accept-reject strategy, but I have trouble with this result without making further assumptions about ƒ… Using a two component normal mixture as a benchmark, I found bounds on u(.) and v(.) and simulated a large number of points within the box to end up with the above graph that indeed the accepted (u,v)’s were within this boundary. And the same holds with a more ambitious mixture:

correlation matrices on copulas
Posted in R, Statistics, University life with tags copulas, correlation, Gérard Letac, Luc Devroye, Marc Yor on July 4, 2016 by xi'an
 Following my post of yesterday about the missing condition in Lynch’s R code, Gérard Letac sent me a paper he recently wrote with Luc Devroye on correlation matrices and copulas. Paper written for the memorial volume in honour of Marc Yor. It considers the neat problem of the existence of a copula (on [0,1]x…x[0,1]) associated with a given correlation matrix R. And establishes this existence up to dimension n=9. The proof is based on the consideration of the extreme points of the set of correlation matrices. The authors conjecture the existence of (10,10) correlation matrices that cannot be a correlation matrix for a copula. The paper also contains a result that answers my (idle) puzzling of many years, namely on how to set the correlation matrix of a Gaussian copula to achieve a given correlation matrix R for the copula. More precisely, the paper links the [correlation] matrix R of X~N(0,R) with the [correlation] matrix R⁰ of Φ(X) by
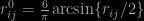
A side consequence of this result is that there exist correlation matrices of copulas that cannot be associated with Gaussian copulas. Like

Гнеде́нко and Forsythe [and e]
Posted in Books, Kids, R, Statistics, University life with tags Гнеде́нко, exponential distribution, George Forsythe, Gnedenko, John von Neumann, Luc Devroye, Monte Carlo Statistical Methods, Theory of Probability, uniform distribution on February 16, 2016 by xi'an In the wake of my earlier post on the Monte Carlo estimation of e and e⁻¹, after a discussion with my colleague Murray Pollock (Warwick) Gnedenko’s solution, he pointed out another (early) Monte Carlo approximation called Forsythe’s method. That is detailed quite neatly in Luc Devroye’s bible, Non-uniform random variate generation (a free bible!). The idea is to run a sequence of uniform generations until the sequence goes up, i.e., until the latest uniform is larger than the previous one. The expectation of the corresponding stopping rule, N, which is the number of generations the uniform sequence went down continuously is then e, while the probability that N is odd is e⁻¹, most unexpectedly! Forsythe’s method actually aims at a much broader goal, namely simulating from any density of the form g(x) exp{-F(x)}, F taking values in (0,1). This method generalises von Neuman’s exponential generator (see Devroye, p.126) which only requires uniform generations.
 This is absolutely identical to Gnedenko’s approach in that both events have the same 1/n! probability to occur [as pointed out by Gérard Letac in a comment on the previous entry]. (I certainly cannot say whether or not one of the authors was aware of the other’s result: Forsythe generalised von Neumann‘s method around 1972, while Gnedenko published Theory of Probability at least in 1969, but this may be the date of the English translation, I have not been able to find the reference on the Russian wikipedia page…) Running a small R experiment to compare both distributions of N, the above barplot shows that they look quite similar:
[sourcecode language=”r” gutter=”false”]
n=1e6
use=runif(n)
# Gnedenko’s in action:
gest=NULL
i=1
while (i<(n-100)){
sumuse=cumsum(use[i:(i+10)])
if (sumuse[11]<1])
sumuse=cumsum(use[i:(i+100)])
j=min((1:length(sumuse))[sumuse>1])
gest=c(gest,j)
i=i+j}
#Forsythe’s method:
fest=NULL
i=1
while (i<(n-100)){
sumuse=c(-1,diff(use[i:(i+10)]))
if (max(sumuse)<0])
sumuse=c(-1,diff(use[i:(i+100)]))
j=min((1:length(sumuse))[sumuse>0])
fest=c(fest,j)
i=i+j}
[/sourcecode]
And the execution times of both approaches [with this rudimentary R code!] are quite close.


