
Archive for machine learning
computo on the go
Posted in Books, R, Statistics, University life with tags binary, Biometrika, Computo, editor in chief, free software, French researchers, github, journal, Julia, Latin, logo, machine learning, open access, open source, Python, Quarto, R, repositories, reproducible research, Rmarkdown, SFDS, Société française de Statistique, Statistics on April 8, 2025 by xi'an
handbook of sharing confidential data [book review]
Posted in Statistics with tags Bayesian privacy, book review, Census Bureau, CHANCE, Chapman & Hall, CRC Press, deep learning, differential privacy, EU, GDPR, handbook, LaTeX, machine learning, PRNG on March 12, 2025 by xi'an A new Chapman & Hall handbook appeared on the most current issue of confidentiality and privacy, which has been edited by Jörg Drechsler, Daniel Kifer, Jerome Reiter, and Aleksandra Slavković. The forty authors of the 18 chapters are mostly from the U.S., with a few outliers from Edinburgh (involved in two chapters on protecting the Scottish Longitudinal Study and the U.S. IRS tax data) and Tallinn (for a chapter on secure multi-party computation applications). This means a more U.S. centric focus for realistic implementations as, e.g., with the Census Bureau (which employs 25% of the authors), than those implied by EU regulations, for instance.
Overall, I enjoyed reading these chapters and would certainly use the book as a first entry to a graduate course on privacy (as opposed to some books I recently reviewed). The first two chapters are 100% formula-free and thus more surveys than informative entries to the field, imho. The following Part II on formal privacy techniques covers the expected standards of differential privacy, local vs. global design, single vs. multiple queries, consequence on learning machines and statistical procedures. Concerning Bayesian aspects, Chapter 7 about private machine learning has two paragraphs on the privacy properties of MCMC algorithms albeit not exposing clearly enough that privacy vanishes as the number of iterations grows to infinity. Chapter 8 concentrates on statistical differential privacy, much along my own perception of the requirements for a genuine statistical approach, with Bayesian aspects not sidelined. If less critical of differential privacy than I. Chapter 9 focusses on system issues, investing a dozen pages into the specifics of pseudo-random generators. Part III is about synthetic data, with some overlap between the first two chapters. (I would deem DP need not be introduced by Chapter 12.) I find the section rather superficial, mostly formula free, and lacking in the statistical impact.
As an aside, I am disappointed at the poor rendering of (mathematical) equations making me wonder which type of LaTeX, if any, was used. There are even genuine typos that seem to result from cut and past encoding errors (see, e.g., the final accentuated c of Sklavković). The reference lists are plentiful, see e.g. the 164 entries for Chapter 7, to the point it would have made more sense to regroup them into a single bibliography. (The predictable reply being that chapters are sold separately and need their respective reference lists.)
[Disclaimer about potential self-plagiarism: this post or an edited version of it could possibly appear in my Books Review section in CHANCE.]
Hands-On Differential Privacy [book review]
Posted in Books, R, Statistics, University life with tags Bayesian inference, biases, book review, CHANCE, classification, coding, contextual integrity, differential privacy, GANs, Harvard, Laplace distribution, LaTeX, Lipschitz continuity, machine learning, O'Reilly Media, OpenDP, Python, slate pencil sea urchin, Type I error, Type II error on October 2, 2024 by xi'anHands-On Differential Privacy was published just a few months ago (from September 2024!) by (the US publisher) O’Reilly, famous for its programming and technical books with animal covers! A slate pencil sea urchin in the present case. The book is indeed classical O’Reilly’s, with lots of notes, little theory (or maths!) and symbols, a loose structuring of the chapters (no section numbers) and highly detailed examples, and of course plenty of OpenDP code inserts. For instance, in the present case, a case study about the privatization of a sample average x̄ that takes about ten pages. Terrible equation rendering btw (what’s wrong with LATEX?!). Overall, I am quickly lost in most of the chapters due to a lack of a driving narrative, facing instead a catalogue of possible scenari and procedures, appearing one after the other as in a fashion show.
Hands-On Differential Privacy is written by Ethan Cowan, Michael Shoemate, and Mayana Pereira. I came across the book during the OpenDP workshop at Harvard [that took place right after my return from the Pacific Northwest] and it is definitely linked with OpenDP, all authors being actually involved at one stage or another in the OpenDP Team. The style of the book is once again in tune with the O’Reilly manuals, which sort of clashes with my preferences. For instance, the introduction of differential privacy (Chapter 2) is quite extensive. Chapter 3 proceeds to teach about private data transform(ation)s, stability (a rewording of Lipschitz-ianity), with code illustrations, often repeating the earlier derivation (see eg p203), while Chapter 4 is its equivalent for private mechanisms. (With the diagrams Figures 3-1 and 4-1 differing only in highlighting/bolding different functions in a privatized data processing pipeline.) Returning to differential privacy with a privacy loss parameter and to Laplace and exponential mechanisms, Chapter 5 proposes several notions of privacy, all closed under post-processing. This includes Wasserman and Zhou (2010) interpretation of privacy as hypothesis testing, except it is not exploited further than connecting type I and type II with (ε,δ) parameters. Chapter 6 concludes Part I about concepts with a series of (fearless) combinators, keeping stability and privacy. With an increasing proportion of coding excerpts which I [imho] did not find particularly helpful.
 Nothing about statistical loss of information or efficiency, bias, &tc. until Chapter 8 (p199) and even then so little. Part II is about practice, with a first Chapter 7 on setting a privacy unit (e.g., a person-month) before ensuring their privacy is protected. And discussing unbounded contributions (not unbounded data!). While Chapter 8 very thinly covers statistical modelling, while remaining agnostic about the choice of statistical procedures (Bayes being solely and naïvely mentioned for classification, furthermore with data-based evaluation of the class “prior” probabilities, p211). At this stage, procedures are often only defined through spinets of code, like the private Theil-Sen estimator (pp204-205). The continuous case boils to a Normality assumption, with its pmf being defined (p212) as

which contains at least three errors! Chapter 9 is the equivalent of Chapter 8 for machine learning, mostly centred on private gradient descent. And a Pytorch section (pp232-235). Completed by a light Chapter 10 on synthetic data, which does not seem to broach upon the issue of large dimension covariates, providing instead a list of GAN synthetizers.
Part III (Deploying differential privacy) is even more about practice, with Chapter 11 on privacy attacks, Chapter 12 on calibrating a privacy mechanism (co-written with Jayshree Sarathy), and good practice (like codebooks and data annotations), with the appearance of contextual integrity I discovered if not perfectly understood last year at the BIRS workshop in Kelowna. And Chapter 13 on planning a privacy project, with an 11 step checklist, most of which are quite vague [imho] and do include strategies to make the data owners confident their privacy is safe.
[Disclaimer about potential self-plagiarism: this post or an edited version will eventually appear in my Books Review section in CHANCE]
Nature tidbits
Posted in Books, pictures, Statistics, University life with tags AI, Brave New World, climate change, Clockwork Orange, CO2 levels, cover, frogs, Huber loss, Intergovernmental Panel on Climate Change, loss functions, machine learning, Nature, neural networks and learning machines, neuroscience of religions, sauna, temperature anomalies, ZRR on September 2, 2024 by xi'an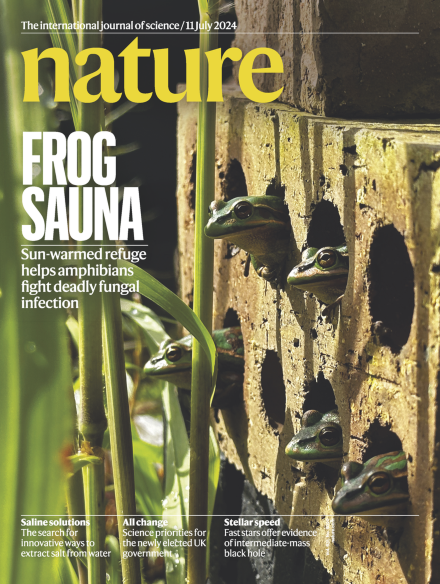
- a “technology and tools” long article on picking the “right” loss function when constructing an algorithmic predictor or another ML tool,
 although the author remains vague about the “rightness” part (with an incorrect entry for Huber loss). The message is however clearly that tuning the loss function to the problem one wants to address is (obviously) key. With additional advices about properly handling outliers, avoiding overfitting, and correctly modelling noise. In short, run a proper statistical analysis!
- a call for neuroscientists not to be afraid of studying religions, which should sound like an obviousness, but believers and religious leaders are often so touchy about their faith that running representative scientific studies of the “brain processes associated with religiosity and spirituality” may prove inaccessible. I also find the statement “researchers might be able to get a better handle on what (if any) alterations happen in people’s brains in the rare instances when religious belief turns to radicalized action or sectarian hatred” closer to Brave New World or Clockwork Orange than to the purpose of Nature!
- the warmest summer ever, ever, ever…

- a scary story from South Korea where an academic got sentenced to two years in prison for sharing data with Chinese collaborators on “national core technology”, a case reminiscent of similar ones earlier in the US. And where the academic researcher is again seen as the sole culprit instead of their university or the government sharing the responsibility. In France, the imminent threat to turn mathematics and statistics labs into restrictive regime zones (ZRR), with much heavier constraints on visitors and students, and on publication contents, carried by the researchers themselves, pertains from the same tendency. (A personal illustration of the induced administrative absurdities: my datascience lab being next to a biomedical ZRR lab, I am not allowed to use the lift shared by both units, but can nonetheless reach the same spot using the nearby stairs.)
Alexandre Bouchard-Côté, 2004 CRM-SSC Prize in Statistics winner
Posted in Statistics with tags bouncy particle sampler, British Columbia, Centre de recherches mathématiques, computational statistics, CRM-SSC, machine learning, Montréal, non-reversible MCMC, phylogenetic tree, prize, Québec, Société Statistique du Canada, SSC, UBC, University of British Columbia, Vancouver on May 18, 2024 by xi'an


