Julien Stoehr, Pierre Pudlo, and Lionel Cucala (I3M, Montpellier) arXived yesterday a paper entitled “Geometric summary statistics for ABC model choice between hidden Gibbs random fields“. Julien had presented this work at the MCMski 4 poster session. The move to a hidden Markov random field means that our original approach with Aude Grelaud does not apply: there is no dimension-reduction sufficient statistics in that case… The authors introduce a small collection of (four!) focussed statistics to discriminate between Potts models. They further define a novel misclassification rate, conditional on the observed value and derived from the ABC reference table. It is the predictive error rate
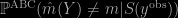
integrating in both the model index m and the corresponding random variable Y (and the hidden intermediary parameter) given the observation. Or rather the transform of the observation by the summary statistic S. In a simulation experiment, the paper shows that the predictive error rate decreases quite a lot by including 2 or 4 geometric summary statistics on top of the no-longer-sufficient concordance statistics. (I did not find how the distance is constructed and how it adapts to a larger number of summary statistics.)
“[the ABC posterior probability of index m] uses the data twice: a first one to calibrate the set of summary statistics, and a second one to compute the ABC posterior.” (p.8)
It took me a while to understand the above quote. If we consider ABC model choice as we did in our original paper, it only and correctly uses the data once. However, if we select the vector of summary statistics based on an empirical performance indicator resulting from the data then indeed the procedure does use the data twice! Is there a generic way or trick to compensate for that, apart from cross-validation?

 This is the last day at


