An interesting paper by Murray Aitkin, Charles Liu, and Tom Chadwick is due to appear in the Annals of Applied Statistics. Its main focus is the comparison of models for a specific problem of small area estimation, but it also contains general views on Bayesian model choice that relates to our earlier paper about DIC and to our reassessment of Bayes factor approximation with Jean-Michel Marin. In connection with Aitkin’s 1991 paper, this paper considers the posterior distribution of the likelihood. For one given model, this amounts to using the likelihood twice since the posterior expectation of the likelihood equals
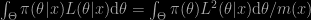
This made me first think that DIC may suffer from the same drawback since

hence integrates a quantity that depends on x against the posterior, but this is not the same since

appears like a Kullback-Leibler divergence between the prior and the posterior distributions. Back to the paper, it suggest to run model comparison via the distribution of the likelihood ratio values

where the 


which do not correspond to genuine Bayesian solutions, in my opinion, because the data x is used repeatedly in this process, producing a sample from the product of the posteriors, instead of using pseudo-priors as in Carlin and Chib (Series B, 1995). In addition, I fail to see how to interpret the “posterior” distribution of this quantity, even under the condition of using pseudo-priors, as it will also reflect the joint distribution, while a coherent model choice procedure should only depend on the marginal (model-wise) distributions (which reminds me of an old criticism against Pitman nearness…)
 in an altogether different way, namely as a tool assessing the goodness of fit of a given model. It reminds me of Richard Wilkinson’s earlier ABC paper, discussed on that

 is the data and
 plays the role of the likelihood. (The
 are obviously the priors on
 and
 given
 is distributed from
 . The authors then derive an ABC algorithm they call ABCμ to simulate an MCMC chain targeting this joint distribution, replacing
 . The product being most often defined as a density in
 it can be simulated from, but I have trouble seeing this as a regular Bayesian problem, especially because it seems the prior on

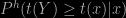 to define the “surprise” means that
 . (What one does with this evaluation is another issue!)]


