Archive for nested sampling

likelihood-free nested sampling

Posted in Books, Statistics with tags , , , , , , on April 11, 2022 by xi'an

Last week, I came by chance across a paper by Jan Mikelson and Mustafa Khammash on a likelihood-free version of nested sampling (a popular keyword on the ‘Og!). Published in 2020 in PLoS Comput Biol. The setup is a parameterised and hidden state-space model, which allows for an approximation of the (observed) likelihood function L(θ|y) by means of a particle filter. An immediate issue with this proposal is that a novel  filter need be produced for a new value of the parameter θ, which makes it enormously expensive. It then gets more bizarre as the [Monte Carlo] distribution of the particle filter approximation ô(θ|y) is agglomerated with the original prior π(θ) as a joint “prior” [despite depending on the observed y] and a nested sampling is conducted with level sets of the form

ô(θ|y)>ε.

Actually, if the Monte Carlo error was null, that is, if the number of particles was infinite,

ô(θ|y)=L(θ|y)

implies that this is indeed the original nested sampler. Simulation from the restricted region is done by constructing an extra density estimator of the constrained distribution (in θ)…

“We have shown how using a Monte Carlo estimate over the livepoints not only results in an unbiased estimator of the Bayesian evidence Z, but also allows us to derive a formulation for a lower bound on the achievable variance in each iteration (…)”

As shown by the above the authors insist on the unbiasedness of the particle approximation, but since nested sampling is not producing an unbiased estimator of the evidence Z, the point is somewhat moot. (I am also rather surprised by the reported lack of computing time benefit in running ABC-SMC.)

F(1-F)

Posted in Books, Kids, Statistics with tags , , , on March 9, 2022 by xi'an

When answering an X validated question about the covariance between a random variable X and its cdf transform F(X), I realised that it was half the integral of the function

x → F(x)(1-F(x))

when X is centred. It is not surprising in the least to see the cdf appearing for this second order expectation, since it can similarly be used to represent first order expectations (as exploited by nested sampling). But it is easy to be confused by the fact that F(X) is usually a Uniform (0,1) variate hence distribution-free, until one sees it remains positively correlated with X, or by the apparent lack of scale or by the symmetry, until one realises this is not the case. (The associated correlation is scale-free.)

[more than] everything you always wanted to know about marginal likelihood

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , on February 10, 2022 by xi'an

Earlier this year, F. Llorente, L. Martino, D. Delgado, and J. Lopez-Santiago have arXived an updated version of their massive survey on marginal likelihood computation. Which I can only warmly recommend to anyone interested in the matter! Or looking for a base camp to initiate a graduate project. They break the methods into four families

  1. Deterministic approximations (e.g., Laplace approximations)
  2. Methods based on density estimation (e.g., Chib’s method, aka the candidate’s formula)
  3. Importance sampling, including sequential Monte Carlo, with a subsection connecting with MCMC
  4. Vertical representations (mostly, nested sampling)

Besides sheer computation, the survey also broaches upon issues like improper priors and alternatives to Bayes factors. The parts I would have done in more details are reversible jump MCMC and the long-lasting impact of Geyer’s reverse logistic regression (with the noise contrasting extension), even though the link with bridge sampling is briefly mentioned there. There is even a table reporting on the coverage of earlier surveys. Of course, the following postnote of the manuscript

The Christian Robert’s blog deserves a special mention , since Professor C. Robert has devoted several entries of his blog with very interesting comments regarding the marginal likelihood estimation and related topics.

does not in the least make me less objective! Some of the final recommendations

  • use of Naive Monte Carlo [simulate from the prior] should be always considered [assuming a proper prior!]
  • a multiple-try method is a good choice within the MCMC schemes
  • optimal umbrella sampling estimator is difficult and costly to implement , so its best performance may not be achieved in practice
  • adaptive importance sampling uses the posterior samples to build a suitable normalized proposal, so it benefits from localizing samples in regions of high posterior probability while preserving the properties of standard importance sampling
  • Chib’s method is a good alternative, that provide very good performances [but is not always available]
  • the success [of nested sampling] in the literature is surprising.

invertible flow non equilibrium sampling (InFiNE)

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on May 21, 2021 by xi'an

With Achille Thin and a few other coauthors [and friends], we just arXived a paper on a new form of importance sampling, motivated by a recent paper of Rotskoff and Vanden-Eijnden (2019) on non-equilibrium importance sampling. The central ideas of this earlier paper are the introduction of conformal Hamiltonian dynamics, where a dissipative term is added to the ODE found in HMC, namely
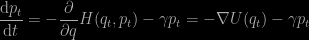
\dfrac{\text d p_t}{\text dt}=-\dfrac{\partial}{\partial q}H(q_t,p_t)-\gamma p_t=-\nabla U(q_t)-\gamma p_t

which means that all orbits converge to fixed points that satisfy ∇U(q) = 0 as the energy eventually vanishes. And the property that, were T be a conformal Hamiltonian integrator associated with H, i.e. perserving the invariant measure, averaging over orbits of T would improve the precision of Monte Carlo unbiased estimators, while remaining unbiased. The fact that Rotskoff and Vanden-Eijnden (2019) considered only continuous time makes their proposal hard to implement without adding approximation error, while our approach is directly set in discrete-time and preserves unbiasedness. And since measure preserving transforms are too difficult to come by, a change of variable correction, as in normalising flows, allows for an arbitrary choice of T, while keeping the estimator unbiased. The use of conformal maps makes for a natural choice of T in this context.

The resulting InFiNE algorithm is an MCMC particular algorithm which can be represented as a  partially collapsed Gibbs sampler when using the right auxiliary variables. As in Andrieu, Doucet and Hollenstein (2010) and their ISIR algorithm. The algorithm can be used for estimating normalising constants, comparing favourably with AIS, sampling from complex targets, and optimising variational autoencoders and their ELBO.

I really appreciated working on this project, with links to earlier notions like multiple importance sampling à la Owen and Zhou (2000), nested sampling, non-homogeneous normalising flows, measure estimation à la Kong et al. (2002), on which I worked in a more or less distant past.

nested sampling: any prior anytime?!

Posted in Books, pictures, Statistics, Travel with tags , , , , , , , , , , , , on March 26, 2021 by xi'an

A recent arXival by Justin Alsing and Will Handley on “nested sampling with any prior you like” caught my attention. If only because I was under the impression that some priors would not agree with nested sampling. Especially those putting positive weight on some fixed levels of the likelihood function, as well as improper priors.

“…nested sampling has largely only been practical for a somewhat restrictive class of priors, which have a readily available representation as a transform from the unit hyper-cube.”

Reading from the paper, it seems that the whole point is to demonstrate that “any proper prior may be transformed onto the unit hypercube via a bijective transformation.” Which seems rather straightforward if the transform is not otherwise constrained: use a logit transform in every direction. The paper gets instead into the rather fashionable direction of normalising flows as density representations. (Which suddenly reminded me of the PhD dissertation of Rob Cornish at Oxford, which I examined last year. Even though nested was not used there in the same understanding.) The purpose appearing later (in the paper) or in fine to express a random variable simulated from the prior as the (generative) transform of a Uniform variate, f(U). Resuscitating the simulation from an arbitrary distribution from first principles.

“One particularly common scenario where this arises is when one wants to use the (sampled) posterior from one experiment as the prior for another”

But I remained uncertain at the requirement for this representation in implementing nested sampling as I do not see how it helps in bypassing the hurdles of simulating from the prior constrained by increasing levels of the likelihood function. It would be helpful to construct normalising flows adapted to the truncated priors but I did not see anything related to this version in the paper.

The cosmological application therein deals with the incorporation of recent measurements in the study of the ΛCDM cosmological model, that is, more recent that the CMB Planck dataset we played with 15 years ago. (Time flies, even if an expanding Universe!) Namely, the Baryon Oscillation Spectroscopic Survey and the SH0ES collaboration.