Archive for non-parametrics

Inference for stochastic simulation models by ABC

Posted in Books, Statistics, University life with tags , , , , , on February 13, 2015 by xi'an

Hartig et al. published a while ago (2011) a paper  in Ecology Letters entitled “Statistical inference for stochastic simulation models – theory and application”, which is mostly about ABC. (Florian Hartig pointed out the paper to me in a recent blog comment. about my discussion of the early parts of Guttman and Corander’s paper.) The paper is largely a tutorial and it reminds the reader about related methods like indirect inference and methods of moments. The authors also insist on presenting ABC as a particular case of likelihood approximation, whether non-parametric or parametric. Making connections with pseudo-likelihood and pseudo-marginal approaches. And including a discussion of the possible misfit of the assumed model, handled by an external error model. And also introducing the notion of informal likelihood (which could have been nicely linked with empirical likelihood). A last class of approximations presented therein is called rejection filters and reminds me very much of Ollie Ratman’s papers.

“Our general aim is to find sufficient statistics that are as close to minimal sufficiency as possible.” (p.819)

As in other ABC papers, and as often reported on this blog, I find the stress on sufficiency a wee bit too heavy as those models calling for approximation almost invariably do not allow for any form of useful sufficiency. Hence the mathematical statistics notion of sufficiency is mostly useless in such settings.

“A basic requirement is that the expectation value of the point-wise approximation of p(Sobs|φ) must be unbiased” (p.823)

As stated above the paper is mostly in tutorial mode, for instance explaining what MCMC and SMC methods are. As illustrated by the above figure. There is however a final and interesting discussion section on the impact of estimating the likelihood function at different values of the parameter. However, the authors seem to focus solely on pseudo-marginal results to validate this approximation, hence on unbiasedness, which does not work for most ABC approaches that I know. And for the approximations listed in the survey. Actually, it would be quite beneficial to devise a cheap tool to assess the bias or extra-variation due to the use of approximative techniques like ABC… A sort of 21st Century bootstrap?!
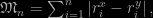
Bayesian optimization for likelihood-free inference of simulator-based statistical models

Posted in Books, Statistics, University life with tags , , , , on January 29, 2015 by xi'an

Michael Gutmann and Jukka Corander arXived this paper two weeks ago. I read part of it (mostly the extended introduction part) on the flight from Edinburgh to Birmingham this morning. I find the reflection it contains on the nature of the ABC approximation quite deep and thought-provoking.  Indeed, the major theme of the paper is to visualise ABC (which is admittedly shorter than “likelihood-free inference of simulator-based statistical models”!) as a regular computational method based on an approximation of the likelihood function at the observed value, yobs. This includes for example Simon Wood’s synthetic likelihood (who incidentally gave a talk on his method while I was in Oxford). As well as non-parametric versions. In both cases, the approximations are based on repeated simulations of pseudo-datasets for a given value of the parameter θ, either to produce an estimation of the mean and covariance of the sampling model as a function of θ or to construct genuine estimates of the likelihood function. As assumed by the authors, this calls for a small dimension θ. This approach actually allows for the inclusion of the synthetic approach as a lower bound on a non-parametric version.

In the case of Wood’s synthetic likelihood, two questions came to me:

  • the estimation of the mean and covariance functions is usually not smooth because new simulations are required for each new value of θ. I wonder how frequent is the case where we can always use the same basic random variates for all values of θ. Because it would then give a smooth version of the above. In the other cases, provided the dimension is manageable, a Gaussian process could be first fitted before using the approximation. Or any other form of regularization.
  • no mention is made [in the current paper] of the impact of the parametrization of the summary statistics. Once again, a Cox transform could be applied to each component of the summary for a better proximity of/to the normal distribution.

When reading about a non-parametric approximation to the likelihood (based on the summaries), the questions I scribbled on the paper were:

  • estimating a complete density when using this estimate at the single point yobs could possibly be superseded by a more efficient approach.
  • the authors study a kernel that is a function of the difference or distance between the summaries and which is maximal at zero. This is indeed rather frequent in the ABC literature, but does it impact the convergence properties of the kernel estimator?
  • the estimation of the tolerance, which happens to be a bandwidth in that case, does not appear to be processed in this paper, which could explain for very low probabilities of acceptance mentioned in the paper.
  • I am lost as to why lower bounds on likelihoods are relevant here. Unless this is intended for ABC maximum likelihood estimation.

Guttmann and Corander also comment on the first point, through the cost of producing a likelihood estimator. They therefore suggest to resort to regression and to avoid regions of low estimated likelihood. And rely on Bayesian optimisation. (Hopefully to be commented later.)

rate of convergence for ABC

Posted in Statistics, University life with tags , , , , on November 19, 2013 by xi'an

Barber, Voss, and Webster recently posted and arXived a paper entitled The Rate of Convergence for Approximate Bayesian Computation. The paper is essentially theoretical and establishes the optimal rate of convergence of the MSE—for approximating a posterior moment—at a rate of 2/(q+4), where q is the dimension of the summary statistic, associated with an optimal tolerance in n-1/4. I was first surprised at the role of the dimension of the summary statistic, but rationalised it as being the dimension where the non-parametric estimation takes place. I may have read the paper too quickly as I did not spot any link with earlier convergence results found in the literature: for instance, Blum (2010, JASA) links ABC with standard kernel density non-parametric estimation and find a tolerance (bandwidth) of order n-1/q+4 and an MSE of order 2/(q+4) as well. Similarly, Biau et al. (2013, Annales de l’IHP) obtain precise convergence rates for ABC interpreted as a k-nearest-neighbour estimator. And, as already discussed at length on this blog, Fearnhead and Prangle (2012, JRSS Series B) derive rates similar to Blum’s with a tolerance of order n-1/q+4 for the regular ABC and of order n-1/q+2 for the noisy ABC…

Le Monde rank test (cont’d)

Posted in R, Statistics with tags , , , on April 5, 2010 by xi'an

Following a comment from efrique pointing out that this statistic is called Spearman footrule, I want to clarify the notation in

\mathfrak{M}_n = \sum_{i=1}^n |r^x_i-r^y_i|\,,

namely (a) that the ranks of x_i and y_i are considered for the whole sample, i.e.

\{r^x_1,\ldots,r^x_n,r^y_1,\ldots,r^y_n\} = \{1,\ldots,2n\}

instead of being computed separately for the x‘s and the y‘s, and then (b) that the ranks are reordered for each group (meaning that the groups could be of different sizes). This statistics is therefore different from the Spearman footrule studied by Persi Diaconis and R. Graham in a 1977 JRSS paper,

\mathfrak{D}_ n = \sum_{i=1}^n |\pi(i)-\sigma(i)|\,,

where \pi and \sigma are permutations from \mathfrak{S}_n. The mean of \mathfrak{D}_ n is approximately n^{2/3}. I mistakenly referred to Spearman’s ρ rank correlation test in the previous post. It is actually much more related to the Siegel-Tukey test, even though I think there exists a non-parametric test of iid-ness for paired observations… The x‘s and the y‘s are thus not paired, despite what I wrote previously. This distance must be related to some non-parametric test for checking the equality of location parameters.

Exploratory Statistics with R

Posted in Statistics, University life with tags , , , , , on October 5, 2009 by xi'an

The exploratory Statistics course at Université Paris Dauphine has now started again and I am giving as in the past years the version of the course in English for interested students. Here are the slides (in English):

The course is intended for our third year students who already have two probability courses and one statistics course as background. The idea is to work only with small groups and only in the computer lab, so that they can experiment on the go. This approach is the result of several failed attempts when the students would not show up in class but only in the labs. The students take an on-line exam at the end of the course in January with multiple choice questions that must be argumented by attached R programs. This follows several years when the students were handling projects, due to massive cheating!