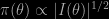Archive for noninformative priors

penalising model component complexity

Posted in Books, Mountains, pictures, Statistics, University life with tags , , , , , , , , , , on April 1, 2014 by xi'an

“Prior selection is the fundamental issue in Bayesian statistics. Priors are the Bayesian’s greatest tool, but they are also the greatest point for criticism: the arbitrariness of prior selection procedures and the lack of realistic sensitivity analysis (…) are a serious argument against current Bayesian practice.” (p.23)

A paper that I first read and annotated in the very early hours of the morning in Banff, when temperatures were down in the mid minus 20’s now appeared on arXiv, “Penalising model component complexity: A principled, practical approach to constructing priors” by Thiago Martins, Dan Simpson, Andrea Riebler, Håvard Rue, and Sigrunn Sørbye. It is a highly timely and pertinent paper on the selection of default priors! Which shows that the field of “objective” Bayes is still full of open problems and significant advances and makes a great argument for the future president [that I am] of the O’Bayes section of ISBA to encourage young Bayesian researchers to consider this branch of the field.

“On the other end of the hunt for the holy grail, “objective” priors are data-dependent and are not uniformly accepted among Bayesians on philosophical grounds.” (p.2)

Apart from the above quote, as objective priors are not data-dependent! (this is presumably a typo, used instead of model-dependent), I like very much the introduction (appreciating the reference to the very recent Kamary (2014) that just got rejected by TAS for quoting my blog post way too much… and that we jointly resubmitted to Statistics and Computing). Maybe missing the alternative solution of going hierarchical as far as needed and ending up with default priors [at the top of the ladder]. And not discussing the difficulty in specifying the sensitivity of weakly informative priors.

“Most model components can be naturally regarded as a flexible version of a base model.” (p.3)

The starting point for the modelling is the base model. How easy is it to define this base model? Does it [always?] translate into a null hypothesis formulation? Is there an automated derivation? I assume this somewhat follows from the “block” idea that I do like but how generic is model construction by blocks?

      germany-relative-risk

“Occam’s razor is the principle of parsimony, for which simpler model formulations should be preferred until there is enough support for a more complex model.” (p.4)

I also like this idea of putting a prior on the distance from the base! Even more because it is parameterisation invariant (at least at the hyperparameter level). (This vaguely reminded me of a paper we wrote with George a while ago replacing tests with distance evaluations.) And because it gives a definitive meaning to Occam’s razor. However, unless the hyperparameter ξ is one-dimensional this does not define a prior on ξ per se. I equally like Eqn (2) as it shows how the base constraint takes one away from Jeffrey’s prior. Plus, if one takes the Kullback as an intrinsic loss function, this also sounds related to Holmes’s and Walker’s substitute loss pseudopriors, no? Now, eqn (2) does not sound right in the general case. Unless one implicitly takes a uniform prior on the Kullback sphere of radius d? There is a feeling of one-d-ness in the description of the paper (at least till page 6) and I wanted to see how it extends to models with many (≥2) hyperparameters. Until I reached Section 6 where the authors state exactly that! There is also a potential difficulty in that d(ξ) cannot be computed in a general setting. (Assuming that d(ξ) has a non-vanishing Jacobian as on page 19 sounds rather unrealistic.) Still about Section 6, handling reference priors on correlation matrices is a major endeavour, which should produce a steady flow of followers..!

“The current practice of prior specification is, to be honest, not in a good shape. While there has been a strong growth of Bayesian analysis in science, the research field of “practical prior specification” has been left behind.” (*p.23)

There are still quantities to specify and calibrate in the PC priors, which may actually be deemed a good thing by Bayesians (and some modellers). But overall I think this paper and its message constitute a terrific step for Bayesian statistics and I hope the paper can make it to a major journal.

A discussion on Bayesian analysis : Selecting Noninformative Priors

Posted in Statistics with tags , , , , , , on February 26, 2014 by xi'an

Following an earlier post on the American Statistician 2013 paper by Seaman III and co-authors, Hidden dangers of specifying noninformative priors, my PhD student Kaniav Kamary wrote a paper re-analysing the examples processed by those authors and concluding to the stability of the posterior distributions of the parameters and to the effect of the noninformative prior being essentially negligible. (This is the very first paper quoting verbatim from the ‘Og!) Kaniav logically submitted the paper to the American Statistician.

hidden dangers of noninformative priors

Posted in Books, Statistics, University life with tags , , , , , on November 21, 2013 by xi'an

Last year, John Seaman (III), John Seaman (Jr.), and James Stamey published a paper in The American Statistician with the title Hidden dangers of specifying noninformative priors. (It does not seem to be freely available on-line.) I gave it to read to my PhD students, meaning to read towards the goal of writing a critical reply to the authors. In the meanwhile, here are my own two-cents on the paper.

“Applications typically employ Markov chain Monte Carlo (MCMC) methods to obtain posterior features, resulting in the need for proper priors, even when the modeler prefers that priors be relatively noninformative.” (p.77)

Apart from the above quote, which confuses proper priors with proper posteriors (maybe as the result of a contagious BUGS!), and which is used to focus solely and sort-of inappropriately on proper priors, there is no hard fact to bite in, but rather a collection of soft decisions and options that end up weakly supporting the authors’ thesis. (Obviously, following an earlier post, there is no such thing as a “noninformative” prior.) The paper is centred on four examples where a particular choice of (“noninformative”) prior leads to peaked or informative priors on some transform(s) of the parameters. Note that there is no definition provided for informative, non-informative, diffuse priors, except those found in BUGS with “extremely large variance” (p.77). (The quote below seems to settle on a uniform prior if one understands the “likely” as evaluated through the posterior density.) The argument of the authors is that “if parameters with diffuse proper priors are subsequently transformed, the resulting induced priors can, of course, be far from diffuse, possibly resulting in unintended influence on the posterior of the transformed parameters” (p.77).

Continue reading →

on noninformative priors

Posted in Books, Kids, Statistics with tags , , , , on August 5, 2013 by xi'an

A few weeks ago, Larry Wasserman posted on Normal Deviate an entry on noninformative priors as a lost cause for statistics. I first reacted rather angrily to this post, then decided against posting my reply. After a relaxing week in Budapest, and the prospect of the incoming summer break, I went back to the post and edited it towards more constructive  goals… The post also got discussed by Andrew and Entsophy, generating in each case a heap of heated discussions. (Enjoy your summer, winter is coming!)

Although Larry wrote he wanted to restrain from only posting on Bayesian statistics, he does seem attracted to them like a moth to a candle… This time, it is about the “lost cause of noninformative priors”. While Larry is 200% entitled to post about whatever he likes or dislikes, the post does not really bring new fuel to the debate, if debate there is. First, I think everyone agrees that there is no such thing as a noninformative prior or a prior representing ignorance. (To quote from Jeffreys: “A prior probability used to express ignorance is merely the formal statement of ignorance” (ToP, VIII, x8.1). Every prior brings something into the game and this is reflected in the posterior inference. Sometimes, the impact is enormous and we may be unaware of it. Take for instance Bayesian nonparametrics. It is thus essential to keep this in mind. (And to keep calm!) Which does not mean we should not use them. Indeed, noninformative priors are a way of setting a reference measure, from which one can start evaluating the impact of picking this or that prior. Just a measure. (No-one gets emotional when hearing the Lebesgue measure mentioned, right?!) And if the reference prior is a σ-finite measure, one cannot even put a meaning to events like θ>0. This reference measure is required to set the Bayesian crank turning, here or there depending on one’s prior beliefs or information. If we reject those reference priors for accepting only the cases when the prior is provided along with the data and the model, I think everyone is a Bayesian. Even Feller. Even Larry (?).

Second, there is alas too much pathos or unintended meaning put in names like noninformative, ignorance, objective, &tc. And this may be the major message in Larry’s post. We should call those reference priors Linear A priors in reference to the mostly undeciphered Minoan alphabet. Or whatever name with no emotional content whatsoever in order not to drive people crazy. Noninformative is not even a word, to start with… And I dunno how to define ignorance in a mathematical manner.Once more in connection with the EMS 2013 meeting in Budapest, I do not see why one should object more to reference priors than to the so-called “subjective” priors, as the former provide a baseline against which to test the latter, using e.g. Xiao Li’s approach. I am actually much more annoyed by the use of a specific proper prior in a statistical analysis when this prior is neither justified nor assessed in terms of robustness. And I see nothing wrong in establishing either asymptotic or frequentist properties about some procedures connected with some of those reference priors: I became a Bayesian this way, after all.

Keep Calm and CARRY ON PosterAnyway, have a nice (end of the) summer if you are in the Northern Hemisphere, and expect delays (or snapshots!) on the ‘Og for the coming fortnight…

why noninformative priors?

Posted in Books, Statistics, University life with tags , , , , on May 9, 2012 by xi'an

Answering a question around this theme on StackExchange, I wrote the following reply:

The debate about non-informative priors has been going on for ages, at least since the end of the 19th century with criticisms by Bertrand and de Morgan about the lack of invariance of Laplace’s uniform priors (the same criticism reported by Stéphane Laurent in the above comments). This lack of invariance sounded like a death stroke for the Bayesian approach and, while some Bayesians were desperately trying to cling to specific distributions, using less-than-formal arguments, others had a wider vision of a larger picture where priors could be used in situations where there was hardly any prior information, beyond the shape of the likelihood itself. (This was even before Abraham Wald established his admissibility and complete class results about Bayes procedures. And at about the same time as E.J.G. Pitman gave an “objective” derivation of the best invariant estimator as a Bayes estimator against the corresponding Haar measure…)

This vision is best represented by Jeffreys’ distributions, where the information matrix of the sampling model, I(\theta), is turned into a prior distribution

\pi(\theta) \propto |I(\theta)|^{1/2}

which is most often improper, i.e. does not integrate to a finite value. The label “non-informative” associated with Jeffreys’ priors is rather unfortunate, as they represent an input from the statistician, hence are informative about something! Similarly, “objective” has an authoritative weight I dislike… I thus prefer the label “reference prior”, used for instance by José Bernado.

Those priors indeed give a reference against which one can compute either the reference estimator/test/prediction or one’s own estimator/test/prediction using a different prior motivated by subjective and objective items of information. To answer directly the question, “why not use only informative priors?”, there is actually no answer. A prior distribution is a choice made by the statistician, neither a state of Nature nor a hidden variable. In other words, there is no “best prior” that one “should use”. Because this is the nature of statistical inference that there is no “best answer”.

Hence my defence of the noninformative/reference choice! It is providing the same range of inferential tools as other priors, but gives answers that are only inspired by the shape of the likelihood function, rather than induced by some opinion about the range of the unknown parameters.