Archive for NYC

dynamic mixtures and frequentist ABC

Posted in Statistics with tags , , , , , , , , , , , , , , , on November 30, 2022 by xi'an

This early morning in NYC, I spotted this new arXival by Marco Bee (whom I know from the time he was writing his PhD with my late friend Bernhard Flury) and found he has been working for a while on ABC related problems. The mixture model he considers therein is a form of mixture of experts, where the weights of the mixture components are not constant but functions on (0,1) of the entry as well. This model was introduced by Frigessi, Haug and Rue in 2002 and is often used as a benchmark for ABC methods, since it is missing its normalising constant as in e.g.
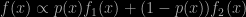
f(x) \propto p(x) f_1(x) + (1-p(x)) f_2(x)

even with all entries being standard pdfs and cdfs. Rather than using a (costly) numerical approximation of the “constant” (as a function of all unknown parameters involved), Marco follows the approximate maximum likelihood approach of my Warwick colleagues, Javier Rubio [now at UCL] and Adam Johansen. It is based on the [SAME] remark that under a uniform prior and using an approximation to the actual likelihood the MAP estimator is also the MLE for that approximation. The approximation is ABC-esque in that a pseudo-sample is generated from the true model (attached to a simulation of the parameter) and the pair is accepted if the pseudo-sample stands close enough to the observed sample. The paper proposes to use the Cramér-von Mises distance, which only involves ranks. Given this “posterior” sample, an approximation of the posterior density is constructed and then numerically optimised. From a frequentist view point, a direct estimate of the mode would be preferable. From my Bayesian perspective, this sounds like a step backwards, given that once a posterior sample is available, reconnecting with an approximate MLE does not sound highly compelling.

sampling, transport, and diffusions

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , on November 18, 2022 by xi'an


This week, I am attending a very cool workshop at the Flatiron Institute (not in the Flatiron building!, but close enough) on Sampling, Transport, and Diffusions, organised by Bob Carpenter and Michael Albergo. It is quite exciting as I do not know most participants or their work! The Flatiron Institute is a private institute focussed on fundamental science funded by the Simons Foundation (in such working conditions universities cannot compete with!).

Eric Vanden-Eijden gave an introductory lecture on using optimal transport notion to improve sampling, with a PDE/ODE approach of continuously turning a base distribution into a target (formalised by the distribution at time one). This amounts to solving a velocity solution to an KL optimisation objective whose target value is zero. Velocity parameterised as a deep neural network density estimator. Using a score function in a reverse SDE inspired by Hyvärinnen (2005), with a surprising occurrence of Stein’s unbiased estimator, there for the same reasons of getting rid of an unknown element. In a lot of environments, simulating from the target is the goal and this can be achieved by MCMC sampling by normalising flows, learning the transform / pushforward map.

At the break, Yuling Yao made a very smart remark that testing between two models could also be seen as an optimal transport, trying to figure an optimal transform from one model to the next, rather than the bland mixture model we used in our mixtestin paper. At this point I have no idea about the practical difficulty of using / inferring the parameters of this continuum but one could start from normalising flows. Because of time continuity, one would need some driving principle.

Esteban Tabak gave another interest talk on simulating from a conditional distribution, which sounds like a no-problem when the conditional density is known but a challenge when only pairs are observed. The problem is seen as a transport problem to a barycentre obtained as a distribution independent from the conditioning z and then inverting. Constructing maps through flows. Very cool, even possibly providing an answer for causality questions.

Many of the transport talks involved normalizing flows. One by [Simons Fellow] Christopher Jazynski about adding to the Hamiltonian (in HMC) an artificial flow field  (Vaikuntanathan and Jarzynski, 2009) to make up for the Hamiltonian moving too fast for the simulation to keep track. Connected with Eric Vanden-Eijden’s talk in the end.

An interesting extension of delayed rejection for HMC by Chirag Modi, with a manageable correction à la Antonietta Mira. Johnatan Niles-Weed provided a nonparametric perspective on optimal transport following Hütter+Rigollet, 21 AoS. With forays into the Sinkhorn algorithm, mentioning Aude Genevay’s (Dauphine graduate) regularisation.

Michael Lindsey gave a great presentation on the estimation of the trace of a matrix by the Hutchinson estimator for sdp matrices using only matrix multiplication. Solution surprisingly relying on Gibbs sampling called thermal sampling.

And while it did not involve optimal transport, I gave a short (lightning) talk on our recent adaptive restore paper: although in retrospect a presentation of Wasserstein ABC could have been more suited to the audience.

towers in the mist [jatp]

Posted in pictures, Running, Travel with tags , , , , , , , , , , , on November 17, 2022 by xi'an

Bill’s 80th!!!

Posted in pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , , , on April 17, 2022 by xi'an

“It was the best of times,
it was the worst of times”
[Dickens’ Tale of Two Cities (which plays a role in my friendship with Bill!)]

My flight to NYC last week was uneventful and rather fast and I worked rather well, even though the seat in front of me was inclined to the max for the entire flight! (Still got glimpses of Aline and of Deepwater Horizon from my neighbours.) Taking a very early flight from Paris was great making a full day once in NYC,  but “forcing” me to take a taxi, which almost ended up in disaster since the Über driver did not show up. At all. And never replied to my message. Fortunately trains were running, I was also running despite the broken rib, and I arrived at the airport some time before access was closed, grateful for the low activity that day. I also had another bit of a worrying moment at the US border control in JFK as I ended up in a back-office of the Border Police after the machine could not catch my fingerprints. And another stop at the luggage control as my lack of luggage sounded suspicious!The conference was delightful in celebrating Bill’s carreer and kindness (tinted with the most gentle irony!). Among stories told at the banquet, I was surprised to learn of Bill’s jazz career side, as I had never heard him play the piano or the clarinet! Even though we had chatted about music and literature on many occasions. Since our meeting in 1989… The (scientific side of the) conference included many talks around shrinkage, from loss estimation to predictive estimation, reminding me of the roaring 70’s and 80’s [James-Stein wise]. And demonstrating the impact of Bill’s wor throughout this era (incl. on my own PhD thesis). I started wondering at the (Bayesian) use of the loss estimate, though, as I set myself facing two point estimators attached with two estimators of their loss: it did not seem a particularly good idea to systematically pick the one with the smallest estimate (and Jim Berger confirmed this feeling on a later discussion). Among the talks on less familiar topics (of mine), I discovered work of Genevera Allen‘s on inferring massive network for neuron connections under sparse information. And of Emma Jingfei Zhang, equally centred on network inference, with applications to brain connectivity.

In a somewhat remote connection with Bill’s work (and our joint and hilarious assessment of Pitman closeness), I presented part of our joint and current work with Adrien Hairault and Judith Rousseau on inferring the number of components in a mixture by Bayes factors when the alternative is an infinite mixture (i.e., a Dirichlet process mixture). Of which Ruobin Gong gave a terrific discussion. (With a connection to her current work on Sense and Sensitivity.)

I was most sorry to miss Larry Wasserman’s and Rob Strawderman’s talk to rush back to the airport, the more because I am sure Larry’s talk would have brought a new light on causality (possibly equating it with tequila and mixtures!). The flight back was uneventfull, the plane rather empty and I slept most of the time. Overall,  it was most wonderful to re-connect with so many friends. Most of whom I had not seen for ages, even before the pandemic. And to meet new friends. (Nothing original in the reported feeling, just telling that the break in conferences and workshops was primarily a hatchet job on social relations and friendships.)