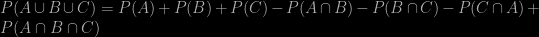Archive for paradoxes

paradoxes in scientific inference

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , on November 23, 2012 by xi'an

This CRC Press book was sent to me for review in CHANCE: Paradoxes in Scientific Inference is written by Mark Chang, vice-president of AMAG Pharmaceuticals. The topic of scientific paradoxes is one of my primary interests and I have learned a lot by looking at Lindley-Jeffreys and Savage-Dickey paradoxes. However, I did not find a renewed sense of excitement when reading the book. The very first (and maybe the best!) paradox with Paradoxes in Scientific Inference is that it is a book from the future! Indeed, its copyright year is 2013 (!), although I got it a few months ago. (Not mentioning here the cover mimicking Escher’s “paradoxical” pictures with dices. A sculpture due to Shigeo Fukuda and apparently not quoted in the book. As I do not want to get into another dice cover polemic, I will abstain from further comments!)

Now, getting into a deeper level of criticism (!), I find the book very uneven and overall quite disappointing. (Even missing in its statistical foundations.) Esp. given my initial level of excitement about the topic!

First, there is a tendency to turn everything into a paradox: obviously, when writing a book about paradoxes, everything looks like a paradox! This means bringing into the picture every paradox known to man and then some, i.e., things that are either un-paradoxical (e.g., Gödel’s incompleteness result) or uninteresting in a scientific book (e.g., the birthday paradox, which may be surprising but is far from a paradox!). Fermat’s theorem is also quoted as a paradox, even though there is nothing in the text indicating in which sense it is a paradox. (Or is it because it is simple to express, hard to prove?!) Similarly, Brownian motion is considered a paradox, as “reconcil[ing] the paradox between two of the greatest theories of physics (…): thermodynamics and the kinetic theory of gases” (p.51) For instance, the author considers the MLE being biased to be a paradox (p.117), while omitting the much more substantial “paradox” of the non-existence of unbiased estimators of most parameters—which simply means unbiasedness is irrelevant. Or the other even more puzzling “paradox” that the secondary MLE derived from the likelihood associated with the distribution of a primary MLE may differ from the primary. (My favourite!)

“When the null hypothesis is rejected, the p-value is the probability of the type I error.” Paradoxes in Scientific Inference (p.105)

“The p-value is the conditional probability given H0.” Paradoxes in Scientific Inference (p.106)

Second, the depth of the statistical analysis in the book is often found missing. For instance, Simpson’s paradox is not analysed from a statistical perspective, only reported as a fact. Sticking to statistics, take for instance the discussion of Lindley’s paradox. The author seems to think that the problem is with the different conclusions produced by the frequentist, likelihood, and Bayesian analyses (p.122). This is completely wrong: Lindley’s (or Lindley-Jeffreys‘s) paradox is about the lack of significance of Bayes factors based on improper priors. Similarly, when the likelihood ratio test is introduced, the reference threshold is given as equal to 1 and no mention is later made of compensating for different degrees of freedom/against over-fitting. The discussion about p-values is equally garbled, witness the above quote which (a) conditions upon the rejection and (b) ignores the dependence of the p-value on a realized random variable. Continue reading →

MCMC at ICMS (2)

Posted in Kids, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , on April 25, 2012 by xi'an

The second day of our workshop on computational statistics at the ICMS started with a terrific talk by Xiao-Li Meng. Although this talk related with his Inception talk in Paris last summer, and of the JCGS discussion paper, he brought new geometric aspects to the phenomenon (managing a zero correlation and hence i.i.d.-ness in the simulation of a Gaussian random effect posterior distribution). While I was reflecting about the difficulty to extend the perspective beyond normal models, he introduced a probit example where exact null correlation cannot be found but an adaptive scheme allows to explore the range of correlation coefficients. This made me somehow think of a possible version in this approach in a tempering perspective, where different data augmentation schemes would be merged into an “optimal” geometric mixture, rather than via interweaving.

As an aside, Xiao-Li mentioned the idea of Bayesian sufficiency and Bayesian ancilarity in the construction of his data augmentation schemes. He then concluded that sufficiency is identical in classical and Bayesian approaches, while ancilarity could be defined in several ways. I have already posted on that, but it seems to me that sufficiency is a weaker notion in the Bayesian perspective in the sense that all that matters is that the posterior is the same given the observation y and given the observed statistics, rather than uniformly over all possible values of the random variable Y as in the classical sense. As for ancilarity, it is also natural to consider that an ancillary statistics does not bring information on the parameter, i.e. that the prior and the posterior distributions are the same given the observed ancillary statistics. Going further to define ancilarity as posterior independence between “true” parameters and auxiliary variables, as Xiao-Li suggested, does not seem very sound as it leads to the paradoxes Basu liked so much!

Today, the overlap with the previous meetings in Bristol and in Banff was again limited: Arnaud Doucet rewrote his talk towards less technicity, which means I got the idea much more clearly than last week. The idea of having a sequence of pseudo-parameters with the same pseudo-prior seems to open a wide range of possible adaptive schemes. Faming Liang also gave a talk fairly similar to the one he presented in Banff. And David van Dyk as well, which led me to think anew about collapsed Gibbs samplers in connection with ABC and a project I just started here in Edinburgh.

Otherwise, the intense schedule of the day saw us through eleven talks. Daniele Impartato called for distributions (in the physics or Laurent Schwarz’ meaning of the term!) to decrease the variance of Monte Carlo estimations, an approach I hope to look further as Schwarz’ book is the first math book I ever bought!, an investment I tried to capitalize once in writing a paper mixing James-Stein estimation and distributions for generalised integration by part, paper that was repeatedly rejected until I gave up! Jim Griffin showed us improvements brought in the exploration of large number of potential covariates in linear and generalised linear models. Natesh Pillai tried to drag us through several of his papers on covariance matrix estimation, although I fear he lost me along the way! Let me perversely blame the schedule (rather than an early rise to run around Arthur’s Seat!) for falling asleep during Alex Beskos’ talk on Hamiltonian MCMC for diffusions, even though I was looking forward this talk. (Apologies to Alex!) Then Simon Byrne gave us a quick tour of differential geometry in connection with orthogonalization for Hamiltonian MCMC. Which brought me back very briefly to this early time I was still considering starting a PhD in differential geometry and then even more briefly played with the idea of mixing differential geometry and statistics à la Shun’ichi  Amari…. Ian Murray and  Simo Sarkka completed the day with a cartoonesque talk on latent Gaussians that connected well with Xiao-Li’s and a talk on Gaussian approximations to diffusions with unknown parameters, which kept within the main theme of the conference, namely inference on partly observed diffusions.

As written above, this was too intense a day, with hardly any free time to discuss about the talks or the ongoing projects, which makes me prefer the pace adopted in Bristol or in Banff. Having to meet a local student on leave from Dauphine for a year here did not help of course!)

Incoherent phyleogeographic inference [reply]

Posted in Statistics, University life with tags , , , , , , , , , on September 29, 2010 by xi'an

“Logical overlap is the norm for the complex models analyzed with ABC, so many ABC posterior model probabilities published to date are wrong.” Alan R. Templeton, PNAS, doi:10.1073/pnas.1009012107

Our letter in PNAS about Templeton’s surprising diatribe on Bayesian inference is now appeared in the early edition, along with Templeton’s reply. This reply is unfortunately missing any novelty element compared with the original paper. First, he maintains that the critcism is about ABC (which is, in case you do not know, a computational technique and not a specific statistical methodology!). Second, he insists on the inappropriate Venn diagram analogy by reproducing the basic identity

P(A\cup B\cup C) = P(A)+P(B)+P(C)-P(A\cap B)-P(B\cap C)-P(C\cap A)+P(A\cap B\cap C)

(presumably in case we had lost sight of it!) to argue that using instead

P(A)+P(B)+P(C)

is incoherent (hence rejecting Bayes factors, Bayesian model averaging and so on). I am not particularly surprised by this immutable stance, but it means that there is little point in debate when starting from such positions… Our main goal in publishing this letter was actually to stress that the earlier tribune had no statistical ground and I think we achieved this goal.