Archive for parallel processing

parallel MCMC via Weirstrass sampler

Posted in Books, Statistics, University life with tags , , , , , , , , on January 2, 2014 by xi'an

IMG_2230During O’Bayes 2013, Xiangyu Wang and David Dunson arXived a paper (with the above title) that David then presented on the 19th.  The setting is quite similar to the recently discussed embarrassingly parallel paper of Neiswanger et al., in that Xiangyu and David start from the same product representation of the target (posterior). Namely,

p(\theta|x) = \prod_{i=1}^m p_i(\theta|x).

However, they criticise the choice made by Neiswanger et al to use MCMC approximations to each component of the product for the following reasons:

  1. Curse of dimensionality in the number of parameters p
  2. Curse of dimensionality in the number of subsets m
  3. Tail degeneration
  4. Support inconsistency and mode misspecification Continue reading →

Asymptotically Exact, Embarrassingly Parallel MCMC

Posted in Books, Statistics, University life with tags , , , , , , on November 26, 2013 by xi'an

Departamento de Matemática, Universidad Complutense de Madrid, 11/11/11Willie Neiswanger, Chong Wang, and Eric Xing (from CMU) recently arXived a paper entitled as above. The “embarrassing” in the title refers to the “embarrassingly simple” solution proposed therein, namely to solve the difficulty in handling very large datasets by running completely independent parallel MCMC samplers on parallel threads or computers and using the outcomes of those samplers as density estimates, pulled together as a product towards an approximation of the true posterior density. In other words, the idea is to break the posterior as
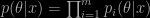
p(\theta|x) = \prod_{i=1}^m p_i(\theta|x)

and to use the estimate

\hat p(\theta|x) = \prod_{i=1}^m \hat p_i(\theta|x)

where the individual estimates are obtained by, say, non-parametric estimates. The method is then “asymptotically exact” in the weak (and unsurprising) sense of being converging in the number of MCMC iterations. Still, there is a theoretical justification that is not found in previous parallel methods that mixed all resulting samples without accounting for the subsampling. And I also appreciate the point that, in many cases, running MCMC samplers with subsamples produces faster convergence.

In the paper, the division of p into its components is done by partitioning the iid data into m subsets. And taking a power 1/m of the prior in each case. (Which may induce improperness issues.) However, the subdivision is arbitrary and can thus be implemented in other cases than the fairly restrictive iid setting. Because each (subsample)  non-parametric estimate involves T terms, the resulting overall estimate contains Tm terms and the authors suggest using an independent Metropolis-within-Gibbs sampler to handle this complexity. Which is necessary [took me a while to realise this!] for producing a final sample from the (approximate) true posterior distribution. As an aside, I wonder why the bandwidths are all equal across all subsamples, as they should depend on those. And as it would not make much of a difference. It would also be interesting to build a typology of cases where subsampling leads to subposteriors that are close to orthogonal, preventing the implementation of the method.

As it happened, I read this paper on the very day Nial Friel (University College Dublin) gave a seminar at the Big’MC seminar on the convergence of approximations to ergodic transition kernels, based on the recent results of Mitrophanov on the stability of Markov chains, where he introduced the topic by the case of datasets large enough to prevent the computation of the likelihood function.

another vanilla Rao-Blackwellisation

Posted in Statistics, University life with tags , , , , , on September 16, 2013 by xi'an

In the latest issue of Statistics and Computing (2013, Issue 23, pages 577-587), Iliopoulos and Malefaki published a paper that relates to our vanilla Rao-Blackwellisation paper with Randal Douc. The idea is to derive another approximation to the ideal importance sampling weight using the “accepted” Markov chain. (With Randal, we had a Bernoulli factory representation.) The density g(x) of the accepted chain being unknown; it is represented as the expectation under π of the function

\min\left\{q(z|x)/\pi(z),q(x|z)/\pi(x)\right\}

and hence estimated by a self-normalised average based on the whole Markov chain. This means the resulting importance estimate uses twice the output of the algorithm and that it is biased and of order O(n²), thus the same order as our original Rao-Blackwellised estimator (Robert & Casella, 1996)… This also means convergence and CLT are very hard to establish: the main convergence theorem of the paper holds only for finite state spaces, with a surprising smaller asymptotic variance for this self-normalised average than for the ideal importance sampling estimator in the independent Metropolis-Hastings case. (Both are biased by being self-normalised and the paper does not consider the magnitude of those biases.)

Interestingly, the authors also ran a comparison with our parallelised Rao-Blackwellised version (with Pierre Jacob and Murray Smith), but conclude (P.58) at a larger CPU (should be GPU!!) required by the parallelisation, which does not really make sense: when compared with the plain Metropolis-Hastings implementation, run on a single processor, the parallel version only requires an extra random permutation per thread or per processor. I thus suspect a faulty implementation that induces this CPU being linear in the size of the blocks, like maybe only saving one output per block… Also interestingly, the paper re-analyses the Pima Indian probit model Jean-Michel Marin and I (and many others) used as benchmark in several of our papers. As in the most standard examples, the outcome shows a mild reduction in variance when using this estimated importance sampling version. Maybe a comparison with the ideal importance sampler (i.e. the one that does not divide by the sum of the weights since using normalised versions of the target and importance densities) would have helped in the comparison.

Path storage in the particle filter

Posted in Books, Kids, Statistics, Travel, University life with tags , , , , , , on July 24, 2013 by xi'an

IMG_0324In the train to Annecy, I read the recently arXived paper by my former PhD student Pierre Jacob (now at NUS), along with Lawrence Murray (Perth), and Sylvain Rubenthaler (Nice), where they obtain precise degeneracy rates of the regular particle filter applied to hidden Markov models with a compact observation space, precise enough to consider storing the entire paths at a linear occupancy rate. Interestingly, the distance to the most common ancestor is of order N log N, if N is the number of particles. And the number of nodes is O(N log N) as well. This means indeed that the whole paths can be stored, which offers a lot of potential in terms of Rao-Blackwellisation and parallelisation. I was first bemused by a silly misunderstanding about the purpose of the algorithm: it is directed at inference at the current time index, not over the whole past and not over the parameters of the model for, else how could we consider the algorithm has converged when it degenerates to a single path at some finite horizon the past? Pierre has also written a further comment of the paper on Statistfaction.

English trip (1)

Posted in Statistics, Travel, University life with tags , , , , , , , , , , , , , on January 25, 2012 by xi'an

Today, I am attending a workshop on the use of graphics processing units in Statistics in Warwick, supported by CRiSM, presenting our recent works with Randal Douc, Pierre Jacob and Murray Smith. (I will use the same slides as in Telecom two months ago, hopefully avoiding the loss of integral and summation signs this time!) Pierre Jacob will talk about Wang-Landau.

Then, tomorrow, I am off to Cambridge to talk about ABC and model choice on Friday afternoon. (Presumably using the same slides as in Provo.)

The (1) in the title is in prevision of a second trip to Oxford next month and another one to Bristol two months after! (The trip to Edinburgh does not count of course, since it is in Scotland!)