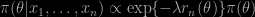Archive for Pima Indians

X divergence for approximate inference

Posted in Statistics with tags , , , , , , , on March 14, 2017 by xi'an

Dieng et al. arXived this morning a new version of their paper on using the Χ divergence for variational inference. The Χ divergence essentially is the expectation of the squared ratio of the target distribution over the approximation, under the approximation. It is somewhat related to Expectation Propagation (EP), which aims at the Kullback-Leibler divergence between the target distribution and the approximation, under the target. And to variational Bayes, which is the same thing just the opposite way! The authors also point a link to our [adaptive] population Monte Carlo paper of 2008. (I wonder at a possible version through Wasserstein distance.)

Some of the arguments in favour of this new version of variational Bayes approximations is that (a) the support of the approximation over-estimates the posterior support; (b) it produces over-dispersed versions; (c) it relates to a well-defined and global objective function; (d) it allows for a sandwich inequality on the model evidence; (e) the function of the [approximation] parameter to be minimised is under the approximation, rather than under the target. The latest allows for a gradient-based optimisation. While one of the applications is on a Bayesian probit model applied to the Pima Indian women dataset [and will thus make James and Nicolas cringe!], the experimental assessment shows lower error rates for this and other benchmarks. Which in my opinion does not tell so much about the original Bayesian approach.

read paper [in Bristol]

Posted in Books, pictures, Statistics, Travel, University life with tags , , , , , , , , , , , , , , on January 29, 2016 by xi'an

Clifton & Durdham Downs, Bristol, Sept. 25, 2012I went to give a seminar in Bristol last Friday and I chose to present the testing with mixture paper. As we are busy working on the revision, I was eagerly looking for comments and criticisms that could strengthen this new version. As it happened, the (Bristol) Bayesian Cake (Reading) Club had chosen our paper for discussion, two weeks in a row!, hence the title!, and I got invited to join the group the morning prior to the seminar! This was, of course, most enjoyable and relaxed, including an home-made cake!, but also quite helpful in assessing our arguments in the paper. One point of contention or at least of discussion was the common parametrisation between the components of the mixture. Although all parametrisations are equivalent from a single component point of view, I can [almost] see why using a mixture with the same parameter value on all components may impose some unsuspected constraint on that parameter. Even when the parameter is the same moment for both components. This still sounds like a minor counterpoint in that the weight should converge to either zero or one and hence eventually favour the posterior on the parameter corresponding to the “true” model.

Another point that was raised during the discussion is the behaviour of the method under misspecification or for an M-open framework: when neither model is correct does the weight still converge to the boundary associated with the closest model (as I believe) or does a convexity argument produce a non-zero weight as it limit (as hinted by one example in the paper)? I had thought very little about this and hence had just as little to argue though as this does not sound to me like the primary reason for conducting tests. Especially in a Bayesian framework. If one is uncertain about both models to be compared, one should have an alternative at the ready! Or use a non-parametric version, which is a direction we need to explore deeper before deciding it is coherent and convergent!

A third point of discussion was my argument that mixtures allow us to rely on the same parameter and hence the same prior, whether proper or not, while Bayes factors are less clearly open to this interpretation. This was not uniformly accepted!

Thinking afresh about this approach also led me to broaden my perspective on the use of the posterior distribution of the weight(s) α: while previously I had taken those weights mostly as a proxy to the posterior probabilities, to be calibrated by pseudo-data experiments, as for instance in Figure 9, I now perceive them primarily as the portion of the data in agreement with the corresponding model [or hypothesis] and more importantly as a solution for staying away from a Neyman-Pearson-like decision. Or error evaluation. Usually, when asked about the interpretation of the output, my answer is to compare the behaviour of the posterior on the weight(s) with a posterior associated with a sample from each model. Which does sound somewhat similar to posterior predictives if the samples are simulated from the associated predictives. But the issue was not raised during the visit to Bristol, which possibly reflects on how unfrequentist the audience was [the Statistics group is], as it apparently accepted with no further ado the use of a posterior distribution as a soft assessment of the comparative fits of the different models. If not necessarily agreeing the need of conducting hypothesis testing (especially in the case of the Pima Indian dataset!).

approximating evidence with missing data

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , on December 23, 2015 by xi'an

University of Warwick, May 31 2010Panayiota Touloupou (Warwick), Naif Alzahrani, Peter Neal, Simon Spencer (Warwick) and Trevelyan McKinley arXived a paper yesterday on Model comparison with missing data using MCMC and importance sampling, where they proposed an importance sampling strategy based on an early MCMC run to approximate the marginal likelihood a.k.a. the evidence. Another instance of estimating a constant. It is thus similar to our Frontier paper with Jean-Michel, as well as to the recent Pima Indian survey of James and Nicolas. The authors give the difficulty to calibrate reversible jump MCMC as the starting point to their research. The importance sampler they use is the natural choice of a Gaussian or t distribution centred at some estimate of θ and with covariance matrix associated with Fisher’s information. Or derived from the warmup MCMC run. The comparison between the different approximations to the evidence are done first over longitudinal epidemiological models. Involving 11 parameters in the example processed therein. The competitors to the 9 versions of importance samplers investigated in the paper are the raw harmonic mean [rather than our HPD truncated version], Chib’s, path sampling and RJMCMC [which does not make much sense when comparing two models]. But neither bridge sampling, nor nested sampling. Without any surprise (!) harmonic means do not converge to the right value, but more surprisingly Chib’s method happens to be less accurate than most importance solutions studied therein. It may be due to the fact that Chib’s approximation requires three MCMC runs and hence is quite costly. The fact that the mixture (or defensive) importance sampling [with 5% weight on the prior] did best begs for a comparison with bridge sampling, no? The difficulty with such study is obviously that the results only apply in the setting of the simulation, hence that e.g. another mixture importance sampler or Chib’s solution would behave differently in another model. In particular, it is hard to judge of the impact of the dimensions of the parameter and of the missing data.

the problem of assessing statistical methods

Posted in Books, pictures, Statistics, University life with tags , , , , , , on November 4, 2015 by xi'an

A new arXival today by Abigail Arnold and Jason Loeppky that discusses how simulations studies are and should be conducted when assessing statistical methods.

“Obviously there is no one model that will universally outperform the rest. Recognizing the “No Free Lunch” theorem, the logical question to ask is whether one model will perform best over a given class of problems. Again, we feel that the answer to this question is of course no. But we do feel that there are certain methods that will have a better chance than other methods.”

I find the assumptions or prerequisites of the paper arguable [in the sense of 2. open to disagreement; not obviously correct]—not even mentioning the switch from models to methods in the above—in that I will not be convinced that a method outperforms another method by simply looking at a series of simulation experiments. (Which is why I find some machine learning papers unconvincing, when they introduce a new methodology and run it through a couple benchmarks.) This also reminds me of Samaniego’s Comparison of the Bayesian and frequentist approaches, which requires a secondary prior to run the comparison. (And hence is inconclusive.)

“The papers above typically show the results as a series of side-by-side boxplots (…) for each method, with one plot for each test function and sample size. Conclusions are then drawn from looking at a handful of boxplots which often look very cluttered and usually do not provide clear evidence as to the best method(s). Alternatively, the results will be summarized in a table of average performance (…) These tables are usually overwhelming to look at and interpretations are incredibly inefficient.”

Agreed boxplots are terrible (my friend Jean-Michel is forever arguing against them!). Tables are worse. But why don’t we question RMSE as well? This is most often a very reductive way of comparing methods. I also agree with the point that the design of the simulation studies is almost always overlooked and induces a false sense of precision, while failing to cover a wide enough range of cases. However, and once more, I question the prerequisites for comparing methods through simulations for the purpose of ranking those methods. (Which is not the perspective adopted by James and Nicolas when criticising the use of the Pima Indian dataset.)

“The ECDF allows for quick assessments of methods over a large array of problems to get an overall view while of course not precluding comparisons on individual functions (…) We hope that readers of this paper agree with our opinions and strongly encourage everyone to rely on the ECDF, at least as a starting point, to display relevant statistical information from simulations.”

Drawing a comparison with the benchmarking of optimisation methods, the authors suggest to rank statistical methods via the empirical cdf of their performances or accuracy across (benchmark) problems. Arguing that “significant benefit is gained by [this] collapsing”. I am quite sceptical [as often] of the argument, first because using a (e)cdf means the comparison is unidimensional, second because I see no reason why two cdfs should be easily comparable, third because the collapsing over several problems only operates when the errors for those different problems do not overlap.

PAC-Bayesians

Posted in Books, Kids, pictures, Statistics, Travel, University life with tags , , , , , , , , , on September 22, 2015 by xi'an

Yesterday, I took part in the thesis defence of James Ridgway [soon to move to the University of Bristol[ at Université Paris-Dauphine. While I have already commented on his joint paper with Nicolas on the Pima Indians, I had not read in any depth another paper in the thesis, “On the properties of variational approximations of Gibbs posteriors” written jointly with Pierre Alquier and Nicolas Chopin.

PAC stands for probably approximately correct and starts with an empirical form of posterior, called the Gibbs posterior, where the log-likelihood is replaced with an empirical error

\pi(\theta|x_1,\ldots,x_n) \propto \exp\{-\lambda r_n(\theta)\}\pi(\theta)

that is rescaled by a factor λ. Factor that is called the learning rate, to be optimised as the (Kullback) closest  approximation to the true unknown distribution, by Peter Grünwald (2012) in his SafeBayes approach. In the paper of James, Pierre and Nicolas, there is no visible Bayesian perspective, since the pseudo-posterior is used to define a randomised estimator that achieves optimal oracle bounds. When λ is of order n. The purpose of the paper is rather to produce an efficient approximation to the Gibbs posterior, by using variational Bayes techniques. And to derive point estimators. With the added appeal that the approximation also achieves the oracle bounds. (Surprisingly, the authors do not leave the Pima Indians alone as they use this benchmark for a ranking model.) Since there is no discussion on the choice of the learning rate λ, as opposed to Bissiri et al. (2013) I discussed around Bayes.250, I have difficulties perceiving the possible impact of this representation on Bayesian analysis. Except maybe as an ABC device, as suggested by Christophe Andrieu.