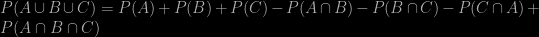Archive for PNAS

Confidence (bis repetita placent?)

Posted in Statistics, University life with tags , , , on June 23, 2011 by xi'an

Due to the simultaneous presence of Jean-Michel Marin and Natesh Pillai in Paris, we were able to write within a few days a new revision of our lack of confidence in ABC model choice paper, currently submitted to PNAS. Following my earlier comments on the reviews, we now consider that indeed different statistics are needed for model choice in that estimation statistics are generally unable to distinguish between the models. The collection of “other statistics” being rather wide means we are still at a loss about which statistics to pick in practive, but the principle is worth stressing.

Here is an illustration of the difficulty to separate (by ABC) between models in a setting suggested by one referee, i.e. when testing a location normal  distribution versus a location Laplace distribution (both with variance 1).  The (frequentist) distribution of the ABC estimate of the posterior probability of the normal model is centred at the same position when simulating data from the normal and from the Laplace distributions and when using a Euclidean distance involving the mean, the median and the variance as summary statistics.

The new version has now been (re)resubmitted and re-arXived. The changes are toward a more cautionary tone, stating that all we know about the ABC approximation to the Bayes factor is that… we do not know whether or not it constitutes a converging approximation to the Bayes factor (mostly not) or to the Bayes decision (presumably yes with “enough” statistics). We are currently working in exploring that direction…

Still not confident…

Posted in Statistics, University life with tags , , , , , on June 14, 2011 by xi'an

About 45 days after submitting our revised version of lack of confidence in ABC model choice to PNAS, we have received the reviews and they still ask for more clarity in our conclusions. In particular, one referee does not buy the distinction between ABC point (and confidence) estimation and ABC model choice, namely that ABC may equally go wrong in the former case when using a poor selection of summary statistics.  This is correct, even though a stepwise ABC estimation à la Marjoram could bring some measure of confidence in the set of summary statistics used for estimation. This referee’s conclusion is then that “the statistics we use for model checking must be different from those used in inference“. This is sound when considering the simple normal example we include in the paper, however in realistic situations, there is no sufficiency to aim at and therefore it is impossible to know how good or how different those summary statistics are. The second referee maintains her or his earlier position that there is nothing wrong with ABC when using a sufficiently large collection of summary statistics. The proof is given in our paper by the fact that for the larger dataset  we “get statistically reliable results using ABC for model choice (without using sufficient statistics)”. First, this is only one experiment, with no reason to extrapolate to other philogenetic trees and even less to models outside population genetics. Second, we only argue that the ABC Bayes factor does not have any reason to converge to the true Bayes factor. It may well be a consistent quantity for model selection, but theoretical arguments are currently missing (although an extension of the perspective adopted in Fearnhead and Prangle and in Dean et al., namely to see ABC as an inference method per se rather than an approximation to a Bayesian inaccessible methodology, could be considered here as well). In conclusion, this means that we have to go for yet another run of revision that will tone even further down our conclusion and presumably soften the distinction between point estimation and hypothesis testing… A good thing Natesh starts his visit to Paris today!

Lack of confidence [revised]

Posted in R, Statistics, University life with tags , , , , , , , on April 22, 2011 by xi'an

Following the comments on our earlier submission to PNAS, we have written (and re-arXived) a revised version where we try to spell out (better) the distinction between ABC point (and confidence) estimation and ABC model choice, namely that the problem was at another level for Bayesian model choice (using posterior probabilities). When doing point estimation with in-sufficient summary statistics, the information content is poorer, but unless one uses very degraded summary statistics, inference is converging. We completely agree with the reviewers that the posterior distribution is different from the true posterior in this case but, at least, gathering more observations brings more information about the parameter (and convergence when the number of observations goes to infinity). For model choice, this is not guaranteed if we use summary statistics that are not inter-model sufficient, as shown by the Poisson and normal examples. Furthermore, except for very specific cases such as Gibbs random fields, it is almost always impossible to derive inter-model sufficient statistics, beyond the raw sample. This is why we consider there is a fundamental difference between point estimation and model choice.

Following the request from a referee, we also ran a more extensive simulation experiment for comparing two scenarios with 3 populations, 100 diploid individuals per population, and 50 loci/markers. However, the results are somehow less conclusive, in the sense that, since we use 50 loci, the data is much more informative about the model and therefore both the importance sampling and the ABC approximations provide a value of the posterior probability approximation that is close to one, hence both concluding with the validation of the true model. Because both approximations are very close to one, it is difficult to assess the worth of the ABC approximation per se, i.e. in numerical terms. (The fact that the statistical conclusion is the same for both approaches is of course satisfying from an inferential perspective, but is an altogether separate issue from our argument about the possible lack of convergence of the ABC Bayes factor approximation to the true Bayes factor.) Furthermore, this experiment may be beyond the manageable/reasonable in the sense that the importance sampling approximation cannot be taken for granted, nor can it be checked empirically. Indeed, with 50 markers and 100 individuals, the product likelihood suffers from an enormous variability that 100,000 particles and 100 trees per locus have trouble to address (despite a huge computing cost of more than 12 days on a powerful cluster).

Incidentally, I had a problem with natbib, when using the pnas style:

!Package natbib Error: Bibliography not compatible with author-year citations.
Press <return> to continue in numerical citation style.
See the natbib package documentation for explanation.

but it vanisheds with the options

\usepackage[round,numbers]{natbib}

which is an easy fix.

Lack of confidence is back

Posted in Statistics, University life with tags , , , , on April 4, 2011 by xi'an

While in Bristol, I received the very good news that our ABC model choice submission to PNAS had passed the first round, namely, the manuscript was not rejected but instead the editor asks for a revision clarifying our message and the difference with the Bayesian Analysis paper. This revision should thus be manageable, even though the most negative reviewer considers that ABC model choice works rather when using summary statistics that are informative for choosing between the models, a point that sounds rather tautological to me., hence difficult to answer. It is indeed always possible to come up with summary statistics that make the ABC Bayes factor close to the genuine Bayes factor; however this requires a huge computing effort in order to validate the choice by cross-validation. Anyway, I have rather good hopes the paper could eventually be accepted in PNAS, which is obviously a quite exciting prospect! (Thanks to Michael Stumpf for pointing out the missing sentence!)

Incoherent phyleogeographic inference [reply]

Posted in Statistics, University life with tags , , , , , , , , , on September 29, 2010 by xi'an

“Logical overlap is the norm for the complex models analyzed with ABC, so many ABC posterior model probabilities published to date are wrong.” Alan R. Templeton, PNAS, doi:10.1073/pnas.1009012107

Our letter in PNAS about Templeton’s surprising diatribe on Bayesian inference is now appeared in the early edition, along with Templeton’s reply. This reply is unfortunately missing any novelty element compared with the original paper. First, he maintains that the critcism is about ABC (which is, in case you do not know, a computational technique and not a specific statistical methodology!). Second, he insists on the inappropriate Venn diagram analogy by reproducing the basic identity

P(A\cup B\cup C) = P(A)+P(B)+P(C)-P(A\cap B)-P(B\cap C)-P(C\cap A)+P(A\cap B\cap C)

(presumably in case we had lost sight of it!) to argue that using instead

P(A)+P(B)+P(C)

is incoherent (hence rejecting Bayes factors, Bayesian model averaging and so on). I am not particularly surprised by this immutable stance, but it means that there is little point in debate when starting from such positions… Our main goal in publishing this letter was actually to stress that the earlier tribune had no statistical ground and I think we achieved this goal.