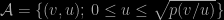Archive for ratio of uniform algorithm

ratio-of-uniforms [#3]

Posted in Books, pictures, R, Statistics with tags , , , , , on November 4, 2016 by xi'an

Being still puzzled (!) by the ratio-of-uniform approach, mostly failing to catch its relevance for either standard distributions in a era when computing a cosine or an exponential is negligible, or non-standard distributions for which computing bounds and boundaries is out-of-reach, I kept searching for solutions that would include unbounded densities and still produce compact boxes, as this seems essential for accept-reject simulation if not for slice sampling. And after exploring some dead-ends (in tune with running in Venezia!), I came upon the case of the generalised logistic transform
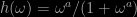
h(\omega)=\omega^a/(1+\omega^a)

which ensures that the [ratio-of-almost-uniform] set I defined in my slides last week
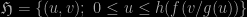
\mathfrak{H}=\left\{(u,v);\ 0\le u\le h(f(v/g(u))\right\}

is bounded in u. Since the transform g is the derivative of the inverse of h (!),
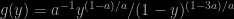
g(y)=a^{-1}y^{(1-a)/a}/(1-y)^{(1-3a)/a}

the parametrisation of the boundary of H is

u(x)=f(x)^a/(1+f(x)^a)\ v(x)=a^{-1}xf(x)^{(a-1)/a}(1+f(x)^a)^2

which means it remains bounded if (a) a≤1 [to ensure boundedness at infinity] and (b) the limit of v(x) at zero [where I assume the asymptote stands] is bounded. Meaning
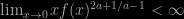
\lim_{x\to 0} xf(x)^{2a+1/a-1}<\infty

Working a wee bit more on the problem led me to realise that resorting to an arbitrary cdf Φ instead of the logistic cdf could solve the problem for most distributions, including all Gammas! Indeed, the boundary of H is now
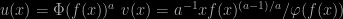
u(x)=\Phi(f(x))^a\ v(x)=a^{-1}xf(x)^{(a-1)/a}/\varphi(f(x))

which means it remains bounded if φ has very heavy tails, like 1/x². To handle the explosion when x=0. And an asymptote itself at zero, to handle the limit at infinity when f(x) goes to zero.

ratio-of-uniforms [#2]

Posted in Books, R, Statistics with tags , , , , , , on October 31, 2016 by xi'an

Following my earlier post on Kinderman’s and Monahan’s (1977) ratio-of-uniform method, I must confess I remain quite puzzled by the approach. Or rather by its consequences. When looking at the set A of (u,v)’s in R⁺×X such that 0≤u²≤ƒ(v/u), as discussed in the previous post, it can be represented by its parameterised boundary

u(x)=√ƒ(x),v(x)=x√ƒ(x)    x in X

Similarly, since the simulation from ƒ(v/u) can also be derived [check Luc Devroye’s Non-uniform random variate generation in the exercise section 7.3] from a uniform on the set B of (u,v)’s in R⁺×X such that 0≤u≤ƒ(v+u), on the set C of (u,v)’s in R⁺×X such that 0≤u³≤ƒ(v/√u)², or on the set D of (u,v)’s in R⁺×X such that 0≤u²≤ƒ(v/u), which is actually exactly the same as A [and presumably many other versions!, for which I would like to guess the generic rule of construction], there are many sets on which one can consider running simulations. And one to pick for optimality?! Here are the three sets for a mixture of two normal densities:

For instance, assuming slice sampling is feasible on every one of those three sets, which one is the most efficient? While I have no clear answer to this question, I found on Sunday night that a generic family of transforms is indexed by a differentiable  monotone function h over the positive half-line, with the uniform distribution being taken over the set

H={(u,v);0≤u≤h(f(v/g(u))}

when the primitive G of g is the inverse of h, i.e., G(h(x))=x. [Here are the slides I gave at the Warwick reading group on Devroye’s book last week:]

ratio-of-uniforms

Posted in Books, pictures, R, Statistics with tags , , , , on October 24, 2016 by xi'an

One approach to random number generation that had always intrigued me is Kinderman and Monahan’s (1977) ratio-of-uniform method. The method is based on the result that the uniform distribution on the set A of (u,v)’s in R⁺xX such that

0≤u²≤ƒ(v/u)

induces the distribution with density proportional to ƒ on V/U. Hence the name. The proof is straightforward and the result can be seen as a consequence of the fundamental lemma of simulation, namely that simulating from the uniform distribution on the set B of (w,x)’s in R⁺xX such that

0≤w≤ƒ(x)

induces the marginal distribution with density proportional to ƒ on X. There is no mathematical issue with this result, but I have difficulties with picturing the construction of efficient random number generators based on this principle.

ratouniI thus took the opportunity of the second season of [the Warwick reading group on] Non-uniform random variate generation to look anew at this approach. (Note that the book is freely available on Luc Devroye’s website.) The first thing I considered is the shape of the set A. Which has nothing intuitive about it! Luc then mentions (p.195) that the boundary of A is given by

u(x)=√ƒ(x),v(x)=x√ƒ(x)

which then leads to bounding both ƒ and x→x²ƒ(x) to create a box around A and an accept-reject strategy, but I have trouble with this result without making further assumptions about ƒ… Using a two component normal mixture as a benchmark, I found bounds on u(.) and v(.) and simulated a large number of points within the box to end up with the above graph that indeed the accepted (u,v)’s were within this boundary. And the same holds with a more ambitious mixture:

bagpiiipe

generalised ratio of uniforms

Posted in R, Statistics, University life with tags , , , on May 15, 2012 by xi'an

A recent arXiv posting of the paper “On the Generalized Ratio of Uniforms as a Combination of Transformed Rejection and Extended Inverse of Density Sampling” by Martino, Luengo, and Míguez from Madrid rekindled my interest in this rather peculiar simulation method. The ratio of uniforms samples uniformly on the subgraph

\mathcal{A}=\{(v,u);\,0\le u\le\sqrt{p(v/u)}\}

to produce simulations from p as the ratio v/u. The proof is straightforward first year calculus but I do not find the method intuitive as, say, accept/reject…. The paper gives a very detailed background on those methods, as well as on the “inverse of density method”, which is like looking at the uniform simulation over the subgraph, but with both axes inverted (slice sampling is the same on both). (A minor point of contention or at least misunderstanding: when using the inverse of density method, the authors claim that using the unormalised and the normalised versions of the target leads to the same outcome. While it is true for the direct method, I have trouble seeing the equivalent in the inverse case…) The paper also stresses that the optimal case for accept-reject is when the target is bounded because the uniform can then be used as a proposal. I agree this is a simpler solution but fail to see any optimality in the matter. The authors then study ways of transforming unbounded subgraphs into bounded domains (i.e. bounded pdfs and supports). This imposes conditions on the transform f, which must have finite limits for p(x)/f'(x) or p-1(x)/f'(x) at the boundaries. (An optimal choice is when f is the cdf of p, since then the transform is uniform.)

The remainder (and more innovative) part of the paper is less clear in that I do not get a generic feeling on what it is about! The generalisation of the above is to consider uniform sampling from

\mathcal{A}_g=\big\{(v,u);\,0\le u\le g^{-1}\{c p[v/g'(u)]\}\big\}

for a generic increasing function g such that g(0)=0. And c a positive constant. (Any positive constant?!) But this is from a 1991 paper by Jon Wakefield, Alan Gelfand, and Adrian Smith. The extension is thus in finding g such that the above region is bounded and can be explored by uniform sampling over a box.. And in noticing that “the generalized Ratio-of-Uniform method is a combination of the transformed rejection method applied to the inverse density with the extended inverse-of-density method” (p.27).

I wonder at the applicability of the approach for costly target functions p. And at the extension to larger dimensions. And wish I had more time (or more graduate students) to look at possible adaptive constructions of the transform g. An interesting and fruitful read, nonetheless!