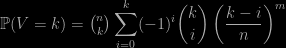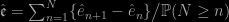Archive for Russian roulette

a closed-form but intractable birthday

Posted in Books, Kids, pictures, Statistics with tags , , , , , on November 7, 2016 by xi'an

An interesting [at least for me!] question found on X Validated yesterday, namely how to simulate efficiently from the generalised birthday problem (or paradox) distribution, which provides the probability of finding exactly k different birthday dates as

\mathbb{P}(V = k) = \binom{n}{k}\displaystyle\sum_{i=0}^k (-1)^i \binom{k}{i}  \left(\frac{k-i}{n}\right)^m

where m is the number of individuals with a random birthday and n the number of days (e.g., n=365). The paradox with this closed-form formula (found by the inclusion-exclusion rule) is that it is too unstable to use per se. While it is always possible to run m draws from a uniform over {1,…,n} and count the number of different values, e.g.,

[sourcecode language=”r”]
x=length(unique(sample(1:n,m,rep=TRUE)))
[/sourcecode]

this takes much more time than using the exact distribution, if available:

[sourcecode language=”r”]
sample(1:m,1e6,rep=TRUE,prob=eff[-1])
[/sourcecode]

I played a little bit with the notion of using an unbiased estimator of the said probability, but the alternating series means that the unbiased estimator may end up being negative, which is an issue met in recent related papers like the famous Russian Roulette.

exact, unbiased, what else?!

Posted in Books, Statistics, University life with tags , , , , , , , , on April 13, 2016 by xi'an

Last week, Matias Quiroz, Mattias Villani, and Robert Kohn arXived a paper on exact subsampling MCMC, a paper that contributes to the current literature on approximating MCMC samplers for large datasets, in connection with an earlier paper of Quiroz et al. discussed here last week.

quirozetal.The “exact” in the title is to be understood in the Russian roulette sense. By using Rhee and Glynn debiaising device, the authors achieve an unbiased estimator of the likelihood as in Bardenet et al. (2015). The central tool for the derivation of an unbiased and positive estimator is to find a control variate for each component of the log likelihood that is good enough for the difference between the component and the control to be lower bounded. By the constant a in the screen capture above. When the individual terms d in the product are iid unbiased estimates of the log likelihood difference. And q is the sum of the control variates. Or maybe more accurately of the cheap substitutes to the exact log likelihood components. Thus still of complexity O(n), which makes the application to tall data more difficult to contemplate.

The $64 question is obviously how to produce cheap and efficient control variates that kill the curse of the tall data. (It still irks to resort to this term of control variate, really!) Section 3.2 in the paper suggests clustering the data and building an approximation for each cluster, which seems to imply manipulating the whole dataset at this early stage. At a cost of O(Knd). Furthermore, because finding a correct lower bound a is close to impossible in practice, the authors use a “soft lower bound”, meaning that it is only an approximation and thus that (3.4) above can get negative from time to time, which cancels the validation of the method as a pseudo-marginal approach. The resolution of this difficulty is to resort to the same proxy as in the Russian roulette paper, replacing the unbiased estimator with its absolute value, an answer I already discussed for the Russian roulette paper. An additional step is proposed by Quiroz et al., namely correlating the random numbers between numerator and denominator in their final importance sampling estimator, via a Gaussian copula as in Deligiannidis et al.

This paper made me wonder (idly wonder, mind!) anew how to get rid of the vexing unbiasedness requirement. From a statistical and especially from a Bayesian perspective, unbiasedness is a second order property that cannot be achieved for most transforms of the parameter θ. And that does not keep under reparameterisation. It is thus vexing and perplexing that unbiased is so central to the validation of our Monte Carlo technique and that any divergence from this canon leaves us wandering blindly with no guarantee of ever reaching the target of the simulation experiment…

more e’s [and R’s]

Posted in Kids, pictures, R, Statistics with tags , , , , , , , on February 22, 2016 by xi'an

estimeAlex Thiéry suggested debiasing the biased estimate of e by Rhee and Glynn truncated series method, so I tried the method to see how much of an improvement (if any!) this would bring. I first attempted to naïvely implement the raw formula of Rhee and Glynn

\hat{\mathfrak{e}} = \sum_{n=1}^N \{\hat{e}_{n+1}-\hat{e}_n\}\big/\mathbb{P}(N\ge n)

with a (large) Poisson distribution on the stopping rule N, but this took ages. I then realised that the index n did not have to be absolute, i.e. to start at n=1 and proceed snailwise one integer at a time: the formula remains equally valid after a change of time, i.e. n=can start at an arbitrary value and proceeds by steps of arbitrary size, which obviously speeds things up! Continue reading →

light and widely applicable MCMC: approximate Bayesian inference for large datasets

Posted in Books, Statistics, University life, Wines with tags , , , , , , , , , , on March 24, 2015 by xi'an

Florian Maire (whose thesis was discussed in this post), Nial Friel, and Pierre Alquier (all in Dublin at some point) have arXived today a paper with the above title, aimed at quickly analysing large datasets. As reviewed in the early pages of the paper, this proposal follows a growing number of techniques advanced in the past years, like pseudo-marginals, Russian roulette, unbiased likelihood estimators. firefly Monte Carlo, adaptive subsampling, sub-likelihoods, telescoping debiased likelihood version, and even our very own delayed acceptance algorithm. (Which is incorrectly described as restricted to iid data, by the way!)

The lightweight approach is based on an ABC idea of working through a summary statistic that plays the role of a pseudo-sufficient statistic. The main theoretical result in the paper is indeed that, when subsampling in an exponential family, subsamples preserving the sufficient statistics (modulo a rescaling) are optimal in terms of distance to the true posterior. Subsamples are thus weighted in terms of the (transformed) difference between the full data statistic and the subsample statistic, assuming they are both normalised to be comparable. I am quite (positively) intrigued by this idea in that it allows to somewhat compare inference based on two different samples. The weights of the subsets are then used in a pseudo-posterior that treats the subset as an auxiliary variable (and the weight as a substitute to the “missing” likelihood). This may sound a wee bit convoluted (!) but the algorithm description is not yet complete: simulating jointly from this pseudo-target is impossible because of the huge number of possible subsets. The authors thus suggest to run an MCMC scheme targeting this joint distribution, with a proposed move on the set of subsets and a proposed move on the parameter set conditional on whether or not the proposed subset has been accepted.

From an ABC perspective, the difficulty in calibrating the tolerance ε sounds more accute than usual, as the size of the subset comes as an additional computing parameter. Bootstrapping options seem impossible to implement in a large size setting.

An MCMC issue with this proposal is that designing the move across the subset space is both paramount for its convergence properties and lacking in geometric intuition. Indeed, two subsets with similar summary statistics may be very far apart… Funny enough, in the representation of the joint Markov chain, the parameter subchain is secondary if crucial to avoid intractable normalising constants. It is also unclear for me from reading the paper maybe too quickly whether or not the separate moves when switching and when not switching subsets retain the proper balance condition for the pseudo-joint to still be the stationary distribution. The stationarity for the subset Markov chain is straightforward by design, but it is not so for the parameter. In case of switched subset, simulating from the true full conditional given the subset would work, but not simulated  by a fixed number L of MCMC steps.

The lightweight technology therein shows its muscles on an handwritten digit recognition example where it beats regular MCMC by a factor of 10 to 20, using only 100 datapoints instead of the 10⁴ original datapoints. While very nice and realistic, this example may be misleading in that 100 digit realisations may be enough to find a tolerable approximation to the true MAP. I was also intrigued by the processing of the probit example, until I realised the authors had integrated the covariate out and inferred about the mean of that covariate, which means it is not a genuine probit model.

Dan Simpson’s seminar at CREST

Posted in Kids, Mountains, Statistics, Travel, University life with tags , , , , , , , , , on April 18, 2014 by xi'an

Daniel Simpson gave a seminar at CREST yesterday on his recently arXived paper, “Penalising model component complexity: A principled, practical  approach to constructing priors” written with Thiago Martins, Andrea Riebler, Håvard Rue, and Sigrunn Sørbye. Paper that he should also have given in Banff last month had he not lost his passport in København airport…  I have already commented at length on this exciting paper, hopefully to become a discussion paper in a top journal!, so I am just pointing out two things that came to my mind during the energetic talk delivered by Dan to our group. The first thing is that those penalised complexity (PC) priors of theirs rely on some choices in the ordering of the relevance, complexity, nuisance level, &tc. of the parameters, just like reference priors. While Dan already wrote a paper on Russian roulette, there is also a Russian doll principle at work behind (or within) PC priors. Each shell of the Russian doll corresponds to a further level of complexity whose order need be decided by the modeller… Not very realistic in a hierarchical model with several types of parameters having only local meaning.

My second point is that the construction of those “politically correct” (PC) priors reflects another Russian doll structure, namely one of embedded models, hence would and should lead to a natural multiple testing methodology. Except that Dan rejected this notion during his talk, by being opposed to testing per se. (A good topic for one of my summer projects, if nothing more, then!)