Archive for StackExchange

testing via credible sets

Posted in Statistics, University life with tags , , , , , , , , , , , on October 8, 2012 by xi'an

Måns Thulin released today an arXiv document on some decision-theoretic justifications for [running] Bayesian hypothesis testing through credible sets. His main point is that using the unnatural prior setting mass on a point-null hypothesis can be avoided by rejecting the null when the point-null value of the parameter does not belong to the credible interval and that this decision procedure can be validated through the use of special loss functions. While I stress to my students that point-null hypotheses are very unnatural and should be avoided at all cost, and also that constructing a confidence interval is not the same as designing a test—the former assess the precision in the estimation, while the later opposes two different and even incompatible models—, let us consider Måns’ arguments for their own sake.

The idea of the paper is that there exist loss functions for testing point-null hypotheses that lead to HPD, symmetric and one-sided intervals as acceptance regions, depending on the loss func. This was already found in Pereira & Stern (1999). The issue with these loss functions is that they involve the corresponding credible sets in their definition, hence are somehow tautological. For instance, when considering the HPD set and T(x) as the largest HPD set not containing the point-null value of the parameter, the corresponding loss function is
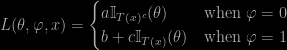
L(\theta,\varphi,x) = \begin{cases}a\mathbb{I}_{T(x)^c}(\theta) &\text{when }\varphi=0\\ b+c\mathbb{I}_{T(x)}(\theta) &\text{when }\varphi=1\end{cases}

parameterised by a,b,c. And depending on the HPD region.

Måns then introduces new loss functions that do not depend on x and still lead to either the symmetric or the one-sided credible intervals.as acceptance regions. However, one test actually has two different alternatives (Theorem 2), which makes it essentially a composition of two one-sided tests, while the other test returns the result to a one-sided test (Theorem 3), so even at this face-value level, I do not find the result that convincing. (For the one-sided test, George Casella and Roger Berger (1986) established links between Bayesian posterior probabilities and frequentist p-values.) Both Theorem 3 and the last result of the paper (Theorem 4) use a generic and set-free observation-free loss function (related to eqn. (5.2.1) in my book!, as quoted by the paper) but (and this is a big but) they only hold for prior distributions setting (prior) mass on both the null and the alternative. Otherwise, the solution is to always reject the hypothesis with the zero probability… This is actually an interesting argument on the why-are-credible-sets-unsuitable-for-testing debate, as it cannot bypass the introduction of a prior mass on Θ0!

Overall, I furthermore consider that a decision-theoretic approach to testing should encompass future steps rather than focussing on the reply to the (admittedly dumb) question is θ zero? Therefore, it must have both plan A and plan B at the ready, which means preparing (and using!) prior distributions under both hypotheses. Even on point-null hypotheses.

Now, after I wrote the above, I came upon a Stack Exchange page initiated by Måns last July. This is presumably not the first time a paper stems from Stack Exchange, but this is a fairly interesting outcome: thanks to the debate on his question, Måns managed to get a coherent manuscript written. Great! (In a sense, this reminded me of the polymath experiments of Terry Tao, Timothy Gower and others. Meaning that maybe most contributors could have become coauthors to the paper!)

estimating a constant

Posted in Books, Statistics with tags , , , , , , , , , on October 3, 2012 by xi'an

Paulo (a.k.a., Zen) posted a comment in StackExchange on Larry Wasserman‘s paradox about Bayesians and likelihoodists (or likelihood-wallahs, to quote Basu!) being unable to solve the problem of estimating the normalising constant c of the sample density, f, known up to a constant

f(x) = c g(x)

(Example 11.10, page 188, of All of Statistics)

My own comment is that, with all due respect to Larry!, I do not see much appeal in this example, esp. as a potential criticism of Bayesians and likelihood-wallahs…. The constant c is known, being equal to

1/\int_\mathcal{X} g(x)\text{d}x

If c is the only “unknown” in the picture, given a sample x1,…,xn, then there is no statistical issue whatsoever about the “problem” and I do not agree with the postulate that there exist estimators of c. Nor priors on c (other than the Dirac mass on the above value). This is not in the least a statistical problem but rather a numerical issue.That the sample x1,…,xn can be (re)used through a (frequentist) density estimate to provide a numerical approximation of c

\hat c = \hat f(x_0) \big/ g(x_0)

is a mere curiosity. Not a criticism of alternative statistical approaches: e.g., I could also use a Bayesian density estimate…

Furthermore, the estimate provided by the sample x1,…,xn is not of particular interest since its precision is imposed by the sample size n (and converging at non-parametric rates, which is not a particularly relevant issue!), while I could use importance sampling (or even numerical integration) if I was truly interested in c. I however find the discussion interesting for many reasons

  1. it somehow relates to the infamous harmonic mean estimator issue, often discussed on the’Og!;
  2. it brings more light on the paradoxical differences between statistics and Monte Carlo methods, in that statistics is usually constrained by the sample while Monte Carlo methods have more freedom in generating samples (up to some budget limits). It does not make sense to speak of estimators in Monte Carlo methods because there is no parameter in the picture, only “unknown” constants. Both fields rely on samples and probability theory, and share many features, but there is nothing like a “best unbiased estimator” in Monte Carlo integration, see the case of the “optimal importance function” leading to a zero variance;
  3. in connection with the previous point, the fascinating Bernoulli factory problem is not a statistical problem because it requires an infinite sequence of Bernoullis to operate;
  4. the discussion induced Chris Sims to contribute to StackExchange!

LGM 2012, Trondheim (3)

Posted in pictures, Running, Statistics, Travel, University life with tags , , , , , , , , on June 2, 2012 by xi'an

Last and final day of LGM 2012: it started most auspiciously with a bit of melted snow. The big news of the day however was [for me] that the next LGM was staged to take place in Reykjavik, Iceland. Indeed, Iceland is sharing top-of-the-list with Greenland and Patagonia for the countries I want to visit, one day, and I hope I will be able to attend and to take some time off to make a trek inland… Besides this personal (and therefore uninteresting!) happy event (!), the day contained a wealth of interesting talks, from Malgorzata Roos talking about using Hellinger distance to evaluate prior sensitivity (with the side impact of driving me posting a question on StackExchange about unbiased estimators of Hellinger distances!), to Aki Vehtari discussing cross-validation and other predictive entities (and concluding on the poor performances of DIC), to Luke Bornn proposing using auxiliary variables and warping to recover stationarity, to Alex Lenkoski achieving a fairly compelling advance by noticing that Gaussian graphical model selection can be handled outside the reversible jump framework, and more (including a machine-learning talk by Valeria Vitelli, now a next door neighbour at École Centrale, on the other side of Parc de Sceaux!). The conclusion talk by Gregor Gorjanc on statistical models for animal breeding genetics was more historical than methodological, however it should work as a nice refresher each time I need to make sure I understand the genetic vocabulary!

All in all, this was a wonderful workshop! New topics that I hope to study deeper, new people I was lucky to meet, most enjoyable city and running routes, hence a highly consistent choice of LGM meeting locations!, a superb sunset on the Trondheimsfjord the last evening, terrific breakfasts that border brunches, convenient travel connections (except for the last leg on the RER train from Charles de Gaulle where I got stuck for one hour)… Just great.

[not] Le Monde puzzle (solution)

Posted in R, Statistics, University life with tags , , , , , on April 14, 2012 by xi'an

Following the question on dinner table permutations on StackExchange (mathematics) and the reply that the right number was six, provided by hardmath, I was looking for a constructive solution how to build the resolvable 2-(20,5,1) covering. A few hours later. hardmath again came up with an answer, found in the paper Equitable Resolvable Coverings by van Dam, Haemers and Peek (2002). In the meanwhile (and even during the Big’MC seminar of yesterday!), I had been thinking of a simulated annealing implementation, which actually was used by van Dam, Haemers and Peek. Here is my (plain) R code

[sourcecode gutter=”false” language=”r”]
#initialisation of tables
#rows for individuals, columns for courses
T=sample(rep(1:4,5))
for (i in 2:6)
T=cbind(T,sample(rep(1:4,5)))
#encounters table
meet=function(T){
M=outer(T[,1],T[,1],"==")
for (i in 2:6)
M=M+outer(T[,i],T[,i],"==")
M
}
#number of missed encounters
penalty=function(M){ sum(M==0) }
penat=penalty(meet(T))

N=10^5
gamma=100

for (t in 1:N){
#random pick of switched individuals
prop=sample(1:20,2,prob=apply(meet(T)==0,1,sum))
cour=sample(1:6,1)
Tp=T
Tp[prop[1],cour]=T[prop[2],cour]
Tp[prop[2],cour]=T[prop[1],cour]
penatp=penalty(meet(Tp))
print(c(penat,penatp))

if (penatp==0){
T=Tp
break()
}

if (log(runif(1))<(penat-penatp)/gamma){
T=Tp
penat=penatp}

if (t%%10==0)
gamma=gamma*.999
}
[/sourcecode]

which happened to provide a solution on the second round (got stuck at a penalty of 4 in the first round):

[sourcecode gutter=”false” language=”r”]
> T
T
[1,] 1 4 3 2 2 3
[2,] 1 2 4 3 4 4
[3,] 3 2 1 4 1 3
[4,] 1 2 3 1 1 1
[5,] 4 2 4 2 3 3
[6,] 2 4 1 2 4 1
[7,] 4 3 1 1 2 4
[8,] 1 3 2 4 3 1
[9,] 3 3 3 3 4 3
[10,] 4 4 2 3 1 1
[11,] 1 1 1 3 3 2
[12,] 3 4 4 1 3 2
[13,] 4 1 3 4 4 2
[14,] 2 4 3 4 3 4
[15,] 2 3 4 2 1 2
[16,] 2 2 2 3 2 2
[17,] 2 1 2 1 4 3
[18,] 4 3 1 1 2 4
[19,] 3 1 4 4 2 1
[20,] 3 1 2 2 1 4
[/sourcecode]

(This makes a great example for my general public talk in Australia this summer/winter!)

[not] Le Monde puzzle (6)

Posted in University life with tags , , , , , , , on April 12, 2012 by xi'an

After posting the question on dinner table permutations on StackExchange (mathematics), I got almost instantaneously a reply that the right number was six, linking to the Covering chapter by Gordan and Stinson, taken from the second edition of Handbook of Combinatorial Designs. If I understand correctly this terse coverage that reminds me of Gradshteyn and Ryzhik’s monumental Table of Integrals, Series and Products, my question is connected to the covering number C(20,5,2), which is equal to 21 according to Table 1.33 of the above chapter. This is the minimum number of blocks such that every pair of points occurs in at least one block (element) of the collection of subsets of size 5 (the tables across courses). Now, in my problem, the interesting coverage is a resolvable coverage, i.e., a collection of tables that “can be partitioned into parallel classes, each of which consists of v/k[=4] disjoint blocks” (Definition 1.43). Then the number of parallel classes is r(4,5)=6, as provided by hardmath. Now the remaining question is how to build the resolvable 2-(20,5,1) covering, i.e. the table plans across the six courses… This may be related to a direct proof as to why a five course dinner does not work.