 Our paper Improving the Convergence Properties of the Data Augmentation Algorithm with an Application to Bayesian Mixture Modeling, written with Jim Hobert and Vivek Roy during their latest visit to Paris a few years ago (!), has now appeared in arXiv, Statistical Science and project Euclid. I already mentioned in a previous post why this is an important paper for me. (There is nothing new here, compared with this earlier post, except that the paper was re-posted on arXiv!)
Archive for Statistical Science
Improving convergence properties of the Data Augmentation algorithm
Posted in Statistics, University life with tags arXiv, Data augmentation, mixtures, Project euclid, Statistical Science on February 7, 2012 by xi'anImproving convergence of Data Augmentation [published]
Posted in Statistics with tags Data augmentation, Don Fraser, Fort Collins, Richard Tweedie, Statistical Science on November 4, 2011 by xi'anOur paper with Jim Hobert and Vivek Roy, Improving the Convergence Properties of the Data Augmentation Algorithm with an Application to Bayesian Mixture Modeling, has now appeared in Statistical Science and is available on Project Euclid. (For IMS members, at least.) Personally, this is an important paper, not only for providing an exact convergence evaluation for mixtures, not only for sharing exciting research days with my friends Jim and Vivek, but also for finalising a line of research somehow started in 1993 when Richard Tweedie visited me in Paris and when I visited him in Fort Collins… Coincidentally, my discussion of Don Fraser’s provocative Is Bayes Posterior just Quick and Dirty Confidence? also appeared in this issue of Statistical Science.
Don Fraser’s rejoinder
Posted in Books, Statistics, University life with tags Bayesian inference, Biometrika, confidence region, Don Fraser, Error and Inference, frequentist inference, Statistical Science on August 24, 2011 by xi'an“How can a discipline, central to science and to critical thinking, have two methodologies, two logics, two approaches that frequently give substantially different answers to the same problems. Any astute person from outside would say “Why don’t they put their house in order?”” Don Fraser
Following the discussions of his Statistical Science paper Is Bayes posterior just quick and dirty confidence?, by Kesar Singh and Minge Xie, Larry Wasserman (who coined the neologism Frasian for the occasion), Tong Zhang, and myself, Don Fraser has written his rejoinder to the discussion (although in Biometrika style it is for Statistical Science!). His conclusion that “no one argued that the use of the conditional probability lemma with an imaginary input had powers beyond confidence, supernatural powers” is difficult to escape, as I would not dream of promoting a super-Bayes jumping to the rescue of bystanders misled by evil frequentists!!! More seriously, this rejoinder makes me reflect on lectures from the past years, from those on the diverse notions of probability (Jeffreys, Keynes, von Mises, and Burdzy) to those on scientific discovery (mostly Seber‘s, and the promising Error and Inference by Mayo and Spanos I just received).
Bayes factors and martingales
Posted in R, Statistics with tags Bayes factor, Martin-Löf, martingales, Statistical Science on August 11, 2011 by xi'anA surprising paper came out in the last issue of Statistical Science, linking martingales and Bayes factors. In the historical part, the authors (Shafer, Shen, Vereshchagin and Vovk) recall that martingales were popularised by Martin-Löf, who is also influential in the theory of algorithmic randomness. A property of test martingales (i.e., martingales that are non negative with expectation one) is that

which makes their sequential maxima p-values of sorts. I had never thought about likelihood ratios this way, but it is true that a (reciprocal) likelihood ratio

is a martingale when the observations are distributed from p. The authors define a Bayes factor (for P) as satisfying (Section 3.2)

which I find hard to relate to my understanding of Bayes factors because there is no prior nor parameter involved. I first thought there was a restriction to simple null hypotheses. However, there is a composite versus composite example (Section 8.5, Binomial probability being less than or large than 1/2). So P would then be the marginal likelihood. In this case the test martingale is
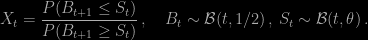
Simulating the martingale is straightforward, however I do not recover the picture they obtain (Fig. 6):
[sourcecode language=”r” gutter=”false”]
x=sample(0:1,10^4,rep=TRUE,prob=c(1-theta,theta))
s=cumsum(x)
ma=pbinom(s,1:10^4,.5,log.p=TRUE)-pbinom(s-1,1:10^4,.5,log.p=TRUE,lower.tail=FALSE)
plot(ma,type="l")
lines(cummin(ma),lty=2) #OR lines(cummin(ma),lty=2)
lines(log(0.1)+0.9*cummin(ma),lty=2,col="steelblue") #OR cummax
[/sourcecode]
When theta is not 1/2, the sequence goes down almost linearly to -infinity.
 but when theta is 1/2, I more often get a picture where max and min are obtained in the first steps:
 Obviously, I have not read the paper with the attention it deserved, so there may be features I missed that could be relevant for the Bayesian analysis of the behaviour of Bayes factors. However, at this stage, I fail to see the point of the “Puzzle for Bayesians” (Section 8.6) since the conclusion that “it is legitimate to collect data until a point has been disproven but not legitimate to interpret this data as proof of an alternative hypothesis within the model” is not at odds with a Bayesian interpretation of the test outcome: when the Bayes factor favours a model, it means this model is the most likely of the two given the data, not this model is true.
Estimation of covariance matrices
Posted in Statistics with tags arXiv, covariance matrix, James-Stein estimator, Statistical Science, Stein loss, Wishart distribution on June 21, 2011 by xi'anMathilde Bouriga and Olivier Féron have posted a paper on arXiv centred on the estimation of covariance matrices using inverse-Wishart priors. They introduce hyperpriors on the hyperparameters in the spirit of Daniels and Kass (JASA, 1999) and derive Bayes estimators as well as MCMC procedures. They then run a simulation comparison between the different priors in terms of frequentist risks, concluding in favour of the shrinkage covariance estimators that shrink all components of the empirical covariance matrix. (This paper is part of Mathilde’s thesis, which I co-advise with Jean-Michel Marin.)
More among interesting postings on arXiv, many of them published in Statistical Science:
-
Variable Selection for Nonparametric Gaussian Process Priors: Models and Computational Strategies by Terrance Savitsky, Marina Vannucci, Naijun Sha
-
Bayesian Statistical Pragmatism by Andrew Gelman (a discussion of the above)
-
A flexible observed factor model with separate dynamics for the factor volatilities and their correlation matrix by Yu-Cheng Ku, Peter Bloomfield, Robert Kohn
-
Test martingales, Bayes factors and p-values by Glenn Shafer, Alexander Shen, Nikolai Vereshchagin, Vladimir Vovk
-
Pitman-Yor Diffusion Trees by David A. Knowles, Zoubin Ghahramani


