Archive for sufficiency

sufficient statistics for machine learning

Posted in Books, Running, Statistics, Travel with tags , , , , , on April 26, 2022 by xi'an

By chance, I came across this ICML¹⁹ paper of Milan Cvitkovic and Günther Koliander, Minimal Achievable Sufficient Statistic Learning,  on a form of sufficiency for machine learning. The paper starts with “our” standard notion of sufficiency albeit in a predictive sense, namely that Z=T(X) is sufficient for predicting Y if the conditional distribution of Y given Z is the same as the conditional distribution of Y given X. It also acknowledges that minimal sufficiency may be out of reach. However, and without pursuing this question into the depths of said paper, I am surprised that any type of sufficiency can be achieved there since the model stands outside exponential families… In accordance with the Darmois-Pitman-Koopman lemma. Obviously, this is not a sufficiency notion in the statistical sense, since there is no likelihood (albeit there are parameters involved in the deep learning network). And Y is a discrete variate, which means that

\mathbb P(Y=1|x),\ \mathbb P(Y=2|x),\ldots

is a sufficient “statistic” for a fixed conditional, but I am lost at how the solution proposed in the paper, could be minimal when the dimension and structure of T(x) are chosen from the start. A very different notion, for sure!

Concentration and robustness of discrepancy-based ABC [One World ABC ‘minar, 28 April]

Posted in Statistics, University life with tags , , , , , , , , , , , on April 15, 2022 by xi'an

Our next speaker at the One World ABC Seminar will be Pierre Alquier, who will talk about “Concentration and robustness of discrepancy-based ABC“, on Thursday April 28, at 9.30am UK time, with an abstract reported below.
Approximate Bayesian Computation (ABC) typically employs summary statistics to measure the discrepancy among the observed data and the synthetic data generated from each proposed value of the parameter of interest. However, finding good summary statistics (that are close to sufficiency) is non-trivial for most of the models for which ABC is needed. In this paper, we investigate the properties of ABC based on integral probability semi-metrics, including MMD and Wasserstein distances. We exhibit conditions ensuring the contraction of the approximate posterior. Moreover, we prove that MMD with an adequate kernel leads to very strong robustness properties.

an insufficient puzzle

Posted in Books, Kids, Statistics with tags , , , on January 12, 2022 by xi'an

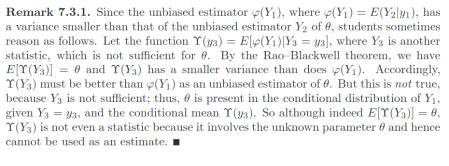
A rather peculiar and challenging question on X validated,  concerning the absolute impossibility of a conditional expectation, given a non-sufficient statistic, being still a statistic (i.e., being independent on the parameter θ). Inspired from the following except from Hogg and Craig. Namely, could there exist a specific function φ(·) such that E[φ(Y¹)|Y³] does not depend on the parameter θ? I could not find a satisfactory explanation right away (and the question remains unanswered!)

After posting this entry, I thought anew that cases when the unbiased estimator φ(Y¹) is not a bijective transform of Y¹ would work as a counter-example, since Y³=φ(Y¹) is not sufficient but E[φ(Y¹) |φ(Y¹) ]=φ(Y¹) is not involving θ… And this case does not exhibit a paradox in that the variance does not decrease any further.

conditioning on zero probability events

Posted in Books, Kids, pictures, Statistics, University life with tags , , , , on November 15, 2019 by xi'an

An interesting question on X validated as to how come a statistic T(X) can be sufficient when its support depends on the parameter θ behind the distribution of X. The reasoning there being that the distribution of X given T(X)=t does depend on θ since it is not defined for some values of θ … Which is not correct in that the conditional distribution of X depends on the realisation of T, meaning that if this realisation is impossible, then the conditional is arbitrary and of no relevance. Which also led me to tangentially notice and bemoan that most (Stack) exchanges on conditioning on zero probability events are pretty unsatisfactory in that they insist on interpreting P(X=x) [equal to zero] in a literal sense when it is merely a notation in the continuous case. And undefined when X has a discrete support. (Conditional probability is always a sore point for my students!)

p-values, Bayes factors, and sufficiency

Posted in Books, pictures, Statistics with tags , , , , , , , , , on April 15, 2019 by xi'an

Among the many papers published in this special issue of TAS on statistical significance or lack thereof, there is a paper I had already read before (besides ours!), namely the paper by Jonty Rougier (U of Bristol, hence the picture) on connecting p-values, likelihood ratio, and Bayes factors. Jonty starts from the notion that the p-value is induced by a transform, summary, statistic of the sample, t(x), the larger this t(x), the less likely the null hypothesis, with density f⁰(x), to create an embedding model by exponential tilting, namely the exponential family with dominating measure f⁰, and natural statistic, t(x), and a positive parameter θ. In this embedding model, a Bayes factor can be derived from any prior on θ and the p-value satisfies an interesting double inequality, namely that it is less than the likelihood ratio, itself lower than any (other) Bayes factor. One novel aspect from my perspective is that I had thought up to now that this inequality only holds for one-dimensional problems, but there is no constraint here on the dimension of the data x. A remark I presumably made to Jonty on the first version of the paper is that the p-value itself remains invariant under a bijective increasing transform of the summary t(.). This means that there exists an infinity of such embedding families and that the bound remains true over all such families, although the value of this minimum is beyond my reach (could it be the p-value itself?!). This point is also clear in the justification of the analysis thanks to the Pitman-Koopman lemma. Another remark is that the perspective can be inverted in a more realistic setting when a genuine alternative model M¹ is considered and a genuine likelihood ratio is available. In that case the Bayes factor remains smaller than the likelihood ratio, itself larger than the p-value induced by the likelihood ratio statistic. Or its log. The induced embedded exponential tilting is then a geometric mixture of the null and of the locally optimal member of the alternative. I wonder if there is a parameterisation of this likelihood ratio into a p-value that would turn it into a uniform variate (under the null). Presumably not. While the approach remains firmly entrenched within the realm of p-values and Bayes factors, this exploration of a natural embedding of the original p-value is definitely worth mentioning in a class on the topic! (One typo though, namely that the Bayes factor is mentioned to be lower than one, which is incorrect.)