 Our paper with Andrew Gelman, “Not only defended but also applied”: the perceived absurdity of Bayesian inference, has been reviewed for the second time and is to appear in The American Statistician, as a discussion paper. Terrific news! This is my first discussion paper in The American Statistician (and the second in total, the first one being the re-read of Jeffreys‘ Theory of Probability

Archive for William Feller
not only defended but also applied [to appear]
Posted in Books, Statistics, University life with tags Andrew Gelman, arXiv, ASA, discussion paper, Harold Jeffreys, The American Statistician, Theory of Probability, William Feller on June 12, 2012 by xi'annot only defended but also applied (rev’d)
Posted in Statistics with tags An Introduction to Probability Theory and Its Applications, Andrew Gelman, The American Statistician, William Feller on April 16, 2012 by xi'anFollowing a very positive and encouraging review by The American Statistician of our paper with Andrew Gelman on Feller’s misrepresentation of Bayesian statistics in the otherwise superb Introduction to Probability Theory , we have submited a revised version, now posted on arXiv. Hopefully, we will be able to publish this historic-philosophical note in The American Statistician, and maybe even get a discussion paper on the issue of misconceptions on Bayesian analysis.
the birthday problem [X’idated]
Posted in R, Statistics, University life with tags birthday, coincidence, R, William Feller on February 1, 2012 by xi'an The birthday problem (i.e. looking at the distribution of the birthdates in a group of n persons, assuming [wrongly] a uniform distribution of the calendar dates of those birthdates) is always a source of puzzlement [for me]! For instance, here is a recent post on Cross Validated:
I have 360 friends on facebook, and, as expected, the distribution of their birthdays is not uniform at all. I have one day with that has 9 friends with the same birthday. So, given that some days are more likely for a birthday, I’m assuming the number of 23 is an upperbound.
The figure 9 sounded unlikely, so I ran the following computation:
[sourcecode language=”r” gutter=”false”]
extreme=rep(0,360)
for (t in 1:10^5){
i=max(diff((1:360)[!duplicated(sort(sample(1:365,360,rep=TRUE)))]))
extreme[i]=extreme[i]+1
}
extreme=extreme/10^5
barplot(extreme,xlim=c(0,30),names=1:360)
[/sourcecode]
whose output shown on the above graph. (Actually, I must confess I first forgot the sort in the code, which led me to then believe that 9 was one of the most likely values and post it on Cross Validated! The error was eventually picked by one administrator. I should know better than trust my own R code!) According to this simulation, observing 9 or more people having the same birthdate has an approximate probability of 0.00032… Indeed, fairly unlikely!
Incidentally, this question led me to uncover how to print the above on this webpage. And to learn from the X’idated moderator whuber the use of tabulate. Which avoids the above loop:
[sourcecode language=”r” gutter=”false”]
> system.time(test(10^5)) #my code above
user system elapsed
26.230 0.028 26.411
> system.time(table(replicate(10^5, max(tabulate(sample(1:365,360,rep=TRUE))))))
user system elapsed
5.708 0.044 5.762
[/sourcecode]
[weak] information paradox
Posted in pictures, Running, Statistics, University life with tags binomial coefficient, binomial distribution, combinatorics, cross validated, elm tree, MAP estimators, William Feller on December 2, 2011 by xi'an While (still!) looking at questions on Cross Validated on Saturday morning, just before going out for a chilly run in the park, I noticed an interesting question about a light bulb problem. Once you get the story out of the way, it boils down to the fact that, when comparing two binomial probabilities, p1 and p2, based on a Bernoulli sample of size n, and when selecting the MAP probability, having either n=2k-1 or n=2k observations lead to the same (frequentist) probability of making the right choice. The details are provided in my answers here and there. It is a rather simple combinatoric proof, once you have the starting identity [W. Feller, An Introduction to Probability Theory and Its Applications, vol. 1, 1968, [II.8], eqn (8.6)]
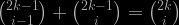
but I wonder if there exists a more statistical explanation to this weak information paradox…
“Not only defended but also applied”: The perceived absurdity of Bayesian inference
Posted in Books, Statistics, University life with tags An Introduction to Probability Theory and Its Applications, Andrew Gelman, Bayesian inference, bogosity, doomsday argument, foundations, The American Statistician, William Feller on October 13, 2011 by xi'anAfter a first unsuccessful attempt at publishing a note on the great Willliam Feller’s dismissive attitude towards Bayesian statistics, in An Introduction to Probability Theory and Its Applications, and more broadly about misconceptions on Bayesianism, jointly with Andrew Gelman, last year, we have rewritten some of it and resubmitted to The American Statistician. It has also been re-arXived. Here is the abstract:
Abstract. The missionary zeal of many Bayesians has been matched, in the other direction, by a view among some theoreticians that Bayesian methods are absurd—not merely misguided but obviously wrong in principle. We consider several examples, beginning with Feller’s classic text on probability theory and continuing with more recent cases such as the perceived Bayesian nature of the so-called doomsday argument. We analyze in this note the intellectual background behind various misconceptions about Bayesian statistics, without aiming at a complete historical coverage of the reasons for this dismissal.


