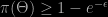Archive for Bayesian inference

Bertrand’s paradox [re]solved?

Posted in Books, pictures, Statistics, Travel with tags , , , , , , , , , , , on September 29, 2023 by xi'an

On the plane back from Vancouver, I read Bertrand’s Paradox Resolution and Its Implications for the Bing–Fisher Problem by Richard A. Chechile [who had pointed out his paper to me] In this paper, Chechile considers the Bayesian connections/sequences of Betrand’s paradox, as he sees it Bertrand’s different solutions/paradox to be

“designed to illustrate his dissatisfaction with the Bayes and Laplace use of a probability distribution to represent an unknown parameter that can have any continuous value”

and proposes to “resolve” this paradox, which imho is neither a paradox nor in need of a resolution!, as I see it more like a reflection on the importance of sigma algebras and measure theory. The uniform distribution (behind the “random” chord) is not a uniquely specified concept, just like the maximum entropy distribution is relative to the dominating measure. When arguing that

“Such a definition [based on any possible distribution of a stochastic chord] would yield a random variable, but this weak sense of the word random is not satisfactory, because there is an infinite number of stochastic processes that can be defined to yield a probability distribution of chord lengths.”

the author is simply restating that infinite collection of dominating measures.  But imho he is somewhat missing this point when defining Shannon`s entropy by resorting to a discrete version. And when adopting a uniform measure on the chord as a reference (Section 3.2, on The Importance of a Dominant Metric Representation). While the probability P(L>1) is invariant under any increasing transform of L (and 1)… This amounts to arguing for a favourite parameterisation in constructing  a reference prior (Section 4, where Jeffreys prior is also dismissed for not being at maximum entropy). The ensuing discussion as to why the three solutions of Bertrand’s are not valid (Section 2.2) is thus most curious to me since they all are implementable/practical ways of producing stochastic chords. I find it rather amusing that one returns to the quest for the ideal priori distribution Bayesians were so fiercely debating at the turn of the previous century. And non-Bayesians were all too happy to exploit when arguing against this approach.

Bayesian differential privacy for free?

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on September 24, 2023 by xi'an

“We are interested in the question of how we can build differentially-private algorithms within the Bayesian framework. More precisely, we examine when the choice of prior is sufficient to guarantee differential privacy for decisions that are derived from the posterior distribution (…) we show that the Bayesian statistician’s choice of prior distribution ensures a base level of data privacy through the posterior distribution; the statistician can safely respond to external queries using samples from the posterior.”

Recently I came across this 2016 JMLR paper of Christos Dimitrakakis et al. on “how Bayesian inference itself can be used directly to provide private access to data, with no modification.” Which comes as a surprise since it implies that Bayesian sampling would be enough, per se, to keep both the data private and the information it conveys available. The main assumption on which this result is based is one of Lipschitz continuity of the model density, namely that, for a specific (pseudo-)distance ρ

|\log f(x|\theta)-\log f(y|\theta)|\le L\rho(x,y)

uniformly in θ over a set Θ with enough prior mass

\pi(\Theta)\ge 1-e^{-\epsilon}

for an ε>0. In this case, the Kullback-Leibler divergence between the posteriors π(θ|x) and π(θ|y) is bounded by a constant times ρ(x,y). (The constant being 2L when Θ is the entire parameter space.) This condition ensures differential privacy on the posterior distribution (and even more on the associated MCMC sample). More precisely, (2L,0)-differentially private in the case Θ is the entire parameter space. While there is an efficiency issue linked with the result since the bound L being set by the model and hence immovable, this remains a fundamental result for the field (as shown by its high number of citations).

approximate computation for exact statistical inference from differentially private data

Posted in Books, Mountains, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , , , , on September 10, 2023 by xi'an

“the employment of ABC for differentially private data serendipitously eradicates the “approximate” nature of the resulting posterior  samples, which otherwise would be the case if the data were noise-free.”

In parallel or conjunction with the 23w5601 workshop, I was reading some privacy literature and came across this Exact inference with approximate computation for differentially private data via perturbation by Ruobin Gong  that appeared in the Journal of Privacy and Confidentiality last year (2022). When differential privacy is implemented by perturbation, i.e. by replacing the private data with a randomised, usually Gaussian, version, the exact posterior distribution is a convolution which, if unavailable, can be approximated by a standard ABC step. Which, most interestingly does not impact the accuracy of the (public) posterior, i.e. it does not modify this posterior when the probability of acceptance in ABC is the density of the perturbation noise at the public data given the pseudo-data. Which follows from the 1984 introduction of the ABC idea. On the opposite, EM does not enjoy an exact version, as the E step must be (unbiasedly) approximated by a Monte Carlo representation that relies on the same ABC algorithm. Which usually makes the M step harder, although a Monte Carlo version of the gradient is also available.

differentially private distributed Bayesian linear regression with MCMC

Posted in Books, pictures, Statistics, University life with tags , , , , , , , , , on August 30, 2023 by xi'an

An ICML 2023 paper by Barıs¸ Alparslan, Sinan Yıldırım¸ and Ilker Birbil that (re)addresses the issue of privacy when running a Bayesian regression analysis. Resorting to the common notion of differential privacy, imposing a limited variability if a single observation is modified, and a Gaussian randomisation of the observations.

“A differentially private algorithm constrains the difference between the probability distributions of the output values obtained from neighbouring data sets”

In the super classical setup of simple Normal linear regression, y=Xθ+σε. Summary statistics are chosen as

S=X’X and z=X’y,

(why the separation?) then randomised. (Keeping Ŝ definite positive? Not necessarily, it appear.) Inspired directly from Dwork & al. (2014). The authors still manage to spend an entire column in (re)deriving the conditional Normal distribution of z conditional on S and (θ,σ)… Which is later exploited for integrating z out in the MCMC algorithm.

“some important differences between our work and that of Bernstein & Sheldon (2019) [stem] from the choice of summary statistics and the consequent hierarchical structure used for modelling linear regression [and]lead to significant differences in the inference methods as well as significant computational advantages [O(d³) vs. O(d⁶)]”

In a distributed setting several agents are handling their own data and keep their privacy by the same mechanishttps://www.slideshare.net/xianblog/discussion-of-icml23pdfm [as in the top graph from the paper]. On principle, a Bayesian analysis of the resulting hierarchical model should directly consider the posterior on the global parameter by considering the distributions of the randomised pairs (ẑ,Ŝ). The elephant in the room is the distribution of the regressors, which is customarily unknown and not accounted for in a traditional Bayesian analysis. It is needed here due to the division in S and z, plus the randomisation step that calls for the posterior distribution of S given Ŝ. Elephant that is exfiltrated by either assuming Normality or substituting Ŝ for S without accounting for the noise! Definitely not exactly Bayesian. Another column is spent on the Metropolis-within-Gibbs simulation of the posterior…

Overall, I remain reserved about this approach, since it does not follow a clear Bayesian pathway and in particular does not incorporate privacy as part of the Bayesian decision analysis.

a versatile alternative to ABC

Posted in Books, Statistics with tags , , , , , , , , , on July 25, 2023 by xi'an

“We introduce the Fixed Landscape Inference MethOd, a new likelihood-free inference method for continuous state-space stochastic models. It applies deterministic gradient-based optimization algorithms to obtain a point estimate of the parameters, minimizing the difference between the data and some simulations according to some prescribed summary statistics. In this sense, it is analogous to Approximate Bayesian Computation (ABC). Like ABC, it can also provide an approximation of the distribution of the parameters.”

I quickly read this arXival by Monard et al. that is presented as an alternative to ABC, while outside a Bayesian setup. The central concept is that a deterministic gradient descent provides an optimal parameter value when replacing the likelihood with a distance between the observed data and simulated synthetic data indexed by the current value of the parameter (in the descent). In order to operate the descent the synthetic data is assumed to be available as a deterministic transform of the parameter value and of a vector of basic random objects, eg Uniforms. In order to make the target function differentiable, the above Uniform vector is fixed for the entire gradient descent. A puzzling aspect of the paper is that it seems to compare the (empirical) distribution of the resulting estimator with a posterior distribution, unless the comparison is with the (empirical) distribution of the Bayes estimators. The variability due to the choice of the fixed vector of basic random objects does not seem to be taken into account either, apparently. Furthermore, the method is presented as able to handle several models at once, which I find difficult to fathom as (a) the random vectors behind each model necessarily vary and (b) there is no apparent penalisation for complexity.