Archive for bias

neural importance sampling

Posted in Books, Kids, pictures, Statistics, University life with tags , , , , , , , , , , on May 13, 2020 by xi'an

Dennis Prangle signaled this paper during his talk of last week, first of our ABC ‘minars now rechristened as The One World ABC Seminar to join the “One World xxx Seminar” franchise! The paper is written by Thomas Müller and co-authors, all from Disney research [hence the illustration], and we discussed it in our internal reading seminar at Dauphine. The authors propose to parameterise the importance sampling density via neural networks, just like Dennis is using auto-encoders. Starting with the goal of approximating
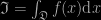
\mathfrak I=\int_{\mathfrak D} f(x)\text{d}x

(where they should assume f to be non-negative for the following), the authors aim at simulating from an approximation of f(x)/ℑ since this “ideal” pdf would give zero variance.

“Unfortunately, the above integral is often not solvable in closed form, necessitating its estimation with another Monte Carlo estimator.”

Among the discussed solutions, the Latent-Variable Model one is based on a pdf represented as a marginal. A mostly intractable integral, which the authors surprisingly seem to deem an issue as they do not mention the standard solution of simulating from the joint and using the conditional in the importance weight. (Or even more surprisingly and obviously wrongly see the latter as a biased approximation to the weight.)

“These “autoregressive flows” offer the desired exact evaluation of q(x;θ). Unfortunately, they generally only permit either efficient sample generation or efficient evaluation of q(x;θ), which makes them prohibitively expensive for our application to Mont Carlo integration.”

When presenting normalizing flows, namely the representation of the simulation output as the result of an invertible mapping of a standard (e.g., Gaussian or Uniform) random variable, x=h(u,θ), which can itself be decomposed into a composition of suchwise functions. And I am thus surprised this cannot be done in an efficient manner if transforms are well chosen…

“The key proposition of Dinh et al. (2014) is to focus on a specific class of mappings—referred to as coupling layers—that admit Jacobian matrices where determinants reduce to the product of diagonal terms.

Using a transform with a triangular Jacobian at each stage has the appeal of keeping the change of variable simple and allowing for non-linear transforms. Namely piecewise polynomials. When reading the one-blob (!) encoding , I am however uncertain the approach is more than the choice of a particular functional basis, as for instance wavelets (which may prove more costly to handle, granted!)

“Given that NICE scales well to high-dimensional problems…”

It is always unclear to me why almost every ML paper feels the urge to redefine & motivate the KL divergence. And to recall that it avoids bothering about the normalising constant. Looking at the variance of the MC estimator & seeking minimal values is praiseworthy, but only when the variance exists. What are the guarantees on the density estimate for this to happen? And where are the arguments for NICE scaling nicely to high dimensions? Interesting intrusion of path sampling, but is it of any use outside image analysis—I had forgotten Eric Veach’s original work was on light transport—?

rare ABC [webinar impressions]

Posted in Books, Statistics, Travel, University life with tags , , , , , , , on April 28, 2020 by xi'an

A second occurrence of the One World ABC seminar by Ivis Kerama, and Richard Everitt (Warwick U), on their on-going pape with and Tom Thorne, Rare Event ABC-SMC², which is not about rare event simulation but truly about ABC improvement. Building upon a previous paper by Prangle et al. (2018). And also connected with Dennis’ talk a fortnight ago in that it exploits an autoencoder representation of the simulated outcome being H(u,θ). It also reminded me of an earlier talk by Nicolas Chopin.

This approach avoids using summary statistics (but relies on a particular distance) and implements a biased sampling of the u’s to produce outcomes more suited to the observation(s). Almost sounds like a fiducial ABC! Their stopping rule for decreasing the tolerance is to spot an increase in the variance of the likelihood estimates. As the method requires many data generations for a single θ, it only applies in certain settings. The ABC approximation is indeed used as an estimation of likelihood ratio (which makes sense for SMC² but is biased because of ABC). I got slightly confused during Richard’s talk by his using the term of unbiased estimator of the likelihood before I realised he was talking of the ABC posterior. Thanks to both speakers, looking forward the talk by Umberto Picchini in a fortnight (on a joint paper with Richard).

biased sample!

Posted in Statistics with tags , , , , , , , , , , , on May 21, 2019 by xi'an

A chance occurrence led me to this thread on R-devel about R sample function generating a bias by taking the integer part of the continuous uniform generator… And then to the note by Kellie Ottoboni and Philip Stark analysing the reason, namely the fact that R uniform [0,1) pseudo-random generator is not perfectly continuously uniform but discrete, by the nature of numbers on a computer. Knuth (1997) showed that in this case the range of probabilities is larger than (1,1), the largest range being (1,1.03). As noted in the note, exploiting directly the pseudo-random bits of the pseudo-random generator. Shocking, isn’t it!  A fast and bias-free alternative suggested by Lemire is available as dqsample::sample

As an update of June 2019, sample is now fixed.

visualising bias and unbiasedness

Posted in Books, Kids, pictures, R, Statistics, University life with tags , , , , , , , , , on April 29, 2019 by xi'an

A question on X validated led me to wonder at the point made by Christopher Bishop in his Pattern Recognition and Machine Learning book about the MLE of the Normal variance being biased. As it is illustrated by the above graph that opposes the true and green distribution of the data (made of two points) against the estimated and red distribution. While it is true that the MLE under-estimates the variance on average, the pictures are cartoonist caricatures in their deviance permanence across three replicas. When looking at 10⁵ replicas, rather than three, and at samples of size 10, rather than 2, the distinction between using the MLE (left) and the unbiased estimator of σ² (right).

When looking more specifically at the case n=2, the humongous variability of the density estimate completely dwarfs the bias issue:

Even when averaging over all 10⁵ replications, the difference is hard to spot (and both estimations are more dispersed than the truth!):

no country for old biases

Posted in Books, Kids, Statistics with tags , , , , , on March 20, 2018 by xi'an

Following a X validated question, I read a 1994 paper by Phil Dawid on the selection paradoxes in Bayesian statistics, which first sounded like another version of the stopping rule paradox. And upon reading, less so. As described above, the issue stands with drawing inference on the index and value, (i⁰,μ⁰), of the largest mean of a sample of Normal rvs. What I find surprising in Phil’s presentation is that the Bayesian analysis does not sound that Bayesian. If given the whole sample, a Bayesian approach should produce a posterior distribution on (i⁰,μ⁰), rather than follow estimation steps, from estimating i⁰ to estimating the associated mean. And if needed, estimators should come from the definition of a particular loss function. When, instead, given the largest point in the sample, and only that point, its distribution changes, so I am fairly bemused by the statement that no adjustment is needed.

The prior modelling is also rather surprising in that the priors on the means should be joint rather than a product of independent Normals, since these means are compared and hence comparable. For instance a hierarchical prior seems more appropriate, with location and scale to be estimated from the whole data. Creating a connection between the means… A relevant objection to the use of independent improper priors is that the maximum mean μ⁰ then does not have a well-defined measure. However, I do not think a criticism of some priors versus other is a relevant attack on this “paradox”.