 This afternoon, Jean-Michel Marin gave his talk at the big’MC seminar. As already posted, it was about a convergence proof for AMIS, which gave me the opportunity to simultaneously read the paper and listen to the author. The core idea for adapting AMIS towards a manageable version is to update the proposal parameter based on the current sample rather than on the whole past. This facilitates the task of establishing convergence to the optimal (pseudo-true) value of the parameter, under an assumption that the optimal value is a know moment of the target. From there, convergence of the weighted mean is somehow natural when the number of simulations grows to infinity. (Note the special asymptotics of AMIS, though, which are that the number of steps goes to infinity while the number of simulations per step grows a wee faster than linearly. In this respect, it is the opposite of PMC, where convergence is of a more traditional nature, pushing the number of simulations per step to infinity.) The second part of the convergence proof is more intricate, as it establishes that the multiple mixture estimator based on the “forward-backward” reweighting of all simulations since step zero does converge to the proper posterior moment. This relies on rather complex assumptions, but remains a magnificent tour de force. During the talk, I wondered if, given the Markovian nature of the algorithm (since reweighting only occurs once simulation is over), an alternative estimator based on the optimal value of the simulation parameter would not be better than the original multiple mixture estimator: the proof is based on the equivalence between both versions….
Archive for convergence
AMIS convergence, at last!
Posted in Statistics, University life with tags AMIS, Big'MC, convergence, importance sampling, PMC, seminar, unbiasedness on November 19, 2012 by xi'anABC as knn…
Posted in Statistics with tags ABC, convergence, DIYBAC, economics, k-nearest neighbours on September 13, 2012 by xi'anGérard Biau, Frédéric Cérou, and Arnaud Guyader recently posted an arXiv paper on the foundations of ABC, entitled “New insights into Approximate Bayesian Computation“. They also submitted it to several statistics journals, with no success so far, and I find this rather surprising. Indeed, the paper analyses the ABC algorithm the way it is truly implemented (as in DIYABC for instance), i.e. with a tolerance bound ε that is determined as a quantile of the simulated distances, say the 10% or the 1% quantile. This means in particular that the interpretation of ε as a non-parametric bandwidth, while interesting and prevalent in the literature (see, e.g., Fearnhead and Prangle’s discussion paper), is only an approximation of the actual practice.
The authors of this new paper focus on the mathematical foundations of this practice, by (re)analysing ABC as a k-nearest neighbour (knn) method. Using generic knn results, they thus derive a consistency property for the ABC algorithm by imposing some constraints upon the rate of decrease of the quantile as a function of n. (The setting is restricted to the use of sufficient statistics or, equivalently, to a distance over the whole sample. The issue of summary statistics is not addressed by the paper.) The paper also contains a perfectly rigorous proof (the first one?) of the convergence of ABC when the tolerance ε goes to zero. The mean integrated square error consistency of the conditional kernel density estimate is established for a generic kernel (under usual assumptions). Further assumptions (on the target and on the kernel) allow the authors to obtain precise convergence rates (as a power of the sample size), derived from classical k-nearest neighbour regression, like

in dimensions m larger than 4…. The paper is completely theoretical and highly mathematical (with 25 pages of proofs!), which may explain why it did not meet with success with editors and/or referees, however I definitely think (an abridged version of) this work clearly deserves publication in a top statistics journal as a reference for the justification of ABC! The authors also mention future work in that direction: I would strongly suggest they consider the case of the insufficient summary statistics from this knn perspective.
potentially relevant
Posted in pictures, Statistics, Travel, University life with tags ABC, asymptotics, Bayes factors, Bayesian model choice, consistency, convergence, JRSSB, methodology, Ratmann, refereeing, Series B, sufficiency, summary statistics on March 14, 2012 by xi'an This week, freshly back from Roma, I got the reviews on our paper “Relevant statistics for Bayesian model choice” from Series B. The comments are detailed and mostly to the point, expressing concern about the relevance of the paper for statistical methodology as the major issue. We are thus asked for a revision making a much better connection with ABC methodology.
This is not an unexpected outcome, from my point of view, because the paper is indeed quite theoretical and the mathematical assumptions required to obtain the convergence theorems are rather overwhelming… Meaning that in practical cases they cannot truly be checked. However, I think we can eventually address those concerns for two distinct reasons: first, the paper comes as a third step in a series of papers where we first identified a sufficiency property, then realised that this property was actually quite a rare occurrence, and finally made a theoretical advance as to when is a summary statistic enough (i.e. “sufficient” in the standard sense of the term!) to conduct model choice, with a clear answer that the mean ranges of the summary statistic under each model could not intersect. Second, my own personal view is that those assumptions needed for convergence are not of the highest importance for statistical practice (even though they are needed in the paper!) and thus that, from a methodological point of view, only the conclusion should be taken into account. It is then rather straightforward to come up with (quick-and-dirty) simulation devices to check whether a summary statistic behaves differently under both models, taking advantage of the reference table already available (instead of having to run Monte Carlo experiments with ABC basis)…
One of the comments was that maybe Bayes factors were not appropriate for conducting model choice, thus making the whole derivation irrelevant. This is a possible perspective but it can be objected that Bayes factors and posterior probabilities are used in conjunction with ABC in dozens of genetic papers. Further arguments are provided in the various replies to both of Templeton’s radical criticisms. That more empirical and model-based assessments also are available is quite correct, as demonstrated in the multicriterion approach of Olli Ratmann and co-authors. This is simply another approach, not followed by most geneticists so far…

updated slides for ABC PhD course
Posted in pictures, R, Statistics, Travel, University life with tags ABC, convergence, CREST, HMM, Malakoff, Melbourne, PhD course, Roma on February 8, 2012 by xi'an Over the weekend, I have added a few slides referring to recent papers mentioning the convergence of ABC algorithms, in particular the very relevant paper by Dean et al. I had already discussed in an earlier post. (This coursing is taking a much larger chunk of my time than I expected! I am thus relieved I will use the same slides in Roma next month and presumably in Melbourne next summer…)
Harmonic means, again
Posted in Statistics, University life with tags arXiv, Bayes factors, bias, convergence, evidence, exoplanet, harmonic mean estimator, importance sampling, marginal likelihood on January 3, 2012 by xi'anOver the non-vacation and the vacation breaks of the past weeks, I skipped a lot of arXiv postings. This morning, I took a look at “Probabilities of exoplanet signals from posterior samplings” by Mikko Tuomi and Hugh R. A. Jones. This is a paper to appear in Astronomy and Astrophysics, but the main point [to me] is to study a novel approximation to marginal likelihood. The authors propose what looks at first as defensive sampling: given a likelihood f(x|θ) and a corresponding Markov chain (θi), the approximation is based on the following importance sampling representation
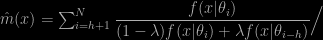
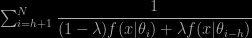
This is called a truncated posterior mixture approximation and, under closer scrutiny, it is not defensive sampling. Indeed the second part in the denominators does not depend on the parameter θi, therefore, as far as importance sampling is concerned, this is a constant (if random) term! The authors impose a bounded parameter space for this reason, however I do not see why such an approximation is converging. Except when λ=0, of course, which brings us back to the original harmonic mean estimator. (Properly rejected by the authors for having a very slow convergence. Or, more accurately, generally no stronger convergence than the law of large numbers.) Furthermore, the generic importance sampling argument does not work here since, if

is the importance function, the ratio

does not simplify… I do not understand either why the authors compare Bayes factors approximations based on this technique, on the harmonic mean version or on Chib and Jeliazkov’s (2001) solution with both DIC and AIC, since the later are not approximations to the Bayes factors. I am therefore quite surprised at the paper being accepted for publication, given that the numerical evaluation shows the impact of the coefficient λ does not vanish with the number of simulations. (Which is logical given the bias induced by the additional term.)


