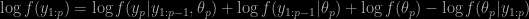Archive for harmonic mean estimator

easily computed marginal likelihoods for multivariate mixture models using the THAMES estimator

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , on May 25, 2025 by xi'an

Martin Metodiev and his coauthor(es)s have produced another paper on the THAMES Monte Carlo method when specifically targetting marginal likelihoods for mixture models. Since this problem has long been a central interest of mine’s and since the method is closely connected with the harmonic mean solution we developed with Darren Wraith in 2009, (and also included in our 2009 survey with Jean-Michel Marin of evidence approximations, published in Frontiers of Statistical Decision Making and Bayesian Analysis for Jim Berger’s 60th birthday), I quickly went into the paper. The core purpose of this paper is to adapt THAMES to a multimodal setting since using an ellipsoidal region as the support of the Uniform reciprocal importance sampling distribution does not make sense for a multimodal target. After reading it a few times, and while some computational aspects remain obscure to me, I am not convinced this brings an adequate answer to the challenge.  Indeed, while the approach borrows directly from Berkhof et al. (2003) that inspired the resolution we proposed, Jeong (Kate) Lee and myself, the issues I have with the current proposal are that

1. the evacuation of earlier methods as not simple or not universal enough is rather disingenuous. For instance, software that do not return (latent) allocation vectors can easily be post-processed. And the current method uses allocation probabilities just the same (in Section 3.3). Similarly, the random shuffling answer to label (lack of) switching proposed by Sylvia Früwirth-Schnatter—which again can be achieved by post-processing—cannot be rejected on the sole basis that the component means (based on the MCMC sample) are all similar. It is furthermore debatable that the current proposal is simple, when involving relabelling à la Stephens, averaging over permutations, selecting over said permutations by constructing a graph over components (section 3.2.1) and  running a quadratic discriminant analysis (section 3.2.2) on the posterior sample, based on an arbitrary Normal representation of the distributions of the clusters, and finally defining a new ordering constraint (section 3.2.3). Computing efforts  required by the respective methods do not appear in the main text.

2. the handling of the label switching issue—the reason why Larry Wasserman saw mixtures at the same magnitude of evil as tequila!—is problematic for several reasons. My position (since at least 2000!) on the matter is that the proper posterior sample must exhibit label switching and come close to symmetry among the “components”. The label switching problem (section 3.1) is rather when the MCMC sample does not “switch their labels”. The relabelling approach (e.g., à la Stephens) allows for a differentiation between components, to some extent, which helps with computing basic posterior moments for point estimation or for the calibration of the support of the Uniform reciprocal importance sampling distribution, but the use of any relabelling procedure is tampering with the original MCMC sample and thus bound to impact the distribution of the resulting relabelled sample. Furthermore, relabelling depends on the value of G, whereas the actual number of (significant) modes in the posterior is also connected with the (partial) fit of the data to the model, meaning the creation of further modes than those linked with relabelling. Especially when the model is misspecified. Incidentally, the symmetrised version of THAMES (5) does not require relabelling. Neither does the Bayes factor. In addition, the experiment section (4.1.2) mentions that bridge sampling is biased by a factor of G!, which comes as a surprise to me since I associated this factor with the call to Sid Chib’s formula in the absence of label switching, i.e. when the MCMC sample was stuck on a mode, as exposed by Radford Neal in 1999. Is it because bridge sampling is applied to the relabelled sample? It is also surprising that the gap appears in the simulated datasets (Fig.3) and not in the real ones (Fig.5).

3. the (legitimate) purpose of using marginal likelihoods for selecting the number G of components is weakened by the intrusion of alternate proposals to assess G from the data, like the criterion of overlap (section 3.2.1), which instead aims at the number of clusters, with an elimination of “empty components” that should either remain a possibility (within a regular mixture model) or be evacuated with a different modelling (à la Diebolt & Robert, or à la Wasserman). This overlapping criterion is further used in the discriminant analysis that only applies to “non-overlapping components” of the mixture (section 3.2.3)—at which point I got lost in the reordering and simplification of the computation of THAMES (but got reminded of the results of Agostino Nobile in the 2000’s, with whom I used to discuss a lot in my yearly visit to the University of Glasgow).

4. several mentions are made of the other estimators being biased, which is indeed the case for bridge sampling (if not necessarily for importance sampling), but not necessarily a central issue, while the original generalised harmonic proposal by Gelfand and Dey (1994) and thus THAMES produce an unbiased estimator of the inverse of the evidence (thus neither of the evidence nor of the log-evidence). However, in the paper, the volume of the support of the Uniform reciprocal importance sampling distribution is estimated by a basic Monte Carlo coverage probability in (3), which induces the same type of bias as the other methods.

gentle importance sampling

Posted in Books, pictures, Statistics with tags , , , , , , , , , , , , on February 24, 2025 by xi'an

A new (and gentle!) survey by Luca Martino! And by Fernando Llorente. On importance sampling, with coverage of normalised and self-normalised versions. And their usage in different configurations (one vs several integrals, one vs several families of distributions). Some points relating to earlier remarks or musing of mine’s:

  • the fact that the optimal importance function does not lead to a zero variance importance estimator when the integrand f is not of constant sign (p.7) can be cancelled by first decomposing f as f⁺-f⁻, since both allow for a zero variance importance estimator, if formally requiring two different samples (of size zero!), a trick considered later on p.18 and repeated for the ratio in self-normalised importance (p.19)
  • the special case when the integrand f is constant is not of practical interest but relevant for checking properties of different estimators. For instance, this case allowed George and myself to spot a mistake in an early importance paper. In the same volume of the Comptes Rendus as an early paper of Lions and Villani.
  • the remark that self-normalised (SNIS) importance sampling can prove more efficient than (properly normalised) importance sampling, although the property that SNIS is always bounded should not be seen as a major point given that it is simply due to using a finite sample and hence a finite set of images of f
  • the case of integrals involving several target pdfs or several integrands is not necessarily of major interest if simulating different samples for each unidimensional integral can be implemented (again formally leading to zero variance at no cost)
  • the issue of merging several estimators in an optimal way is briefly mentioned in §5.4, a challenge Victor Elvira and I have been approaching over the past years, if not yet concluding satisfactorily (mea culpa)
  • when replacing the target with a noisy estimate (p.22), the fact that this estimate must be normalised is correct, but pales against the impact of using this estimate, which may prove catastrophic. And unbiasedness is not particularly crucially important in this setup for the same reason
  • the section on evidence approximation (§7) is more standard, with the harmonic mean estimator being called reverse importance sampling, which brings us to the “elephant in the room”, namely that
  • the issue of infinite variance of some importance sampling estimators is not directly covered (except once in §8, p.34), thus perceiving importance sampling as a variance reduction method being somewhat misleading (unless the authors consider solely the optimal importance function, which is rarely of practical use)

The paper concludes with an interesting notion that

“we suggest the analysis of the relevant connection between importance sampling and contrastive learning Gutmann and Hyvärinen (2012)”

that I also have been pointing out for a while. All in all, a useful summing-up that I will likely suggest to my students.

R[are]SS meeting

Posted in Statistics, Travel, University life with tags , , , , , , , , , , , , , , , , , , on September 29, 2024 by xi'an


Yesterday, I happened to be at the right time in the right place, as I was in Warwick for a RSS local section meeting on rare event simulation. (If missing the aurora borealis and the moon eclipse on previous nights!) And hence attended a seminar by Francesca Crucinio in six days!, as she talked about a turnkey approach to unbiased estimation of transforms of a moment, or wlog a mean μ, f(μ). A recent article with Nicolas Chopin (CREST) and Sumeet Singh, where they resort to Taylor expansions to achieve unbiasedness, using the Russian roulette trick to stop the summation from running to infinity. (As it happens, I heard Nicolas talk about this idea in the recent past namely at the ISBA-Fusion Sunday morn at Ca’Foscari.) Using a Taylor expansion is obviously natural and mathematically correct, albeit fraught with potential dangers [imho]:

  • the Taylor expansion involves central moments up to a random order R, which are harder & harder to estimate with increasing orders (i.e., more & more uncertain, with the possibility of infinite variance estimators after a certain order)
  • I did not spot a discussion on the moment estimators, that seems to rely on k iid replicas for the k-th moment
  • a lot of calibration ensues, from the choice of the centre x⁰ to the (artificial) distribution of the stopping value R, to the parameterisation of the random variable attached to the moment μ
  • the paper insists on recycling simulations to stabilise the moment estimators and ensure consistency, as a primary level of Rao-Blackwellisation, but this only applies to the smallest order moments and could be devised in many different ways, with varying computing costs
  • consistency of the estimate is not necessarily needed, as for instance for pseudo-marginal applications
  • as often with Russian roulette, positive quantities may receive negative estimations that are dominated by truncations to the positive real line (and alternating series offer the use of sandwiching estimators)
  • for the above reason, it is not always reasonable to tunnel vision on unbiasedness and alternative estimates like bridge sampling solutions could be integrating towards improving the quality of the estimator (especially since the conditions for finite variance involve unknown quantities)
  • while f-Taylored solutions like harmonic mean estimators for f(x)=1/x are not necessarily a panacea, they could be included in the comparison or as control variates

The first talk by Mathias Rousset was investigating adaptive multilevel sampling, a form of nested sampler, at the theoretical level, while the third talk by Tobias Grafke was a repetition of a talk he gave at the masterclass the interface between computational physics and computational statistics, last April.

telescope on evidence for graphical models

Posted in Books, Statistics, University life with tags , , , , , , , , , on February 29, 2024 by xi'an

A recent paper on evidence by Anindya Bhadra, Ksheera Sagar, Sayantan Banerjee (whom I met during Rito’s seminar, since he was also visiting Ismael in Paris, and who mentioned this work), and Jyotishka Datta, on computing the evidence for graphical models. Obtaining an approximation of the evidence attached with a model and a prior on the covariance matrix Ω is a challenge they manage to address in a particularly clever manner.

“the conditional posterior density [of the last column of the covariance matrix] can be evaluated as a product of normal and gamma densities under suitable priors (…) We resolve this [difficulty with the integrated likelihood] by evaluating the required densities in one row or column at a time, and proceeding backwards starting from the p-th row, with appropriate adjustments to Ωp×p at each step via Schur complement. “

Using a telescoping trick, the authors exploit the fact that the decomposition

\log f(y_{1:p})=\log f(y_p|y_{1:p-1},\theta_p)+\log f (y_{1:p-1}|\theta_p)+\log f(\theta_p)-\log f(\theta_p|y_{1:p})

involves a problematic second term that can be ignored by successive cancellations, as shown by Figure 1. The other terms are manageable for some classes of priors on Ω. Like a Wishart. This allows them to call for Chib’s (two-black) method, which requires two independent MCMC runs. Actually, an unfortunate aspect of the approach is that its computational complexity is of order O(M p⁵), where M is the number of MCMC samples, due to the telescopic trick involving calling Chib’s approach for each of the p columns of Ω. While the numerical outcomes compare with nested sampling, annealed importance sampling, and even harmonic mean estimates (!), the computing time usually exceeds those for these other methods, esp. harmonic mean estimates For the specific G-Wishart case, the solution proposed by Atay-Kayis and Massam (2005) proves far superior. Since the main purpose of using evidence is in deriving Bayes factors, I wonder at possible gains in recycling simulations between models, even though this would seem to call for bridge sampling, no considered in the paper.

reciprocal importance sampling

Posted in Books, pictures, Statistics with tags , , , , , , , , , on May 30, 2023 by xi'an

In a recent arXival, Metodiev et al. (including my friend Adrian Raftery, who is spending the academic year in Paris) proposed a new version of reciprocal importance sampling, expanding the proposal we made with Darren Wraith (2009) of using a Uniform over an HPD region. It is called THAMES, hence the picture (of London, not Paris!), for truncated harmonic mean estimator.

“…[Robert and Wraith (2009)] method has not yet been fully developed for realistic, higher-dimensional situations. For example, we know of no simple way to compute the volume of the convex hull of a set of points in higher dimensions.”

They suggest replacing the convex hull of the HPD points with an ellipsoid ϒ derived from a Normal distribution centred at the highest of the HPD points, whose covariance matrix is estimated from the whole (?) posterior sample. Which is somewhat surprising in that this ellipsoid may as well included low probability regions when the posterior is multimodal. For instance, the estimator is biased when the posterior cancels on parts of ϒ. And with an unclear fate for the finiteness of its variance, depending on how fast the posterior gets to zero on these parts.

The central feature of the paper is selecting the radius of the ellipse that minimises the variance of the (counter) evidence. Under asymptotic normality of the posterior. This radius roughly corresponds to our HPD region in that 50% of the sample stands within. The authors also notice that separate samples should be used to estimate the ellipse and to estimate the evidence. And that a correction is necessary when the posterior support is restricted. (Examples do not include multimodal targets, apparently.)