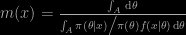Archive for label switching

mixture models [book review]

Posted in Books, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , , , , on August 14, 2024 by xi'an

Strangely enough, I became aware of this new book on mixtures through one of these annoying emails “Your work has been cited n times this week“… Mixture Models (Parametric, Semiparametric, and New Directions) by Weixin Yao and Sijia Wang got published by CRC Press earlier this year, within the Monographs on Statistics and Applied Probability green series (#175), and covers across 380 pages most aspects of mixture (and hidden Markov) estimation, if with strong emphasis on maximum likelihood estimation, while the new directions are unsurprisingly those pursued by the authors, namely robust and semi-parametric estimation, as well as model selection by testing.

An early warning about this book review is that I co-edited a Handbook of Mixture Analysis with my friends Sylvia Früwirth-Schnatter and Gilles Celeux a few years ago. I am therefore biased in what I would have included in a new book on the topic, the more because I find the available literature already plentiful, even though the early (1984) book of Titterington et al. that was my entry to the field may have become an historical reference. For instance, Finite Mixtures by McLachlan and Peel (2000) remains relevant, with similar emphasis on maximum likelihood and the EM algorithm, while Sylvia’s Finite Mixture and Markov Switching Models is still a reference to this day.

And an additional warning on me not being a massive fan of semi- and non-parametric estimation in this setting…

Preliminaries that may explain my limited enthusiasm about the book and its limited originality. Not that I found significant errors there (even though “improper priors [do not always] yield improper posteriors” [p.145] as we demonstrated in several papers), however, I had trouble with the uneven pace adopted by the authors that often skim some topics of importance while spending an inconsiderate amount of space on less relevant once. Some items get many bibliographical references, while others do not. For instance, EM receives a lion’s share (see, e..g, Sections 6.6 and 6.7). Or the 12 pages of proof in Chapter 10. Declination of sections into mixtures, mixtures of regressions, multivariate mixtures, hidden Markov models, and so on feels somewhat repetitive. This is particularly the case for the “mixture regression models” chapter.

The book also contains Bayesian entries, with a first introduction (p.105) in the discrete data chapter that precedes the short Bayesian chapter #4 (p.145), the same issue arising for related algorithms like Gibbs (p.107) that “estimate properties of the joint posterior” and MCMC (p.112). Which sort of erases the specificity of a Bayesian approach by reducing it to one item in the toolbox (with the wrong stress on MAP estimates). In this Bayesian chapter, MCMC validation is handled for discrete state spaces while applied in general spaces. The focus is mostly on relabelling for the following label switching chapter, albeit a large collection of methods are compared if not mentioned.

Handing an unknown number of components by hypothesis testing is supported in the next short chapter, although very little is said about reversible jump MCMC. And there is no general discussion on the consistency of these tests, in particular with bootstrap. Or at least on the regularity conditions they request. An puzzling paradox (p.191) is the existence of an unbounded Fisher information of an exponential mixture

\pi\mathcal Exp(1)+(1-\pi)\mathcal Exp(2)

when the weight π is the parameter (and close to 1).

High-dimensional mixtures in Chapter 8 are mostly handled by linear projections in smaller subspaces, which is natural given that they preserve the mixture structure but open a Pandora box of a wide range of proposed methods, again with little comparison available. Except in the R final section opposing several R functions on the same dataset (if unconclusively).

The semi-parametric chapters mention Dirichlet process priors, albeit briefly, but fail to relate to the recent works on using these when inferring about the number of components. Or failing to do so. There is also a very limited connection pointed out with machine learning but little can be gathered from the three page presentation (pp.308-310). These chapters also have significant overlap with the review paper of Xiang et al. (2019) in Statistical Science.

Most chapters end up with an R section, which usually reads as a quick demo of a related R package, like BayesLCA or our own mixtool. Hence not massively helpful beyond pointers to these packages. The numerical illustrations also are unevenly distributed between chapters, from nothing at all to four pages of small font tables on an MSE comparison between more or less robust approaches undertaken by Yu et al. (2020).

The above thus explains why I am not particularly excited about this bibliographical addition to the analysis of mixtures. It does offer a reference for researchers in the field by adding recent references and approaches to the existing books mentioned above, but I could not recommend it as a textbook (as suggested on p.xiii).

[Disclaimer about potential self-plagiarism: this post or an edited version may eventually appear in my Books Review section in CHANCE.]

ABC in Lapland²

Posted in Mountains, pictures, Statistics, University life with tags , , , , , , , , , , , , , , , , , , , , on March 16, 2023 by xi'an

On the second day of our workshop, Aki Vehtari gave a short talk about his recent works on speed up post processing by importance sampling a simulation of an imprecise version of the likelihood until the desired precision is attained, importance corrected by Pareto smoothing¹⁵. A very interesting foray into the meaning of practical models and the hard constraints on computer precision. Grégoire Clarté (formerly a PhD student of ours at Dauphine) stayed on a similar ground of using sparse GP versions of the likelihood and post processing by VB²³ then stir and repeat!

Riccardo Corradin did model-based clustering when the nonparametric mixture kernel is missing a normalizing constant, using ABC with a Wasserstein distance and an adaptive proposal, with some flavour of ABC-Gibbs (and no issue of label switching since this is clustering). Mixtures of g&k models, yay! Tommaso Rigon reconsidered clustering via a (generalised Bayes à la Bissiri et al.) discrepancy measure rather than a true model, summing over all clusters and observations a discrepancy between said observation and said cluster. Very neat if possibly costly since involving distances to clusters or within clusters. Although she considered post-processing and Bayesian bootstrap, Judith (formerly [?] Dauphine)  acknowledged that she somewhat drifted from the theme of the workshop by considering BvM theorems for functionals of unknown functions, with a form of Laplace correction. (Enjoying Lapland so much that I though “Lap” in Judith’s talk was for Lapland rather than Laplace!!!) And applications to causality.

After the (X country skiing) break, Lorenzo Pacchiardi presented his adversarial approach to ABC, differing from Ramesh et al. (2022) by the use of scoring rule minimisation, where unbiased estimators of gradients are available, Ayush Bharti argued for involving experts in selecting the summary statistics, esp. for misspecified models, and Ulpu Remes presented a Jensen-Shanon divergence for selecting models likelihood-freely²², using a test statistic as summary statistic..

Sam Duffield made a case for generalised Bayesian inference in correcting errors in quantum computers, Joshua Bon went back to scoring rules for correcting the ABC approximation, with an importance step, while Trevor Campbell, Iuri Marocco and Hector McKimm nicely concluded the workshop with lightning-fast talks in place of the cancelled poster session. Great workshop, in my most objective opinion, with new directions!

coupling for the Gibbs sampler

Posted in Books, Mountains, pictures, Running, Statistics, Travel, University life with tags , , , , , , , , , , on November 27, 2022 by xi'an

At BNP13, Brian Trippe presented the AISTAT 2022 paper he recently wrote with Tin D. Nguyen and Tamara Broderick. Which made me read their 2021 paper on the topic. There, they note that coupling may prove challenging, which they blame on label switching. Considering a naïve Gibbs sampler on the space of partitions, meaning allocating each data-point to one of the existing partitions or to a singleton, they construct an optimal transport coupling under Hamming distance. Which appears to be achievable in O(NK³log{K}), if K is the maximal number of partitions among both chains. The paper does not goes deeply into the implementation, which involves [to quote] (a) computing the distances between each pair of partitions in the Cartesian product of supports of the Gibbs conditionals and (b) solving the optimal transport problem. Except in the appendix where the book-keeping necessary to achieve O(K²) for pairwise distances and the remaining complexity follows from the standard Orlin’s algorithm. What remains unclear from the paper is that, while the chains couple faster (fastest?), the resulting estimators do not necessarily improve upon budget-equivalent alternatives. (The reason for the failure of the single chain in Figure 2 is hard to fathom.)

BNP13

Posted in Mountains, pictures, Running, Statistics, Travel with tags , , , , , , , , , , , , , , , , on October 28, 2022 by xi'an

BNP13 is set in this incredible location on a massive lake (almost as large as Lac Saint Jean!) facing several tantalizing snow-capped volcanoes… My trip from Paris to Puerto Varas was quite smooth if relatively longish (but I slept close to 8 hours on the first leg and busied myself with Biometrika submissions the rest of the way). Leaving from Paris at midnight proved a double advantage as this was one of the last flights leaving, with hardly anyone in the airport. On Sunday, I arrived early enough to take a quick dip in Lake Llanquihue which was fairly cold and choppy!

Overall the conference is quite exhilarating as all talks are of interest and often covering on-going research. This may be one of the most engaging meetings I have attended in the past years! Plus a refreshing variety of topics and seniority in the speakers.

To start with a bang!, Sonia Petrone (Bocconi) gave a very nice plenary lecture in the most auspicious manner, covering her recent works on Bayesian prediction as an alternative way to run Bayesian inference (in connection with the incoming Read Paper by Fong et al.). She covered so much ground that I got lost before long (jetlag did not help!). However, an interesting feature underlying her talk is that, under exchangeability, the sequence of predictives converges to a random probability measure, a de Finetti way to construct the prior that is based on predictives. Avoiding in a sense the model and the prior on the parameters of that process. (The parameter is derived from the infinite exchangeable [or conditionally iid] sequence, but the sequence of predictives need be defined.) The drawback is that this approach involves infinite sequences, with practical truncation to a finite horizon being an approximation whose precision / error may prove elusive to characterise. The predictive approach also allows to recover a limiting Normal distribution (not a Bernstein-von Mises type!) and hence credible intervals on parameters and distributions.

While this is indeed a BNP conference (!), I was surprised to see lot of talks paying attention to clustering and even to mixtures, with again a recurrent imprecision on the meaning of a cluster. (Maybe this was already the case for BNP11 in Paris but I may have been too busy helping with catering to notice!) For instance, Brian Trippe (MIT) gave a quick intro on his (AISTATS 2022) work on parallel MCMC with coupling. As unbiased MCMC strongly improving upon naïve parallel MCMC relative to the computing cost. With an interesting example where coupling is agnostic to the labeling of random partitions in clustering problems, involving optimal transport, manageable in O(K³log(K)) time when K is the number of clusters.

Another harmonic mean

Posted in Books, Statistics, University life with tags , , , , , , , , on May 21, 2022 by xi'an

Yet another paper that addresses the approximation of the marginal likelihood by a truncated harmonic mean, a popular theme of mine. A 2020 paper by Johannes Reich, entitled Estimating marginal likelihoods from the posterior draws through a geometric identity and published in Monte Carlo Methods and Applications.

The geometric identity it aims at exploiting is that

m(x) = \frac{\int_A \,\text d\theta}{\int_A \pi(\theta|x)\big/\pi(\theta)f(x|\theta)\,\text d\theta}

for any (positive volume) compact set $A$. This is exactly the same identity as in an earlier and uncited 2017 paper by Ana Pajor, with the also quite similar (!) title Estimating the Marginal Likelihood Using the Arithmetic Mean Identity and which I discussed on the ‘Og, linked with another 2012 paper by Lenk. Also discussed here. This geometric or arithmetic identity is again related to the harmonic mean correction based on a HPD region A that Darren Wraith and myself proposed at MaxEnt 2009. And that Jean-Michel and I presented at Frontiers of statistical decision making and Bayesian analysis in 2010.

In this avatar, the set A is chosen close to an HPD region, once more, with a structure that allows for an exact computation of its volume. Namely an ellipsoid that contains roughly 50% of the simulations from the posterior (rather than our non-intersecting union of balls centered at the 50% HPD points), which assumes a Euclidean structure of the parameter space (or, in other words, depends on the parameterisation)In the mixture illustration, the author surprisingly omits Chib’s solution, despite symmetrised versions avoiding the label (un)switching issues. . What I do not get is how this solution gets around the label switching challenge in that set A remains an ellipsoid for multimodal posteriors, which means it either corresponds to a single mode [but then how can a simulation be restricted to a “single permutation of the indicator labels“?] or it covers all modes but also the unlikely valleys in-between.