Archive for label switching

Overfitting Bayesian mixture models with an unknown number of components

Posted in Statistics with tags , , , , , , , , on March 4, 2015 by xi'an

During my Czech vacations, Zoé van Havre, Nicole White, Judith Rousseau, and Kerrie Mengersen1 posted on arXiv a paper on overfitting mixture models to estimate the number of components. This is directly related with Judith and Kerrie’s 2011 paper and with Zoé’s PhD topic. The paper also returns to the vexing (?) issue of label switching! I very much like the paper and not only because the author are good friends!, but also because it brings a solution to an approach I briefly attempted with Marie-Anne Gruet in the early 1990’s, just before finding about the reversible jump MCMC algorithm of Peter Green at a workshop in Luminy and considering we were not going to “beat the competition”! Hence not publishing the output of our over-fitted Gibbs samplers that were nicely emptying extra components… It also brings a rebuke about a later assertion of mine’s at an ICMS workshop on mixtures, where I defended the notion that over-fitted mixtures could not be detected, a notion that was severely disputed by David McKay…

What is so fantastic in Rousseau and Mengersen (2011) is that a simple constraint on the Dirichlet prior on the mixture weights suffices to guarantee that asymptotically superfluous components will empty out and signal they are truly superfluous! The authors here cumulate the over-fitted mixture with a tempering strategy, which seems somewhat redundant, the number of extra components being a sort of temperature, but eliminates the need for fragile RJMCMC steps. Label switching is obviously even more of an issue with a larger number of components and identifying empty components seems to require a lack of label switching for some components to remain empty!

When reading through the paper, I came upon the condition that only the priors of the weights are allowed to vary between temperatures. Distinguishing the weights from the other parameters does make perfect sense, as some representations of a mixture work without those weights. Still I feel a bit uncertain about the fixed prior constraint, even though I can see the rationale in not allowing for complete freedom in picking those priors. More fundamentally, I am less and less happy with independent identical or exchangeable priors on the components.

Our own recent experience with almost zero weights mixtures (and with Judith, Kaniav, and Kerrie) suggests not using solely a Gibbs sampler there as it shows poor mixing. And even poorer label switching. The current paper does not seem to meet the same difficulties, maybe thanks to (prior) tempering.

The paper proposes a strategy called Zswitch to resolve label switching, which amounts to identify a MAP for each possible number of components and a subsequent relabelling. Even though I do not entirely understand the way the permutation is constructed. I wonder in particular at the cost of the relabelling.

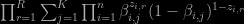
trans-dimensional nested sampling and a few planets

Posted in Books, Statistics, Travel, University life with tags , , , , , , , , , on March 2, 2015 by xi'an

This morning, in the train to Dauphine (train that was even more delayed than usual!), I read a recent arXival of Brendon Brewer and Courtney Donovan. Entitled Fast Bayesian inference for exoplanet discovery in radial velocity data, the paper suggests to associate Matthew Stephens’ (2000)  birth-and-death MCMC approach with nested sampling to infer about the number N of exoplanets in an exoplanetary system. The paper is somewhat sparse in its description of the suggested approach, but states that the birth-date moves involves adding a planet with parameters simulated from the prior and removing a planet at random, both being accepted under a likelihood constraint associated with nested sampling. I actually wonder if this actually is the birth-date version of Peter Green’s (1995) RJMCMC rather than the continuous time birth-and-death process version of Matthew…

“The traditional approach to inferring N also contradicts fundamental ideas in Bayesian computation. Imagine we are trying to compute the posterior distribution for a parameter a in the presence of a nuisance parameter b. This is usually solved by exploring the joint posterior for a and b, and then only looking at the generated values of a. Nobody would suggest the wasteful alternative of using a discrete grid of possible a values and doing an entire Nested Sampling run for each, to get the marginal likelihood as a function of a.”

This criticism is receivable when there is a huge number of possible values of N, even though I see no fundamental contradiction with my ideas about Bayesian computation. However, it is more debatable when there are a few possible values for N, given that the exploration of the augmented space by a RJMCMC algorithm is often very inefficient, in particular when the proposed parameters are generated from the prior. The more when nested sampling is involved and simulations are run under the likelihood constraint! In the astronomy examples given in the paper, N never exceeds 15… Furthermore, by merging all N’s together, it is unclear how the evidences associated with the various values of N can be computed. At least, those are not reported in the paper.

The paper also omits to provide the likelihood function so I do not completely understand where “label switching” occurs therein. My first impression is that this is not a mixture model. However if the observed signal (from an exoplanetary system) is the sum of N signals corresponding to N planets, this makes more sense.

relabelling mixtures (#2)

Posted in Statistics, Travel, University life with tags , , , , , , on February 5, 2015 by xi'an

Following the previous post, I went and had  a (long) look at Puolamäki and Kaski’s paper. I must acknowledge that, despite having several runs through the paper, I still have trouble with the approach… From what I understand, the authors use a Bernoulli mixture pseudo-model to reallocate the observations to components.  That is, given an MCMC output with simulated allocations variables (a.k.a., hidden or latent variables), they create a (TxK)xn matrix of component binary indicators e.g., for a three component mixture,

0 1 0 0 1 0…
1 0 0 0 0 0…
0 0 1 1 0 1…
0 1 0 0 1 1…

and estimate a probability to be in component j for each of the n observations, according to the (pseudo-)likelihood

\prod_{r=1}^R \sum_{j=1}^K \prod_{i=1}^n \beta_{i,j}^{z_{i,r}}(1-\beta_{i,j})^{1-z_{i,r}}

It took me a few days, between morning runs and those wee hours when I cannot get back to sleep (!), to make some sense of this Bernoulli modelling. The allocation vectors are used together to estimate the probabilities of being “in” component j together. However the data—which is the outcome of an MCMC simulation and de facto does not originate from that Bernoulli mixture—does not seem appropriate, both because it is produced by an MCMC simulation and is made of blocks of highly correlated rows [which sum up to one]. The Bernoulli likelihood above also defines a new model, with many more parameters than in the original mixture model. And I fail to see why perfect, partial or inexistent label switching [in the MCMC sequence] is not going to impact the estimation of the Bernoulli mixture. And why an argument based on a fixed parameter value (Theorem 3) extends to an MCMC outcome where parameters themselves are subjected to some degree of label switching. Bemused, I remain…

relabelling mixtures

Posted in Books, Statistics with tags , , , , , , on January 30, 2015 by xi'an

Another short paper about relabelling in mixtures was arXived last week by Pauli and Torelli. They refer rather extensively to a previous paper by Puolamäki and Kaski (2009) of which I was not aware, paper attempting to get an unswitching sampler that does not exhibit any label switching, a concept I find most curious as I see no rigorous way to state that a sampler is not switching! This would imply spotting low posterior probability regions that the chain would cross. But I should check the paper nonetheless.

Because the G component mixture posterior is invariant under the G! possible permutations, I am somewhat undeciced as to what the authors of the current paper mean by estimating the difference between two means, like μ1-μ2. Since they object to using the output of a perfectly mixing MCMC algorithm and seem to prefer the one associated with a non-switching chain. Or by estimating the probability that a given observation is from a given component, since this is exactly 1/G by the permutation invariance property. In order to identify a partition of the data, they introduce a loss function on the joint allocations of pairs of observations, loss function that sounds quite similar to the one we used in our 2000 JASA paper on the label switching deficiencies of MCMC algorithms. (And makes me wonder why this work of us is not deemed relevant for the approach advocated in the paper!) Still, having read this paper, which I find rather poorly written, I have no clear understanding of how the authors give a precise meaning to a specific component of the mixture distribution. Or how the relabelling has to be conducted to avoid switching. That is, how the authors define their parameter space. Or their loss function. Unless one falls back onto the ordering of the means or the weights which has the drawback of not connecting with the levels sets of a particular mode of the posterior distribution, meaning that imposing the constraints result in a region that contains bits of several modes.

At some point the authors assume the data can be partitioned into K≤G groups such that there is a representative observation within each group never sharing a component (across MCMC iterations) with any of the other representatives. While this notion is label invariant, I wonder whether (a) this is possible on any MCMC outcome; (b) it indicates a positive or negative feature of the MCMC sampler.; and (c) what prevents the representatives to switch in harmony from one component to the next while preserving their perfect mutual exclusion… This however constitutes the advance in the paper, namely that component dependent quantities as estimated as those associated with a particular representative. Note that the paper contains no illustration, hence that the method may prove hard to impossible to implement!

Robert’s paradox [reading in Reading]

Posted in Statistics, Travel, University life with tags , , , , , , , , , , , , on January 28, 2015 by xi'an

paradoxOn Wednesday afternoon, Richard Everitt and Dennis Prangle organised an RSS workshop in Reading on Bayesian Computation. And invited me to give a talk there, along with John Hemmings, Christophe Andrieu, Marcelo Pereyra, and themselves. Given the proximity between Oxford and Reading, this felt like a neighbourly visit, especially when I realised I could take my bike on the train! John Hemmings gave a presentation on synthetic models for climate change and their evaluation, which could have some connection with Tony O’Hagan’s recent talk in Warwick, Dennis told us about “the lazier ABC” version in connection with his “lazy ABC” paper, [from my very personal view] Marcelo expanded on the Moreau-Yoshida expansion he had presented in Bristol about six months ago, with the notion that using a Gaussian tail regularisation of a super-Gaussian target in a Langevin algorithm could produce better convergence guarantees than the competition, including Hamiltonian Monte Carlo, Luke Kelly spoke about an extension of phylogenetic trees using a notion of lateral transfer, and Richard introduced a notion of biased approximation to Metropolis-Hasting acceptance ratios, notion that I found quite attractive if not completely formalised, as there should be a Monte Carlo equivalent to the improvement brought by biased Bayes estimators over unbiased classical counterparts. (Repeating a remark by Persi Diaconis made more than 20 years ago.) Christophe Andrieu also exposed some recent developments of his on exact approximations à la Andrieu and Roberts (2009).

Since those developments are not yet finalised into an archived document, I will not delve into the details, but I found the results quite impressive and worth exploring, so I am looking forward to the incoming publication. One aspect of the talk which I can comment on is related to the exchange algorithm of Murray et al. (2006). Let me recall that this algorithm handles double intractable problems (i.e., likelihoods with intractable normalising constants like the Ising model), by introducing auxiliary variables with the same distribution as the data given the new value of the parameter and computing an augmented acceptance ratio which expectation is the targeted acceptance ratio and which conveniently removes the unknown normalising constants. This auxiliary scheme produces a random acceptance ratio and hence differs from the exact-approximation MCMC approach, which target directly the intractable likelihood. It somewhat replaces the unknown constant with the density taken at a plausible realisation, hence providing a proper scale. At least for the new value. I wonder if a comparison has been conducted between both versions, the naïve intuition being that the ratio of estimates should be more variable than the estimate of the ratio. More generally, it seemed to me [during the introductory part of Christophe’s talk] that those different methods always faced a harmonic mean danger when being phrased as expectations of ratios, since those ratios were not necessarily squared integrable. And not necessarily bounded. Hence my rather gratuitous suggestion of using other tools than the expectation, like maybe a median, thus circling back to the biased estimators of Richard. (And later cycling back, unscathed, to Reading station!)

On top of the six talks in the afternoon, there was a small poster session during the tea break, where I met Garth Holloway, working in agricultural economics, who happened to be a (unsuspected) fan of mine!, to the point of entitling his poster “Robert’s paradox”!!! The problem covered by this undeserved denomination connected to the bias in Chib’s approximation of the evidence in mixture estimation, a phenomenon that I related to the exchangeability of the component parameters in an earlier paper or set of slides. So “my” paradox is essentially label (un)switching and its consequences. For which I cannot claim any fame! Still, I am looking forward the completed version of this poster to discuss Garth’s solution, but we had a beer together after the talks, drinking to the health of our mutual friend John Deely.